Take a checklist of thirty-two requirements. Each requirement gets a yes or a no, judged against a few passages retrieved for it from the documents under review. A compliance check has this shape. So does a rubric grader, a security questionnaire, and more than one “does this document satisfy the policy” feature I have worked on. A language model judges one requirement well. The question is how many model calls to make. There are three obvious answers: one call for the whole list, thirty-two calls of one requirement each, or about seven calls of one group each.
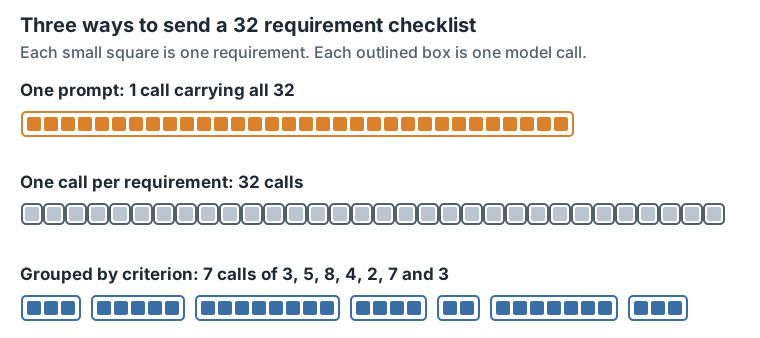
Figure 1. The three shapes compared in this post.
I chose seven. The first time, I treated that as one decision, but it is two. Grouping the judgments into fewer model calls means the retrieval that feeds them has to be split into more, narrower queries. Model calls fall by a factor of 4.57. Retrieval queries rise by a factor of 13.7. The rule behind both: batch the operation that is expensive, slow to answer and unreliable, and fan out the one that is cheap and deterministic.
One prompt for the whole checklist
One call means one round trip, one response to validate, one retry policy and one trace to read. If you cache the shared start of the prompt, repeating the context is cheap. The model also sees the whole file at once. It can notice that the evidence settling requirement 19 also settles requirement 4, which thirty-two isolated calls cannot do. If your evaluator is cheap per token and your list is short, the single prompt is the right answer. The simulation below agrees, for one setting of its parameters.
For every other setting, the big prompt has two costs that a token count does not show. The model reads a long input unevenly, and one failure takes the whole run with it.
Liu and colleagues measured the uneven reading. In their multi-document question answering task, GPT-3.5-Turbo with a 16K window scored 73.4 percent when the document holding the answer was the first of thirty (index 0). It scored 50.5 percent when that document was the tenth (index 9). Given only the document with the answer, it scored 88.6 percent. Given no documents at all, it scored 56.0 percent. So with the answer in the middle of thirty documents, the model did worse than when it answered from memory alone.
Levy, Jacoby and Goldberg tested input length directly. They kept the reasoning task fixed and padded the input to different lengths. They report that performance degrades “at much shorter input lengths than their technical maximum”. A context window large enough to hold the input does not mean the model reads all of it.
A 32 requirement prompt is a document with a long middle. The requirements in that middle get answered carelessly. You are unlikely to notice, because a plausible verdict and a careful one look the same in the response.
One call per requirement
The opposite design is thirty-two calls, each with one requirement and a short prompt. It looks like the safest design: each call is simple. But a run now waits for thirty-two calls, and that brings in a known problem from distributed systems: tail latency, the rare responses that take far longer than the typical one.
Dean and Barroso described it in 2013. Take a server that usually responds in 10ms, but whose 99th percentile latency is one second. “If a user request is handled on just one such server, one user request in 100 will be slow (one second).” Then the consequence: “If a user request must collect responses from 100 such servers in parallel, then 63% of user requests will take more than one second.”
This is exact arithmetic. If each call is slow with probability 0.01, a run of n calls contains at least one slow call with probability 1 minus 0.99 to the power n. My reproduction script gives 63.40 percent for 100 calls, the paper’s 63 percent.
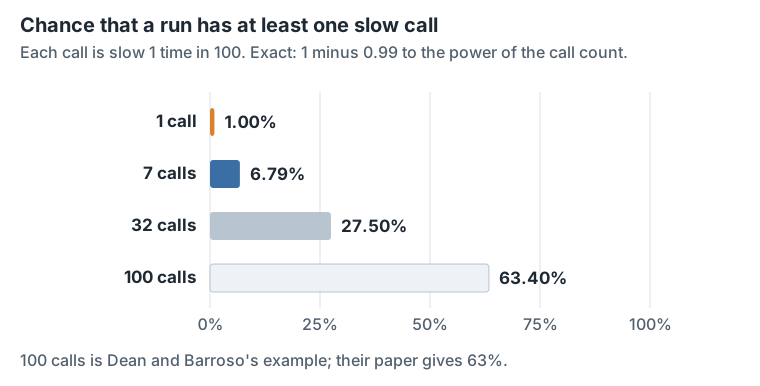
Figure 2. More calls per run, more runs that contain a slow call.
Fanning out does not make any single call slower. It raises the chance that a run contains a slow call. A delay that hits one call in a hundred hits more than one run in four once each run depends on thirty-two calls.
Seven calls, one per criterion
The checklist I have in mind is a public French national quality framework for training providers. Until 1 November 2026 it has 32 requirements, which its own authority splits into 7 criteria; the version that applies from that date has 33. I did not choose the split, and the criteria are not equal in size.
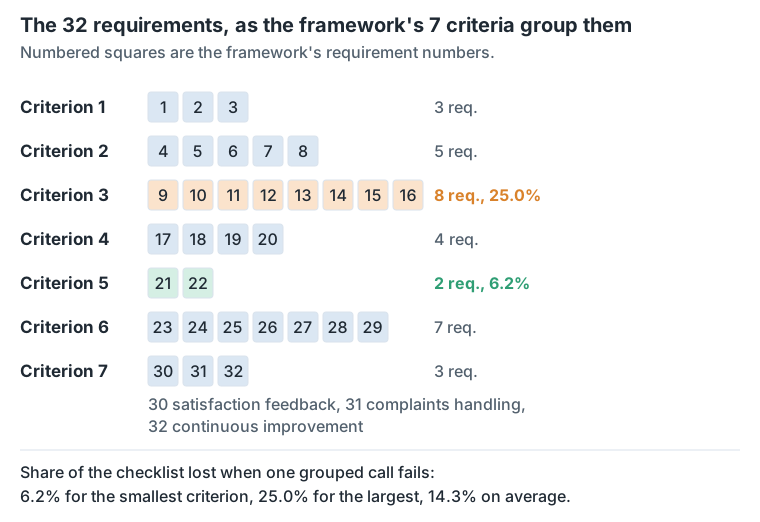
Figure 3. The framework’s 32 requirements in its 7 criteria, as listed on the public home page of auditmalin.com, which needs no account.
The largest criterion has eight requirements and the smallest has two. Both numbers matter.
- Run time. With a fixed number of workers, the longest call sets a floor on the total run time. So the speed gain is capped by the largest criterion, not the average one. Halving the average group would not help; splitting the biggest would.
- Blast radius, the share of the checklist lost when one call fails. Losing the eight requirement call costs 25.0 percent of the checklist. Losing the two requirement call costs 6.2 percent. The mean, 14.3 percent, sits inside a spread that covers a factor of four.
Criterion 7 shows the retrieval problem on a small scale. Its three requirements cover satisfaction feedback, complaints handling and continuous improvement: three topics that a single embedding query will easily mix up. I come back to it in the retrieval section.
Setup: a seeded simulation
To compare the three shapes I wrote a small simulator in Python. It uses a fixed random seed, so every run gives the same numbers. Its inputs are declared assumptions, not measurements:
- A call takes 2.0 seconds plus 0.6 seconds per requirement it carries, times random noise. The noise is lognormal with sigma 0.35: a multiplier usually close to 1, and above 1.8 one time in twenty, which gives the slow tail.
- A call fails with probability 0.02.
- The single prompt runs on its own. The other two shapes share a pool of four workers, because the real limit is usually a provider’s rate limit, not your hardware.
- Each shape is run 20,000 times.
The scheduler decides how the calls share the four workers:
def wall_clock(durations: list[float], workers: int) -> float:
    """Makespan of `durations` on `workers` servers, submitted in the given order."""
    if workers >= len(durations):
        return max(durations)
    free_at = [0.0] * workers
    for d in durations:
        i = min(range(workers), key=lambda k: free_at[k])
        free_at[i] += d
    return max(free_at)
Each call goes to the worker that frees up first. With at least as many workers as calls, the run takes as long as its slowest call. With fewer workers, it takes the makespan: the time until the last queued call finishes. That is much closer to the sum of all call times divided by the number of workers. Thirty-two calls through four workers run as a queue, four at a time.
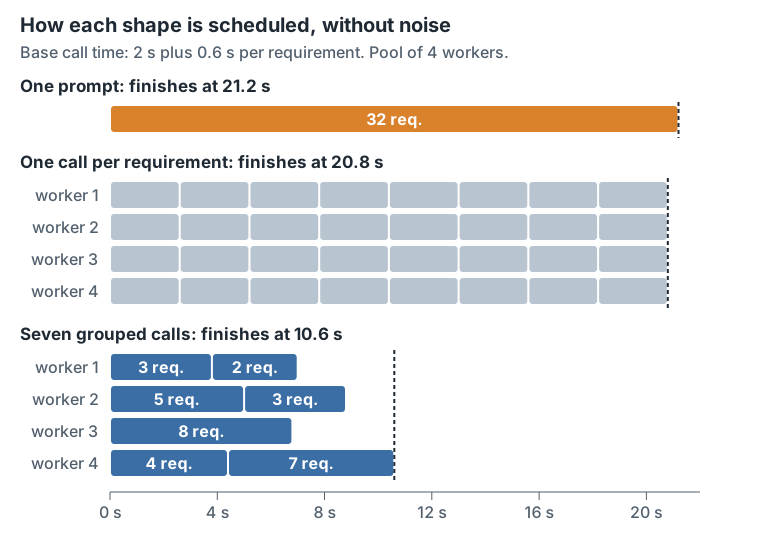
Figure 4. The scheduler above with the noise switched off, so every call takes its base time. The simulation repeats this 20,000 times with noise.
Results: run time
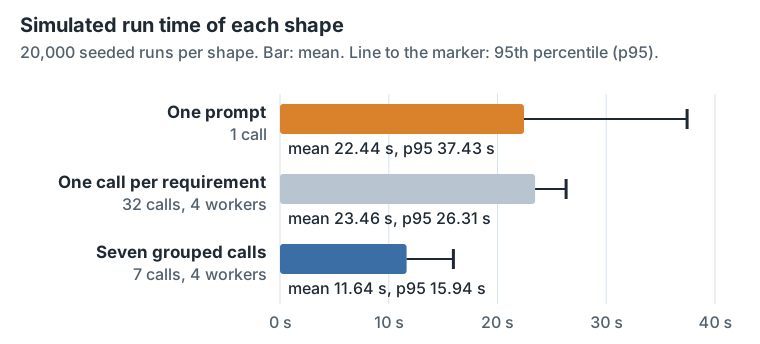
Figure 5. Under this cost model the grouped shape is the fastest of the three. “p95” is the 95th percentile: the time within which 95 runs in 100 finish.
Two results surprised me. The per-requirement shape is the slowest on average, because a bounded pool turns its fan-out back into a sum. And the single call has by far the worst tail: 37.43 seconds at p95 against a mean of 22.44. All of the run’s timing noise sits in one draw, instead of averaging out across seven calls.
Results: the fastest shape depends on one assumption
Thirty-two divided by seven is 4.57. That is a count of requests that anyone can check, and a claim I will defend in a review.
“4.5 times faster” would be a different claim. I could only make it after timing both shapes against the same evaluator on the same evidence. Call count is a property of your code. Latency is a property of the whole system: the provider’s queue, your rate limit, the token count of each prompt, and the time of day.
My own simulator shows this. Change one assumption, the extra seconds each requirement adds to its call, and the ranking changes:
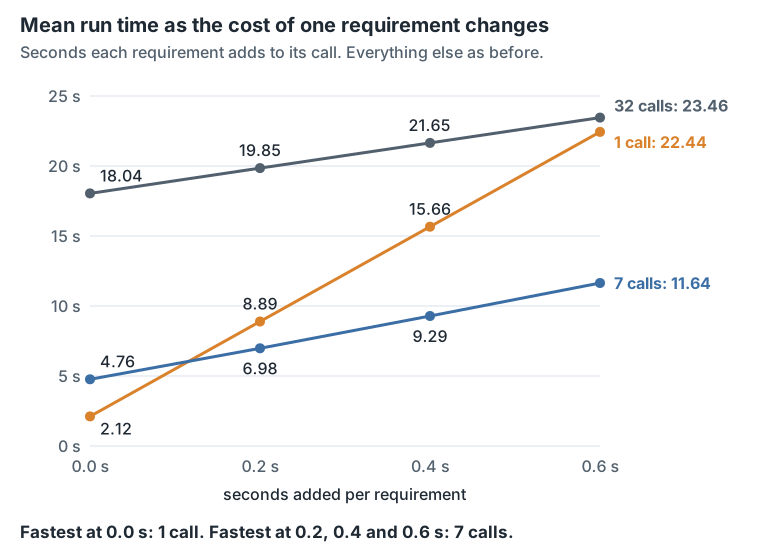
Figure 6. The same 20,000 seeded runs per point, with only the cost per requirement changed.
If a requirement adds nothing to the time of its call, the single prompt is the fastest: 2.12 seconds against 4.76 for the grouped shape, more than twice as fast. Its only problem is then blast radius. At 0.2, 0.4 and 0.6 seconds per requirement, the grouped shape is the fastest. One unmeasured parameter decides which shape is fastest. It does not decide which shape is safest.
Results: what one failure costs
On average, the share of the checklist left unverified per run is 2.0 percent for the single call, 2.0 percent for the per-requirement shape and 2.1 percent for the grouped shape. The 2.1 differs only by sampling noise over twenty thousand runs. In expectation the loss is exactly the per-call failure rate, 2 percent, for all three shapes. This follows from linearity of expectation: every requirement sits in exactly one call, and every call fails with the same probability, so grouping cannot change the average. It changes how the loss is spread across runs.
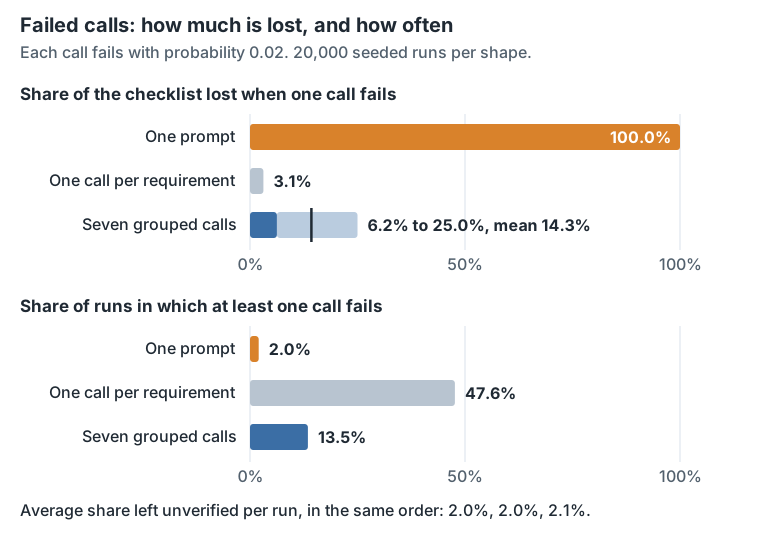
Figure 7. Same average loss, spread differently. For the grouped shape the loss per failed call is a range, because the criteria differ in size.
The single call rarely fails, but then loses everything. The per-requirement shape loses something in almost half of all runs, but only one requirement per failed call. The grouped shape sits between. A run that returns thirty-one verdicts and one honest “not verified” can be finished by hand in a minute. A run that returns nothing has to be run again, and can end in a refund and a support ticket.
So I chose the grouping for its failure behaviour first and for speed second. It also shipped in that order: the grouping landed while the calls still ran one after another, and the worker pool came later.
The grouped shape is what runs behind auditmalin.com, whose home page lists the framework in Figure 3. The number I state about it is the call count, because that is the number I can count.
Retrieval for a grouped call
A grouped call is only as good as the evidence you give it. The simple way to gather that evidence is one retrieval per group: turn the criterion into a query, keep the top k passages (the k closest matches in the vector search), and pass them on. I built this first. It fails for a reason that has nothing to do with ranking quality.
A requirement is not one question. It breaks down into mandatory control points: the actor, the timing, the artefact, the trace. Assume three per requirement. A group of eight requirements then asks twenty-four control questions. A retrieval that returns five passages can supply dedicated evidence for at most five of them. The other nineteen get none. This is counting, so it holds even for a perfect retriever. A better embedding model does not change it, and neither does a reranker.
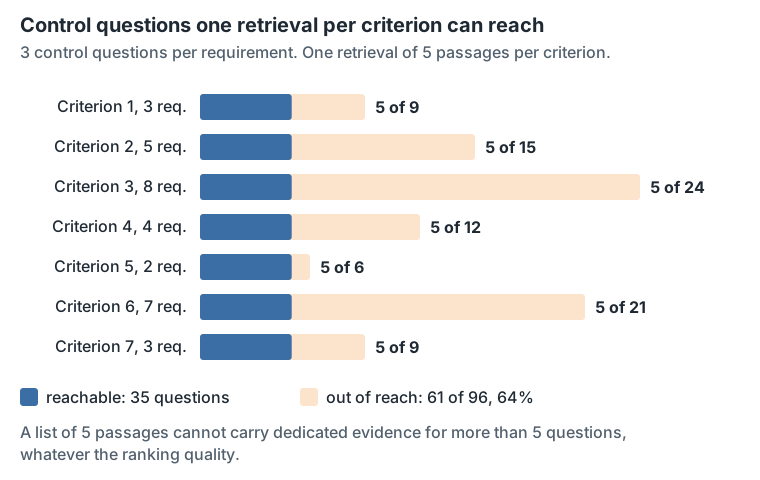
Figure 8. Retrieving once per group starves the large groups, and the large groups are the ones that grouping puts in one call. Across the checklist, 61 of 96 control questions are out of reach before the ranker does anything.
Back to the last criterion: satisfaction feedback, complaints handling, continuous improvement. One query over that group returns five passages about satisfaction surveys, because satisfaction is the dominant word. The complaints procedure never enters the prompt. The model then does one of two things, and both are bad. It reports no evidence for complaints handling, which the customer reads as a finding against them. Or it stretches a satisfaction document to cover complaints, which looks like a verdict but is a guess.
The fix keeps the seven calls and changes what goes into them:
- Retrieve per requirement, then per mandatory control inside it.
- Remove duplicate passages across controls, but record which control each passage matched.
- Give the grouped call a structured evidence matrix, passages by requirement and control, instead of a flat list.
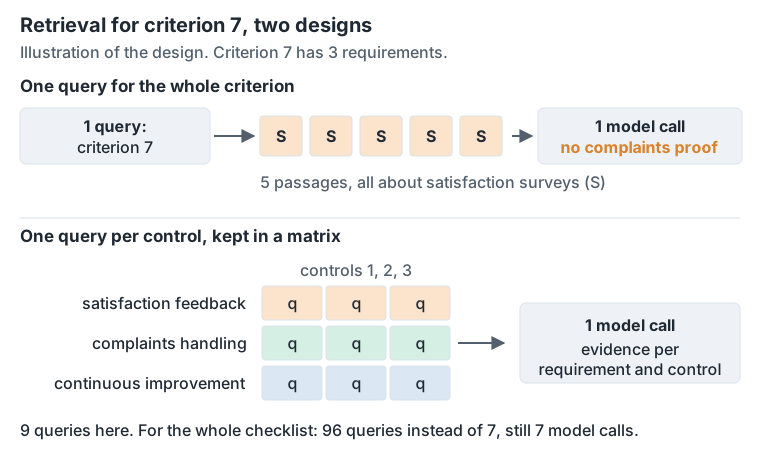
Figure 9. One query per criterion against one query per control, for criterion 7.
The call count does not change. The retrieval count goes from 7 to 96, a factor of 13.7, while model calls fall by a factor of 4.57 against the per-requirement shape.
The two operations have opposite costs. A vector search takes milliseconds, gives the same answer every time, is safe to repeat and costs almost nothing. A model call takes seconds, varies from run to run, is sometimes malformed and is billed. So the model calls are batched and the searches are fanned out. A pipeline that batches both, or fans out both, applies one policy to two operations with opposite costs.
It also pushes the token bill up. Ninety-six retrievals surface more distinct passages than seven do. Removing duplicates only partly offsets that, and a passage matching two controls in two groups is sent twice. So the design has fewer calls and more tokens.
Filtering inside the search
Once retrieval is fine grained, every query carries constraints: this requirement, this tenant, evidence rather than reference material. You can apply them after the search or inside it, and the two are not equivalent.
Filtering after the search silently shrinks your top k. Ask for ten, discard six that fail the constraint, and the model judges on four. Nothing records that the real k for that control was four, least of all the offline metric that assumed ten. Filtering inside the search asks for ten matching passages and gets ten.
That has a cost that only shows up in production. In Qdrant, the vector database here, a filter on the fields stored with each vector is a payload filter, and it needs a payload index. Qdrant’s documentation says payload indexes “speed up filtering” and “should be created before ingesting data”. A managed cluster can be set to refuse filters on fields without an index, because such a filter “can be very slow”. The strict mode setting unindexed_filtering_retrieve does this. A cluster set that way rejects the query with a 400 error that names the field and the index type it wanted.
This cost me an afternoon. The test suite was self-contained and ran against Qdrant’s in-memory client. That client did not implement payload indexes. It applied the filter in Python, and when asked to create an index it warned that “Payload indexes have no effect in the local Qdrant”. Since qdrant-client 1.20.0 (October 2026), text indexes with scoring are the one exception. The filter worked in every test, on every machine, and failed on the first real request to the hosted cluster.
The same holds beyond vector stores. A test stand-in that accepts what the real backend refuses is worse than no test, because it turns a missing precondition into a passing suite. A precondition that exists only on the server, such as an index, a quota, a permission or a schema version, is only tested when you test against a server.
An embedding model chosen by an API key
The same gap between tests and production had a quieter form. Dense embeddings, the vectors used for search, came from a hosted model when an API key was present, and from a local model otherwise. That is a reasonable default, except that the key in question is the one the language model needs. The product cannot run without it. So production always ran hosted embeddings with 1536 dimensions, and the test suite always ran local embeddings with 384.
The loud failure: a collection built with 384 dimensions and queried with 1536. It showed up as an unclear error at write time, until the dimension check moved into collection setup, where it belongs.
The quiet failure: every retrieval number measured offline came from a different embedding model than the one serving users. Recall at five, measured locally, described a model that never ran in production. Choosing an embedding model is a modelling decision. Here it was made as a side effect of a credential, so nobody reviewed it.
A grouped call can skip a requirement
This failure only happens when several requirements share one call.
Give a model six requirements in one call, ask for six verdicts, and sometimes you get five. There is no error: five well formed, confident verdicts in a valid response. Schema enforcement does not catch this. A schema saying the response holds a list of results is satisfied by a list of five. OpenAI’s documentation describes Structured Outputs as a feature “that ensures the model will always generate responses that adhere to your supplied JSON Schema”. The same page says that “in some cases, the model might not generate a valid response that matches the provided JSON schema”. Even when it works, the guarantee is about structure only. Nothing in a JSON schema knows which six requirement identifiers you asked about.
The worse part was what the pipeline did with the omission. The code that handled a missing requirement turned it into the most severe non-conformity the domain has, with an empty justification. That verdict went into the report and into the score. An earlier version was worse: one unparseable response downgraded a whole group at once. So when a model stopped halfway through a list, the visible result was a severe compliance finding against a customer, produced by the error handler, with nothing to cite.
So the damage from a grouped call that skips a requirement includes whatever your code does with the missing verdict. Here the error handler filled in the value that was easiest to type, not the true one.
The repair:
- Send the requirement identifiers and require them back.
- Compare the returned set with the requested set.
- Retry once, naming the missing identifiers.
- If they are still missing, mark them “not verified”. Not a pass, because nothing was verified. Not a failure, because the requirement was never judged.
- Leave “not verified” out of the score’s denominator, so an engineering defect is not counted as the customer’s problem.
At an assumed omission rate of 5 percent per requirement, a grouped run over 32 requirements leaves 1.6 of them unanswered on average. I invented that rate, and the 1.6 moves with it. The difference between the shapes does not: a call carrying one requirement cannot skip it quietly. Its omission is an empty response, and an empty response is easy to detect.
Checking citations in code
Asking the model to cite its evidence gets you a non-empty field. That field can hold a filename, a section label, or a fluent sentence that appears nowhere in your documents. A check for “is this list non-empty” passes all three.
To make citation a guarantee, run a deterministic check after the response comes back:
- Give every passage a stable identifier before it enters the prompt, and require the verdict to name identifiers.
- Accept the verdict only if those identifiers were among the passages retrieved for that specific requirement, or if the quoted text appears word for word in that requirement’s evidence.
- Retry a verdict that fails, then downgrade it to “not verified”.
Grouping is what makes “for that specific requirement” matter. In a per-requirement call, the scoping is free: one requirement, one pool of evidence. In a grouped call, one response carries six verdicts over a shared pool of passages. A model that judged requirement four using a passage retrieved for requirement nine produces a citation that passes against the pool but is wrong for the requirement. Recording which control each passage was retrieved for lets the check reject it. That record only exists because retrieval was split per control.
Limits
- The latency model is invented. A fixed overhead, plus a cost per requirement, times lognormal noise, is a plausible shape, not a measurement of any provider. Figure 6 is there because the conclusion depends on it.
- The retrieval inputs are assumptions. The arithmetic is exact, but I chose three mandatory controls per requirement and a top k of five. The result to keep is the inequality, that one retrieval of five passages cannot cover more than five controls, not the 61 of 96. Change either input and the count moves, though its direction does not.
- The simulated failures are independent, and real ones are not. A rate limit, a provider incident or a malformed shared preamble hits every call in the run at once, and failures that strike together erase most of the isolation that grouping buys.
- Grouping assumes the groups are real. Seven groups of unrelated requirements are just seven smaller big prompts: they mix unrelated material, as the big prompt does, and get none of the benefit of shared context. Here the split came from the standard itself, which is the easy case.
- Retrieval cost is not in the latency model. Ninety-six vector queries against a remote store give the new fan-out a slow tail of its own.
Open question
The grouping is static: it follows the structure of the checklist, not the structure of the evidence. The requirements that actually share retrieved passages may cut across it. A grouping built from retrieval overlap would batch the calls that benefit from seeing each other’s evidence, and split the ones that do not. It would also make the blast radius depend on the data and change on every run, which makes an incident hard to reason about. I do not know which effect is larger.
Sources
- Nelson F. Liu, Kevin Lin, John Hewitt, Ashwin Paranjape, Michele Bevilacqua, Fabio Petroni and Percy Liang, “Lost in the Middle: How Language Models Use Long Contexts”, with the full text and appendix tables carrying the per-position accuracies quoted above.
- Jeffrey Dean and Luiz Andre Barroso, “The Tail at Scale”, Communications of the ACM 56(2), February 2013.
- Mosh Levy, Alon Jacoby and Yoav Goldberg, “Same Task, More Tokens: the Impact of Input Length on the Reasoning Performance of Large Language Models”.
- OpenAI platform documentation, Structured Outputs, for what schema enforcement does and does not promise.
- Qdrant documentation, Indexing and Administration, for payload indexes and for the strict mode setting that refuses unindexed filtering; and
qdrant_client/local/qdrant_local.pyfor the local mode warning quoted above.