A document authenticity check I had built cleared every file in a small set of genuine documents. Zero false positives. Two days later I ran it on a public labelled benchmark where most of the documents carried a forgery. It cleared those too. Recall was 0.0: not one true positive in the whole set.
The usual advice after a story like this is “ask for recall”. I trust that advice least, because recall is the cheapest number in the confusion matrix to buy. Lower the threshold far enough and recall goes to 1.0 on any labelled set. The review queue then fills with false alarms until the team stops opening it. The detector that gets switched off is rarely the one that misses things quietly. It is the noisy one.
So the usual trade-off is about where to sit on a curve: how many alarms you accept for how much recall. My check had no curve at all, and the synthetic rebuild below shows that as a number. There, the detector reads the file’s container (its structure and metadata, not its pixels). Across 200 documents it produces one distinct score. Every threshold then gives one of exactly two outcomes, and its AUC is exactly 0.500: chance itself, with no rounding.
The check I had never done: write down the question the detector answers and the question the labels ask, one sentence each, and read them side by side. Mine were two different questions. This post shows why, and what I measure now instead.
Why the check missed
A container-level detector reads file-format facts: producer strings, object counts, quantisation tables, revision markers. The forgeries were in the pixels, and the benchmark pages I ran were photographs.
Photographing a printed page does not hide those facts. It replaces the file. The bytes the detector reads afterwards came from a camera, which never had access to the original file. So the fields it inspects belong to a different file. No later processing can recover information the photograph never carried, which is why a better parser would not have helped.
The people who built the strongest container-level technique name this failure themselves. Kee, Johnson and Farid write that their analysis “is also vulnerable to a standard re-broadcast attack in which a digital image is manipulated, printed, and re-photographed.”
My inputs were not adversarial. They were photographed pages, which is how a great deal of real document evidence arrives. Each one was a re-broadcast attack that nobody had carried out on purpose.
Seven families of forensic checks
Document and image forensics has about seven families of checks. Each reads a different physical or file-format quantity. Here they are from the outer layer of the file inwards to the scene in the photograph.
Metadata and file structure reads EXIF, IPTC and XMP fields, and the file’s internal structure: how its parts link together, how many times it was revised, how many end-of-file markers it carries. Its question: what software produced this file, and how many times has it been written? Kee, Johnson and Farid built the strongest version: a 576-value signature from JPEG headers alone, “highly distinct across 1.3 million images spanning 773 different cameras and cellphones”. Their own discussion states the limit: “This analysis does not differentiate between benign and nefarious modifications.”
Compression history reads JPEG quantisation tables and DCT coefficient statistics. It looks for a region that went through a different number of JPEG compressions than the rest, most visibly through the JPEG ghost effect. Its question: were all parts of this image encoded the same number of times, at the same quality? It is blind to an edit made before the first save, and to an edit followed by one uniform re-encode.
Error level analysis is the cheap, popular cousin of compression history. Re-save the image at a fixed quality, take the absolute difference per pixel, and amplify it. Its question: which regions change more than the rest when the image is saved again? It “provides no evidence of manipulation in cases where the edit was applied before the first JPEG save”. It also “cannot distinguish object removal or inpainting from authentic content, because neither operation necessarily disturbs the compression history if done carefully”. Its innocent false alarms are ordinary: in-camera HDR, screenshots, portrait-mode boundaries and resampling all leave a region with a different compression history and no forgery.
Frequency domain statistics learn the statistical signature of tampered text directly. The DocTamper authors added a Frequency Perception Head “to compensate the deficiencies caused by the inconspicuous visual features” of document tampering, because the visible evidence is not there to find. The weakness of this family is block alignment. DCT traces are tied to JPEG’s 8 by 8 grid, so a resize or a crop that shifts the grid degrades them. The 2025 ADCD-Net work exists largely to handle that. It weights the DCT input by a predicted alignment score, to stay robust “to various distortions, including resizing and cropping”.
Sensor noise reads photo-response non-uniformity (PRNU): a multiplicative fingerprint left by small manufacturing differences across the camera sensor. Its question: was every pixel of this image produced by the same physical sensor? It is the only family that reaches past the file to the device, and the most demanding. It needs a reference: the camera, or known-good images from it. Its signal sits in the high-frequency band that lossy compression is designed to discard, and it is suppressed in saturated regions, dark regions and heavy texture.
Copy-move and splice correspondence searches one image for two near-duplicate regions, possibly shifted, rotated or scaled, by block matching or keypoints. Its question: does this image contain a region copied from itself? It needs no reference at all. It is deaf to any forgery whose content came from outside the image.
Geometric and physical consistency leaves signal processing and checks whether the scene is possible: whether the perspective of a licence plate agrees with the vehicle, whether the shadows agree with a single light source, whether two photographs of the same damage agree about the object’s shape. Its question is about the world, not the file. It is the hardest to automate. It is also the only family that survives printing and re-photographing intact, because the scene survives when every file-format trace is destroyed.
Each family is blind to some forgeries by construction, because of what it measures. A repainted region inside one uniformly re-encoded photograph is invisible to metadata, compression history, error level analysis and copy-move correspondence, because the quantity they measure did not change.
Setup: a synthetic rebuild
I cannot share the private run, so here is a synthetic one with the same shape that you can run yourself.
A page is a flat array of 2000 samples standing in for pixels. A genuine page is noise around zero. A tampered page has one contiguous patch repainted: a block shifted by a constant. Across the 178 tampered pages, the repainted patch averages 1.85 percent of the page and never exceeds 2.90 percent.
There are three test sets, or cohorts:
- G: 18 genuine documents and no forgeries at all. The in-house smoke set you run before a demo.
- P: 200 photographed pages, 178 of them repainted. The photograph destroyed the container: no revision history, no producer string, no trailer to count. The pixels survive.
- S: 200 born-digital files, 178 of which were re-saved through a second tool. The container changed. The pixels are byte identical to the originals.
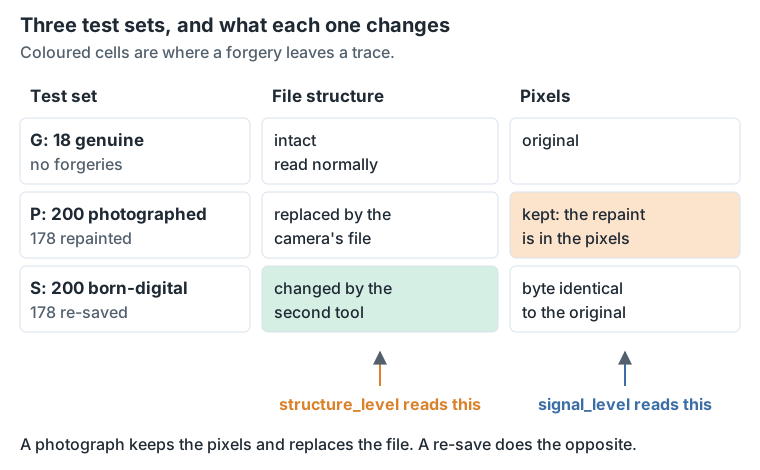
Figure 1. The three test sets, and the layer of the file each detector reads.
There are three detectors:
never_firesreturns “genuine” for everything. It is a baseline to compare against.structure_levelreads the container.signal_levelreads the pixels. It slides a window along the page and takes the largest standardized deviation of the window mean. The scale comes from the differences between neighbouring samples on the page itself, so each page sets its own noise level.
The signal threshold is calibrated on 500 held-out genuine pages to a 5 percent false positive budget. That puts it at z greater than 4.007. It is then never touched.
The scoring code:
def rates(tp, fp, fn, tn):
    return {
        "precision":   None if tp + fp == 0 else tp / (tp + fp),
        "recall":      None if tp + fn == 0 else tp / (tp + fn),
        "specificity": None if tn + fp == 0 else tn / (tn + fp),
        "accuracy":    (tp + tn) / (tp + fp + fn + tn),
    }
It returns None rather than a number in all three places where the denominator can be zero. That matters for precision below.
Seed 20260919, Python 3.12.3, standard library only, no network. Two consecutive runs produce identical stdout.
Results at one threshold
| Cohort | Detector | TP | FP | FN | TN | Precision | Recall | Specificity |
|---|---|---|---|---|---|---|---|---|
| G, 18 genuine | never fires | 0 | 0 | 0 | 18 | undefined | undefined | 1.000 |
| G, 18 genuine | structure level | 0 | 0 | 0 | 18 | undefined | undefined | 1.000 |
| G, 18 genuine | signal level | 0 | 0 | 0 | 18 | undefined | undefined | 1.000 |
| P, 178 of 200 repainted | never fires | 0 | 0 | 178 | 22 | undefined | 0.000 | 1.000 |
| P, 178 of 200 repainted | structure level | 0 | 0 | 178 | 22 | undefined | 0.000 | 1.000 |
| P, 178 of 200 repainted | signal level | 138 | 2 | 40 | 20 | 0.986 | 0.775 | 0.909 |
| S, 178 of 200 re-saved | never fires | 0 | 0 | 178 | 22 | undefined | 0.000 | 1.000 |
| S, 178 of 200 re-saved | structure level | 178 | 0 | 0 | 22 | 1.000 | 1.000 | 1.000 |
| S, 178 of 200 re-saved | signal level | 6 | 2 | 172 | 20 | 0.750 | 0.034 | 0.909 |
Row five is the private incident, rebuilt from scratch. Row eight is the same detector catching 178 of 178 on the question it was built to answer.
Why zero recall looks like a pass
Take the structure detector on cohort P and write the three rates out.
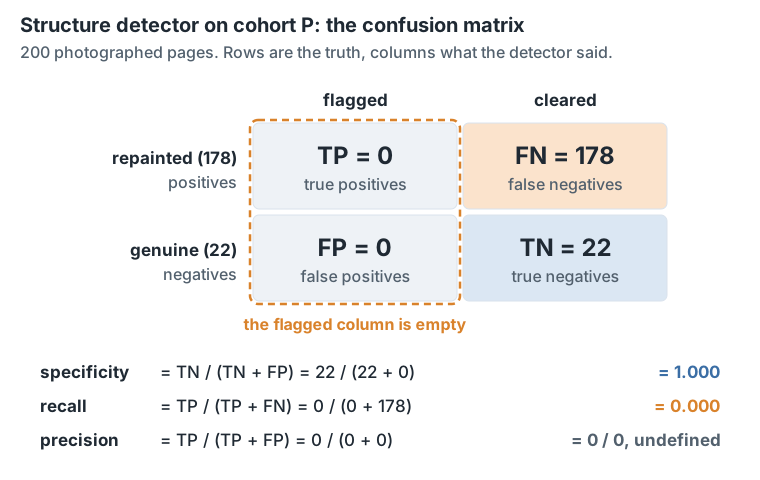
Figure 2. The detector never fires, so both cells of the flagged column are zero.
Specificity is perfect for a reason that has nothing to do with skill. A detector that never fires cannot produce a false positive, so FP is zero by construction. On cohort G, which has no forgeries, there is nothing to miss either, so the arithmetic forces accuracy to 1.000.
Precision is 0 divided by 0, and the honest answer is “undefined”. Almost nothing returns that. The scikit-learn reference says: “When true positive + false positive == 0, precision returns 0 and raises UndefinedMetricWarning. This behavior can be modified with zero_division.” The parameter accepts 0.0, 1.0 or NaN. So the same dead detector on the same run reports precision 0.000 or 1.000, depending on one keyword argument nobody reviews. If a dashboard sets zero_division=1 to stop a warning cluttering the logs, it shows a detector with perfect precision and perfect specificity that has never detected anything.
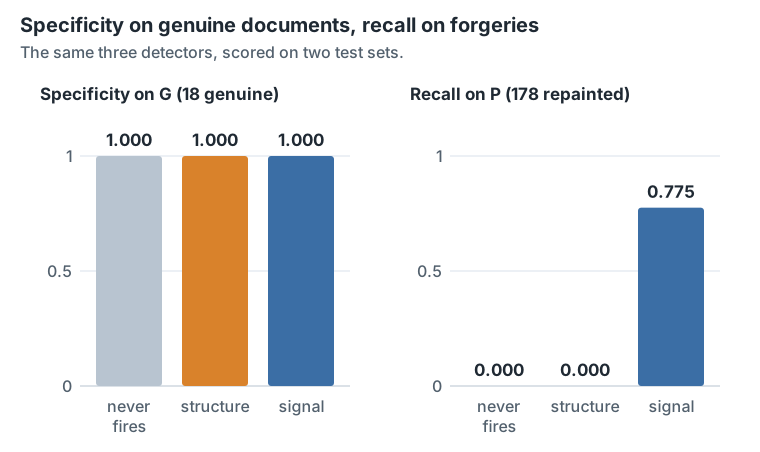
Figure 3. With no forgeries in the set, a working detector and one that always says “genuine” score the same.
Saito and Rehmsmeier make the general point: on imbalanced data, reading ROC plots by eye “can be deceptive with respect to conclusions about the reliability of classification performance, owing to an intuitive but wrong interpretation of specificity”. People read specificity as “it does not make mistakes”. A detector that never fires scores the maximum, 1.000.
Sweeping the threshold
The obvious objection is that I picked a bad threshold. So sweep it: try every threshold and plot recall against the false positive rate. That plot is the receiver operating characteristic (ROC), and AUC is the area under it. An AUC of 0.5 is chance; 1.0 is perfect separation.
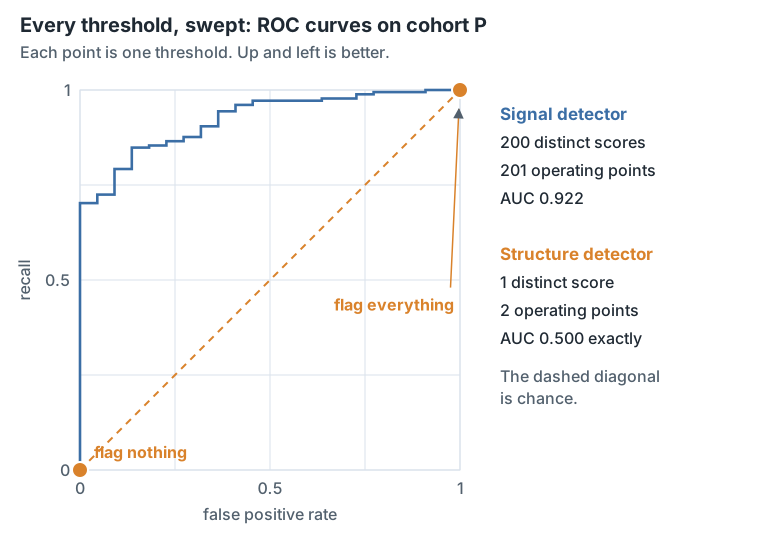
Figure 4. One score value gives two operating points and an AUC of exactly 0.500.
On cohort P the structure detector gives one distinct score across all 200 documents. Sweeping its whole range reaches two operating points. Flag nothing: recall 0.000, false positive rate 0.000. Flag everything: recall 1.000, false positive rate 1.000. Both are ends of the diagonal, so the AUC is exactly 0.500. On the same documents the signal detector gives 200 distinct scores, reaches 201 operating points and scores AUC 0.922. On cohort S the roles swap. The structure detector scores AUC 1.000 and the signal detector 0.444, which is chance plus the noise of only 22 genuine documents.
An AUC of exactly 0.500 is a different thing from an AUC near 0.500. Near 0.500 means a detector that separates poorly. Exactly 0.500 means one that has not measured anything. I read it as a type error, a sign that the detector measures the wrong kind of thing, rather than as a performance result.
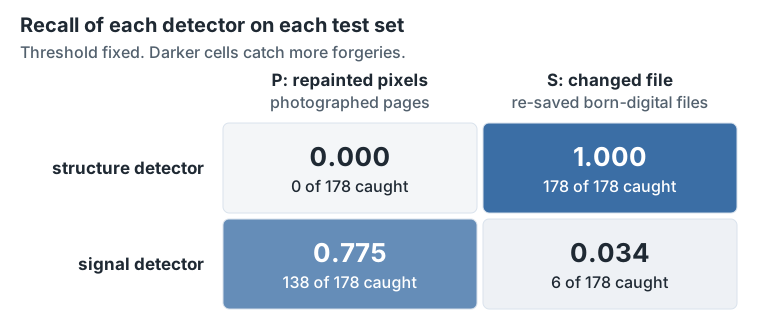
Figure 5. Each detector is excellent on its own question and near zero recall on the other’s. What failed was the pairing of a detector with a label.
A published case shows the same thing on real data. A 2026 compression-history screening method reports AUC 0.990 on a format-controlled JPEG subset of the CASIA v2.0 dataset. It also reports AUC 0.499 on the CoMoFoD copy-move dataset, used on purpose as a negative control. Copy-move duplicates a region inside one image and leaves compression history untouched, so a compression-history detector lands on chance. The authors draw the conclusion in the abstract: the method “should therefore be interpreted as a JPEG compression-response screening tool, not as a universal detector for all image manipulation mechanisms.”
The same paper shows the mirror image of the mistake. CASIA v2.0 has a format confound: 60 percent of its tampered images are TIFF files, and none of its authentic images are. So “a trivial is_tiff classifier” reaches 0.80 AUC. That is a container-level feature scoring 0.80 on a pixel-level label, for a reason that has nothing to do with tampering. A zero is easy to see as a failure. A 0.80 from a format confound is easy to mistake for a result.
Calibrating on genuine documents only
The usual calibration: collect genuine documents, run the detector, and pick the threshold that keeps the false positive rate inside your budget. That fixes one column of the confusion matrix and says nothing about the other. So the calibration returns a threshold that says nothing about recall. Here it is at five budgets, with each threshold then applied to cohort P.
| False positive budget | Structure threshold | Structure alarms per 200 | Structure recall | Signal threshold | Signal alarms per 200 | Signal recall |
|---|---|---|---|---|---|---|
| 0.20 | 0.000 | 0 | 0.000 | 3.617 | 162 | 0.876 |
| 0.10 | 0.000 | 0 | 0.000 | 3.796 | 151 | 0.831 |
| 0.05 | 0.000 | 0 | 0.000 | 4.007 | 140 | 0.775 |
| 0.02 | 0.000 | 0 | 0.000 | 4.297 | 127 | 0.708 |
| 0.01 | 0.000 | 0 | 0.000 | 4.492 | 121 | 0.680 |
The structure detector’s 500 calibration scores all take one value. So every budget from 20 percent down to 1 percent returns the same threshold. The budget changed twentyfold and the threshold did not move: the calibration made no decision, and nothing downstream of it can tell. The signal detector’s calibration scores take 500 distinct values, and its threshold moves from 3.617 to 4.492 across the same budgets.
The right half of that table is also the honest way to state an operating point. “We calibrated at 0.05” sounds like a property of the model. “162 alarms per 200 documents buys recall 0.876, and 121 buys 0.680” states what each choice costs the reviewers. Whoever opens the review queue should get to choose between those two, and they cannot if the only number that reaches them is a threshold.
Recall by repaint area and contrast
This is the result I did not expect, and it changes how I read a benchmark headline.
Take recall on the 178 repainted pages at one fixed threshold. Grouped by area, it runs 0.709, 0.809, 0.867 across a factor of 2.4 in area. Grouped by contrast, meaning how far the repaint shifts the signal in units of the page’s own standard deviation, recall runs 0.318, 0.867, 0.909, 1.000 across a factor of 3.4. Area moves recall by 0.157. Contrast moves it by 0.682.
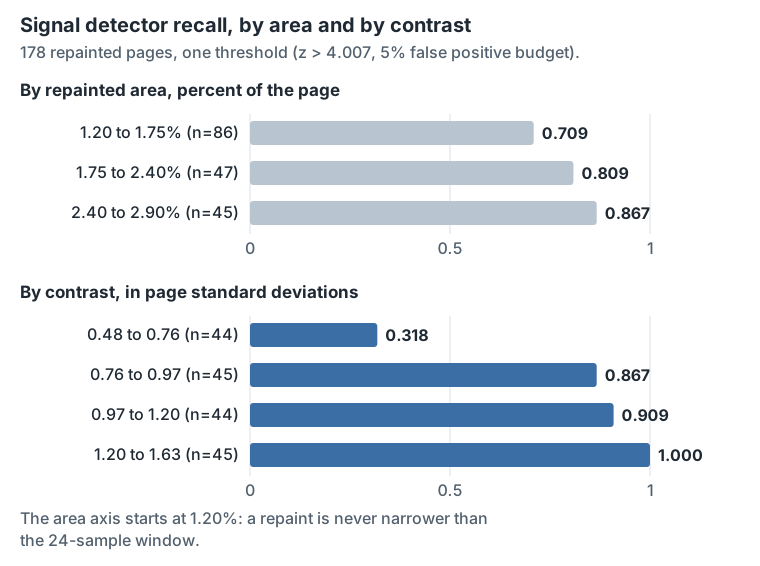
Figure 6. Recall follows the repaint’s contrast far more than its area.
The statistic explains why. The detector averages over a fixed window of 24 samples. Its standardized deviation is roughly the contrast times the square root of the window length. Once the repainted patch is wider than the window, the extra area is area the statistic never averages over, so area stops counting. Past that width, a bigger repaint does not raise the score, while a fainter one always lowers it.
That is a property of this statistic. Any real detector has its own version, set by how much of the image it sees at once (its receptive field). What carries over is the consequence. The 1.85 percent average describes this run’s geometry, not its recall. Neither an average tampered area nor a single recall number from a benchmark predicts recall on inputs whose contrast differs. It is the same mistake as the original failure: a number measured on one kind of input applied to another.
The area axis is truncated. A repaint is never narrower than the window, which is 1.20 percent of the page, so the bottom area bin starts at that floor and holds 86 of the 178 pages. The claim is the mechanism (area stops counting), not the exact slope.
An LLM judge over forensic signals
There is a real reason to put a language model at the end of a forensics stack. Under a strict output schema (fixed fields, a required list of the signals it used, an explicit abstain value) it is one component whose contract you can test. It also produces what a reviewer needs: a written reason attached to the flag.
The risk is in what the judge is shown. A judge given the upstream verdict is not a second opinion. The NeurIPS 2024 work on self-preference bias found that “GPT-4 exhibits a significant degree of self-preference bias”. The cause is not that the model recognises its own output. Models “assign significantly higher evaluations to outputs with lower perplexity than human evaluators, regardless of whether the outputs were self-generated”. Lower perplexity means text the model finds more predictable, so the bias is a preference for familiar text. A fluent upstream verdict is that kind of text: a familiar anchor handed to the judge before it has looked at the evidence, whether or not it wrote the verdict.
So the judge gets the signals and their numeric values, not the verdict. It is scored the way the detectors are scored: on a labelled set, with its own confusion matrix, its abstain rate, and the rate at which it flags evidence that turns out to be a known innocent cause of false alarms. A judge that agrees with a detector that never fires also has recall 0.000, whatever reason it writes.
Limits
The reproduction is synthetic. Its pages are one-dimensional Gaussian noise. The tampering is a constant offset on a contiguous block, which a sliding-window statistic is well suited to find. Real repainting has to survive JPEG re-encoding, rescaling, lighting and print-then-photograph pipelines. And in document images, tampered regions “can be seamlessly blended into the uniform document background (BG) and structured text”. Read the 0.775 as “a detector at the right level of analysis gets non-zero recall”, not as a performance estimate.
The cohorts are small on purpose, to match the shape of the incident, so every sampled rate is very uncertain. 18 genuine documents, or 22 in each labelled cohort, cannot pin down a false positive rate. The structure detector’s 1.000 and the null detector’s 0.000 are exact in a different sense: they follow from how the detectors are built, not from sampling.
The real run stays private. I do not quote its numbers, because a reader cannot check them. What transfers is the arithmetic.
What I ask for now
- The confusion matrix: four cells with their denominators, rather than a headline metric. Every headline metric hides a zero-division policy. And a 2024 review of over 1.5 million papers found that even the widely repeated preference for one aggregate metric over another is “often made without citation, misattributed to papers that do not argue this point, and aggressively over-generalized from source arguments”.
- The number of distinct scores the detector produced on the evaluation set. One distinct score is a type error, not a result. This count is cheaper than AUC and catches the same thing.
- Recall on a labelled set that contains forgeries, broken down by whatever drives detectability, next to the number of alarms per hundred documents at that operating point.
- The null detector as a permanent row in the comparison table. It costs one row, and it turns “our specificity is 1.000” into a claim with a control.
Where this sits now
Figure 7. A risk score and a confidence score sit side by side on the card. Neither is a recall.
The public page for my own product, fidelityai.dev, titles its argument “Modern fraud has outgrown metadata-only checks”. It lists metadata-only authenticity checks among the things being replaced. I agree with that page, and agreeing with it does not close the gap. Locating tampered regions at the pixel level needs a pixel-level model: a different build from a better parser. It brings its own labelled data problem, its own robustness problem under compression and re-photography, and its own false positive budget to negotiate with a review team.
The part I am least sure about is how to fix the underlying habit. Writing the two sentences down catches the mismatch once you suspect it. The distinct-score count is the cheapest thing I have found that catches it when you do not.
Sources
- scikit-learn, precision_score API reference and Metrics and scoring, for the definitions and the documented zero-division behaviour.
- E. Kee, M. K. Johnson and H. Farid, “Digital Image Authentication from JPEG Headers”, IEEE Transactions on Information Forensics and Security 6(3), 2011, for the camera signature and for its authors’ own statement of what it does not cover.
- T. Saito and M. Rehmsmeier, “The Precision-Recall Plot Is More Informative than the ROC Plot When Evaluating Binary Classifiers on Imbalanced Datasets”, PLOS ONE, 2015, on the misreading of specificity.
- “Format-Controlled Multi-Scale JPEG Compression Response Analysis for Image-Level Compression-History Forgery Screening”, 2026, for the CoMoFoD negative control at AUC 0.499, the CASIA v2.0 format confound and the is_tiff classifier at 0.80 AUC, and the stated limits of single-quality error level analysis.
- Error Level Analysis and the multimedia forensics topic index, for the family taxonomy and for a plain statement of what error level analysis cannot establish.
- C. Qu et al., “Towards Robust Tampered Text Detection in Document Image: New Dataset and New Solution”, CVPR 2023, and the DocTamper repository, for the 170,000-image labelled benchmark and the Frequency Perception Head.
- K. Wong et al., “ADCD-Net: Robust Document Image Forgery Localization via Adaptive DCT Feature and Hierarchical Content Disentanglement”, 2025, for the current state of document image forgery localization and for DCT block misalignment.
- K. Wataoka, T. Takahashi and R. Ri, “Self-Preference Bias in LLM-as-a-Judge”, NeurIPS 2024 workshop, for the measured bias and for the perplexity mechanism behind it.
- M. B. A. McDermott et al., “A Closer Look at AUROC and AUPRC under Class Imbalance”, 2024, for how far an aggregate-metric preference can travel without a citation behind it.