My video pipeline has to predict how long a script will take to read aloud, before any audio exists. That prediction was one number: seconds per letter of narration. It was fitted once, by hand, on six samples from a single voice. The comment beside it said to re-measure it when the voice or the model changed. Nobody did, for years, and not out of laziness. There was no data set to re-measure it against.
Most systems that call a stochastic service carry a number like this. A stochastic service is one that can return a different result for the same input. The number turns an input into an expected cost: characters to seconds, tokens to latency, pages to euros.
Two kinds of number appear below:
- Every number in a table or a data chart comes from a seeded reproduction script that runs on synthetic data. You can run it yourself.
- Any number I mark as private comes from the record of my own system. You cannot rerun it. It is here because its shape is the point.
First check: refit the constant
One objection: the constant may be fine. A regression turns one line of arithmetic into an artifact. That artifact has to be stored, versioned, validated, and explained when it drifts.
So the first step is not to build a model. It is to refit the constant properly, and see whether the kind of model was ever the problem. On the synthetic corpus described below:
- The constant fitted on six samples of one voice has a mean absolute percentage error of 16.82 percent. MAPE is the average error as a percentage of the measured duration.
- The same one-parameter model, refitted on all 120 sentences, gets 9.52 percent.
- The best pooled model gets 8.89 percent.
The inherited number is 7.93 points behind the best pooled model, and refitting alone closes 7.30 of them. Almost all of the error was sample size.
Why nobody re-measured it
A number gets re-measured when re-measuring is cheap and someone owns the cost of it being wrong. Neither was true here.
- Re-measuring meant synthesising a corpus, timing it and building a fitting harness, all before knowing whether the answer would move.
- The gate that used the number was loose. A wrong number only showed up as the occasional long video that somebody trimmed by hand.
So the question became which existing data already held the measurement.
Measuring the pipeline from outside
First, the measuring tool. The pipeline became measurable through a tracing layer installed from outside it. The layer patches four boundaries that the system already funnels everything through:
- The subprocess runner. It sees every child process.
- The HTTP client’s send method. It sees every outbound call, with its request and response.
- The factory that builds model clients. It sees every model completion, with its prompt and reply.
- The streaming agent transport.
Only then does the layer wrap the pipeline’s own step functions, so each second can be charged to a step rather than to a socket.
The layer wraps from outside, instead of adding timing code inside, for one reason. A diagnostic that requires editing the thing it measures ends up measuring a different program. A branch carrying timing code drifts away from the product, and eventually reports on something the product no longer is. Patching four chokepoints from outside means the measured run is the shipped run, byte for byte.
Three rules came with it:
- Redact credentials. The trace redacts credential headers as it captures them, because a trace meant to be pasted into a report will eventually be pasted somewhere.
- Keep it off in production. The trace records whole response bodies, so it stays off for anything serving other people. This pulls against the next section: the capture that makes calibration free is the one you must not leave running in production.
- Measure the paths customers use. The operator tool that produced every number in my speed study could not ask for a custom script, custom footage, a non-default voice, or a video without a watermark. Those are three of the four things a paying customer brings. If the measuring tool cannot exercise a path, nobody measures that path.
The calibration data was already in the logs
Every successful run paid a forced aligner for per-word timings. A forced aligner takes audio plus its known transcript and returns when each word starts and ends. The pipeline used those timings to land the captions on the right frames. Then it threw them away once the captions were burned in.
But the tracing layer captures whole response bodies. So old run files on disk still held the aligner’s output, verbatim. That is a calibration set: sentence text on one side, measured duration on the other. Close to two hundred rows, already paid for, needing no network call and no new synthesis.
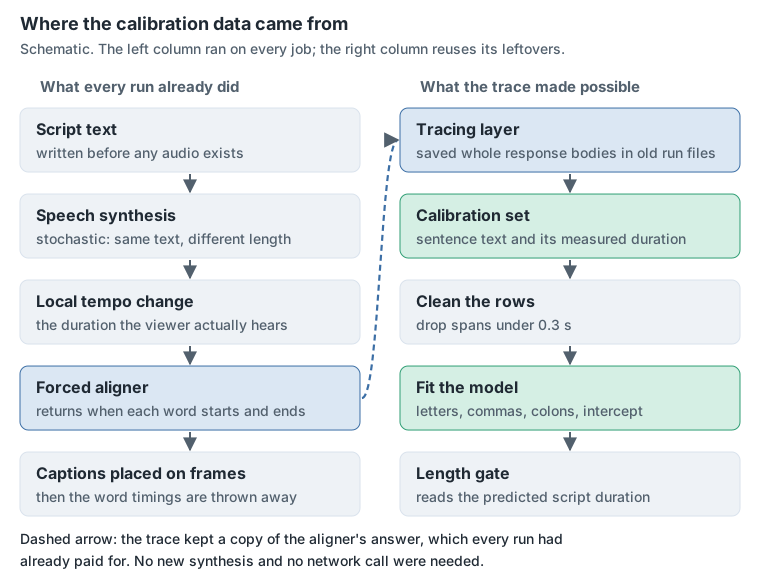
Figure 1. The calibration set is a by-product of work every run already did.
This is not special to speech. A system that calls a stochastic component and then measures what came back is already producing labelled data for a model of that component. Token counts in response headers, a queue’s recorded job durations, an OCR engine’s per-page confidence: each is logged, used once and dropped. Before building anything to collect more data, look at what your logs already hold.
Data mined from logs needs cleaning that purpose-built data does not. Two rules earned their place:
- Drop any span under 0.3 seconds. Below that, a “sentence” is an alignment artifact, and those rows would dominate a percentage error.
- Fit on the duration the consumer receives. That is the duration after the local tempo change, not the raw synthesis output.
The vendor documentation was least useful on the second rule. The speech service has its own speed parameter. Asked for speeds 1.0, 1.2 and 1.44, it returned the same sentence at 5.41, 5.15 and 5.25 seconds (private). That is five percent of movement for a twenty percent ask, and the durations did not even fall steadily as the speed rose. So the pipeline changes the tempo locally instead, where the change is linear to within a few milliseconds, and the model is fitted after it. The calibration covers the whole path, up to the end the consumer reads.
Setup: a synthetic version you can rerun
From here on, every number comes from a synthetic generator I can hand you, unless it is marked private. The generator invents six voices in two categories, three voices each. Each voice:
- reads at its own rate, in letters per second;
- adds a fixed pause for each comma, and a longer one for each colon.
Each render then gets its own independent random jitter, lognormal with a standard deviation of 3.5 percent. Each voice reads 20 sentences, so the corpus has 120. Every sentence is rendered three times.
true_mean = (
    letters / rate
    + COMMA_PAUSE_S * commas
    + COLON_PAUSE_S * colons
    + spec["lead_in_s"]
)
renders = [true_mean * math.exp(j) for j in jitters]
The model under test is ordinary least squares, a plain linear regression. It has three features plus an intercept: letters, commas, and colons plus semicolons. “Letters” means the characters left after removing spaces and punctuation. A space takes no time to say. The punctuation that does take time gets its own column, instead of being counted as a letter. What is being measured is the pause, not the mark.
The reproduction is one Python file. It uses only the standard library, is seeded at 20260919 and makes no network calls. It prints every synthetic number in this post.
Results: pooled models
“Pooled” means one model fitted to all six voices together. Each model below is scored against one render per sentence, on the 120-sentence corpus:
| Pooled model | MAE, seconds | MAPE, percent | R squared |
|---|---|---|---|
| constant, 6 samples, 1 voice | 1.005 | 16.82 | 0.7411 |
| constant, refitted on all 120 | 0.581 | 9.52 | 0.9121 |
| words plus intercept | 0.776 | 13.68 | 0.8552 |
| letters plus intercept | 0.577 | 9.70 | 0.9139 |
| letters, commas, colons | 0.539 | 8.89 | 0.9254 |
| the above plus word count | 0.540 | 8.90 | 0.9284 |
What the table shows:
- The new features barely help. Against a properly refitted constant, the three-feature model gains only 0.63 points. On its own that is not worth a new artifact, and if you stop here you should keep the constant.
- A model per voice is what pays. Fitting the same three features separately for each voice reaches 3.39 percent on held-out sentences, ones the fit never saw. That only becomes possible once a calibration set exists at all.
- Word count adds nothing on top of letters. It moves MAPE from 8.89 to 8.90. The two columns are nearly collinear: they carry almost the same information.
- The words-only row is not evidence about real speech. At 13.68 percent, it measures the cost of the wrong unit in a generator that is driven by letters by construction. The private fit says letters beat words in real speech too, by a similar margin, but this script cannot hand you that.
The table shows two error metrics because neither is enough alone. MAE, the mean absolute error in seconds, is what a scheduler reads, but it depends on scale. MAPE compares across sentence lengths, but blows up when the measured value is near zero.
The noise floor
Three renders of the same sentence do not last the same time. The corpus therefore already contains a direct measurement of the component’s own variance.
Across 360 pairs of renders of identical text, the median absolute gap is 178.1 milliseconds and the mean relative gap is 3.82 percent.
It is tempting to call 3.82 percent the floor: the error a predictor working only from the text should not be able to beat. It is not. The gap between two noisy renders carries the noise of both. For independent errors, the mean absolute gap is the square root of two, 1.414, times the mean distance of one render from its own expected value. So the floor a text-side predictor faces is 3.82 divided by 1.414, or 2.7 percent. Reporting the raw pair gap as the floor overstates it by 41 percent, and quietly gives the model headroom it does not have.
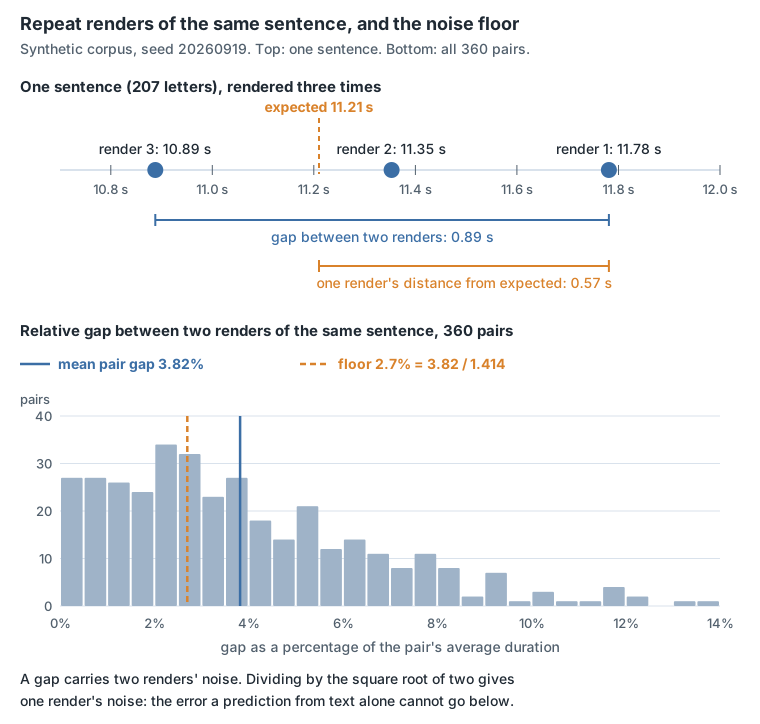
Figure 2. The gap between two renders is the wrong yardstick. The floor is one render’s distance from its expected value.
The correction matters as soon as a model is scored. The per-voice fit gives 2.47 percent in sample, that is, scored on the same sentences it was fitted on. That is below the floor. A model cannot predict a quantity more precisely than the quantity varies, so this is not skill.
Fitting p parameters on n points shrinks in-sample errors by the square root of one minus p over n. Here p is 4 and n is 20, so the factor is the square root of one minus four over twenty, or 0.894. A model sitting exactly at the floor should therefore show about 2.7 times 0.894, or 2.42 percent, in sample. The observed 2.47 is that number. Scored on a held-out half of each voice, the same fit gives 3.39 percent. That is above the floor, and it is the only one of the two figures that is a claim.
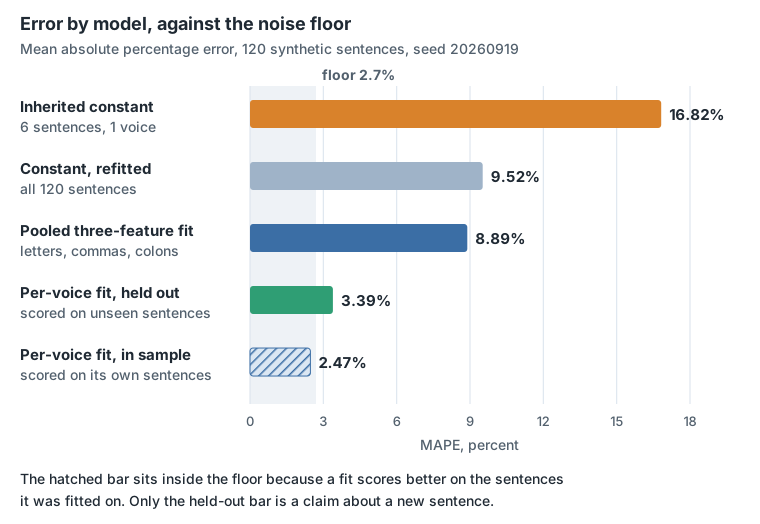
Figure 3. The pooled fit, at 8.89 percent, still carries about six points of error a better model could remove, because one pooled model cannot represent each voice’s own reading rate. The in-sample bar crosses into the floor band because of shrinkage, not because a model beat the generator’s own variance.
So the module states the floor instead of claiming to beat it. A gate that rejects any prediction more than two percent away from reality rejects plain noise in a fixed share of cases, forever, and no feature work will fix that.
One model per category, or one pooled model
Reading rate belongs to the voice, but the metadata you have tends to record only a category. The tempting move is to fit one model per category, and serve a new voice from its category’s model. It looks more specific and more principled.
The check that decides it is leave-one-group-out. Hold one voice out entirely, fit on the rest, and predict the held-out voice with a model that has never seen it. Ordinary cross-validation assumes the samples are independent. Samples grouped by voice are not, so each held-out fold has to be a whole group.
There are two candidates and six folds, one per voice:
- Category model: fitted only on the other voices of the held-out voice’s category.
- Pooled model: fitted on all the other voices.
Pooling wins on the mean, 10.78 against 13.12 percent, and on four of the six voices, because in this corpus the category label carries no information about reading rate. Restricting the fit to the held-out voice’s category buys nothing, and throws away three fifths of the training rows.
That result alone would be suspicious, since I wrote the generator. So the script runs the identical procedure on a second corpus, where the two categories are deliberately 7.0 letters per second apart, with every other random draw held identical. There the category model wins, 13.52 against 22.75 percent, and pooling wins only two of six.
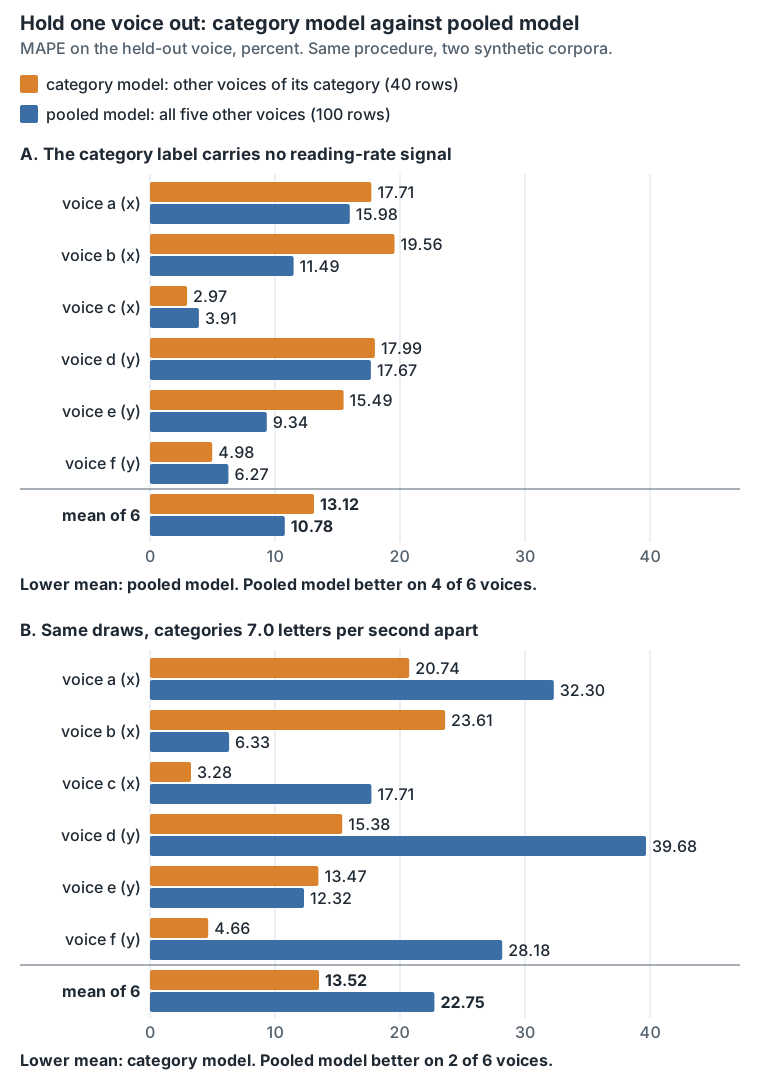
Figure 4. Panel B is the control. The procedure visibly detects a group effect when one exists, so its result in panel A can be trusted.
Look at the spread in panel A. The pooled model’s error runs from 3.91 percent on one voice to 17.67 on another, so the mean of 10.78 describes no voice in the table.
Here the synthetic version undersells the real one. In the private fit, pooling across languages was free for the language that dominated the corpus, and close to doubled the error for the one that did not. The mean over folds hid that. A calibration that reports only its average is reporting the majority group’s error, and the group you are about to serve may be the minority.
The remedy is a model row per group. That turns the question into how few samples justify one. In the private system, the bar started at twenty-five sentences per voice. Most of a twenty-voice cast would never have got a row, and would have kept being served somebody else’s reading rate. The bar is five now. Five is safe for two reasons: the fit uses only the features the sample supports, and it refuses any result implying an implausible reading rate.
Voices that never use a colon
One synthetic voice never uses a colon. Fit that voice alone, and its colon column is all zeros. The equations then have no unique solution, because no row constrains the colon coefficient.
A least squares routine is defined for such under-determined systems and will return something anyway. NumPy’s documentation says it determines rank by treating singular values below a cut-off as zero, and that when several solutions fit equally well it returns the one with the smallest norm. That is a reasonable default, and a silent one.
The fit returns coefficients. The error looks fine on that voice, because it has no colons to get wrong. And the artifact ships with a number nobody can explain.
In the real corpus (private) this was not an edge case. Three of the six calibrated voices had no colon in any sentence, so the per-voice fit had no unique solution for them at any sample bar. Raising the bar would have looked responsible and fixed nothing.
The fix is cheap:
- Drop all-zero columns before the solve, and record which were dropped. The reproduction script does this, and reports the dropped colon column for the voice that has none.
- Refuse any result whose implied reading rate is physically absurd.
A fit on thin data can be arithmetically valid and still be nonsense. A bound on the coefficient catches that far more cheaply than inspecting the residuals.
Error per sentence and per script
The prediction is used per script, not per sentence. Per-sentence errors are close to independent, so they cancel when a script is summed. Under the per-voice fit, 2.47 percent per sentence becomes 0.47 percent over twelve scripts of ten sentences.
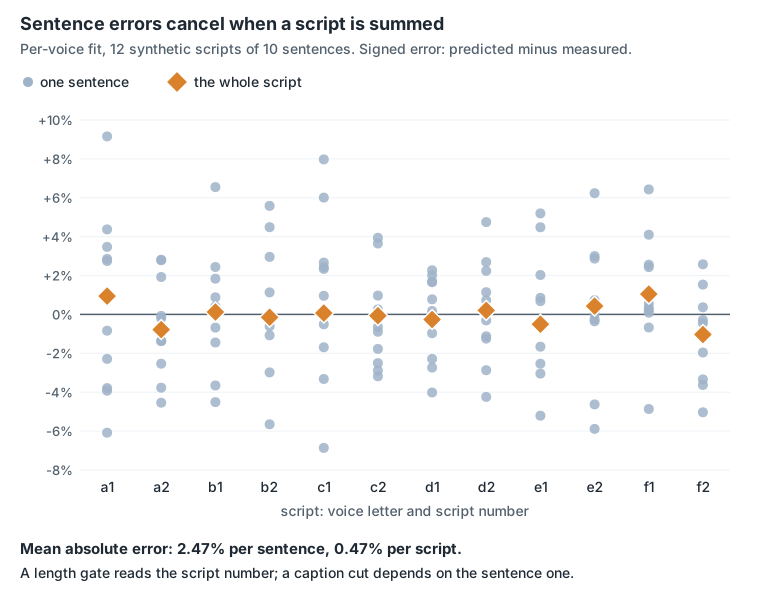
Figure 5. The same model, read at two scales.
The script-level figure is what a length gate reads. But quoting it as the model’s accuracy overstates what the model can do for a single sentence, which is what a caption boundary or a scene cut depends on. Report both, and say which one each consumer reads.
The gate’s tolerance is derived, not chosen. These figures are private:
- It was plus or minus fifty percent, which let a sixty-second request ship at 51.5 seconds without complaint.
- Fifteen percent let a thirty-second request ship at 25.8 seconds.
- Ten percent leaves the model roughly twice its own measured error: enough headroom not to fight the estimator, and tight enough to catch that run.
The method is not private. Set a tolerance at a small multiple of the estimator’s measured error, and you can defend both the number and the next change to it.
Figure 6. The length slider the duration model serves. That is why the accuracy that matters is the finished video’s, not the sentence’s.
The finished video still misses
Eight runs of the finished system asked for sixty seconds, and delivered between 18 percent short and 13 percent long (private). The estimator is accurate to low single digits at script level; the finished video misses by up to eighteen.
These do not conflict, because the error is not in the estimator. It is in what the writing stage produces against the budget the estimator computed. That stage has its own distribution, with its own variance and bias, and that stage was never measured.
The tempting move is to derive a correction from those eight runs, and it is wrong. They miss in both directions, so there is no offset to remove, and eight runs is not a distribution. The defensible order is:
- Record asked against delivered on every job, until the anecdotes become a distribution.
- Attribute the error to a candidate stage on its own.
- Only then change a constant.
This is the same order as at the start of this post, one stage later: measure first, then change the constant.
This is the design behind the script length gate in pipelinevideo.com. The real version, which you cannot rerun, had the same shape:
- around ten percent error per sentence, against a constant in the mid teens, on under two hundred mined sentences;
- a repeat variability of a few percent, written into the module as a stated floor;
- a hold-one-out check that rejected the per-category fit;
- a whole-script prediction within a couple of percent, on the one job where it was checked against delivered audio.
Run-to-run variance in the whole pipeline
The floor argument is not specific to regressions. It governs every measurement of a system that calls a stochastic service. The version that cost me the most was about wall-clock time.
Two runs of the pipeline came back 105 seconds apart, on a job of roughly eight minutes (private). Same site, same configuration, same machine, nothing changed between them. Almost all of the gap was one model call. It answered in 168 seconds on one run and 54 on the other, for a prompt of the same size.
The rule written under it mattered more: nothing under about two minutes on one run is evidence. That is a noise floor, computed the same way as the duration model’s, from repeated identical input. It does the same two jobs:
- it says how large an effect must be before one measurement can see it;
- it says how many repeats a smaller claim needs.
Rules like this share one failure mode, and I hit it. A later change was dismissed as one run either side of that band. It was not noise. It was a real mechanism whose effect happened to be about the size of the variance. A floor says one run cannot tell the two apart. It does not say the effect is absent. A result inside the band needs more runs before any conclusion.
Optimisations measured and rejected
Two optimisations I measured and rejected. Both are private, and neither is rerunnable by you.
A cheaper model tier. Switching every model call to the vendor’s cheaper, nominally faster tier made the whole job 45 percent slower, and the output was no better. The cause was not a slower token rate. On the same replayed prompt, the cheaper model answered with 7,283 characters against 5,569. On a single-shot transport, with no batching and no cache between calls, a longer answer is a slower answer.
More parallel calls. Raising a parallel pass from four concurrent calls to six made it slower. The arithmetic said 80 seconds; it took 320. The six calls came back at 26.5, 178.6, 205.8, 210.5, 246.9 and 300.6 seconds. Each held less work than the answers at two concurrent calls, which had taken 47 to 50 seconds. How much parallelism helps is set by the provider’s side of the connection, not by the local machine. That run also hit a temporary overload at the provider, so it is confounded. It is still the only measurement past four that exists, and it says slower. Both halves of that belong in the write-up.
A rejected optimisation has a shelf life, so record the measurement and not just the verdict. “The cheap tier is the slow tier” is a fact about one model line-up on one transport. When either changes, the experiment reruns in one command, because the conditions were written down beside it.
What this does not show
The corpus is synthetic, and I wrote the process that generates it. So this demonstrates mechanisms; it does not measure speech. Real duration is not exactly linear in letters, real pause lengths depend on context, and real render variance is probably not a clean lognormal.
The square-root-of-two correction assumes two renders are independent draws with equal variance. A warm cache, a shared seed or per-request adaptive behaviour breaks that assumption, and the estimated floor moves.
The hold-one-out comparison covers two candidates on six groups. Its spread, from 2.97 to 19.56 percent, says plainly that a mean over six folds is soft. A third candidate would very likely beat both: partial pooling, where each group gets an offset shrunk toward the global fit. It would also speak directly to the minority-group problem. This post does not test it.
R squared is in the table because it is conventional, not because it decides anything.
Open question: when to refit
Calibration is cheap, because the data arrives for free. But a coefficient that moves when a vendor silently changes a model version is a drift problem. I have no trigger that tells a real shift from a run of unusual scripts. Today the answer is a human noticing. That is the same failure as a comment asking somebody to re-measure a constant, read by nobody for years.
Sources
- NumPy,
numpy.linalg.lstsq, for the solve on under, well and over determined systems, and rank by a singular value cut off. - Hyndman and Athanasopoulos, Forecasting: Principles and Practice, section 5.8, for scale dependent errors and where percentage errors break down.
- scikit-learn, Cross validation: evaluating estimator performance, for grouped samples and what a held out group tests.
- NIST/SEMATECH, measurement process characterization, for repeat measurements of one item differing and precision as a standard deviation.