acf in statsmodels computes the autocorrelation function (ACF) of a series. Before a contribution that improved its missing-data handling, it had a bug with missing="drop". On an array with NaNs, it returned the same ACF values as removing the missing values by hand. But its confidence intervals were narrower. In the archived lag-one cases below, its Ljung-Box Q statistics were also larger. The ACF used one sample size, and the interval and Q used another.
The ACF plot still looks plausible, and a test that checks only the ACF values passes. The error is in the numbers used to decide which spikes matter.
What acf returns
acf can return four arrays, each with one value per lag. A lag is a shift: lag 1 compares each value with the one before it, lag 2 with the one two steps back, and so on.
- The ACF value. How strongly the series correlates with itself shifted by that lag. It runs from -1 to 1.
- A confidence interval (with
alpha). A range around each ACF value. If the range does not include zero, the autocorrelation at that lag is usually read as real rather than noise. The range gets narrower as the number of observationsngrows. - The Ljung-Box Q statistic (with
qstat=True). It combines the squared autocorrelations of lags 1 tominto one number. A large Q points to autocorrelation somewhere in those lags. Its formula is scaled byn(n+2). - A p-value for each Q.
The interval, Q and p-value all depend on n, the number of observations. That count is where the bug was.
Reproduction
import numpy as np
from statsmodels.tsa.stattools import acf

rng = np.random.default_rng(0)
kept = rng.standard_normal(200)
with_nans = np.concatenate([kept, np.full(200, np.nan)])
options = dict(nlags=10, qstat=True, alpha=0.05, fft=False)

drop = acf(with_nans, missing="drop", **options)
manual = acf(kept, missing="none", **options)

for label, index in [
    ("ACF", 0), ("interval", 1), ("Q statistic", 2), ("p-value", 3)
]:
    print(label, np.allclose(drop[index], manual[index]))
The snippet builds 200 random values, appends 200 NaNs, and calls acf twice: once on the full array with missing="drop", once on the 200 values with nothing missing. On the pre-fix checkout, the four lines read True, False, False, False. With the merged fix, all four read True.
Deleting the NaNs by hand is the right reference because of what the documentation promises for missing="drop": remove the missing observations, then treat the survivors as if they were consecutive. This holds for this one estimator. It is not a general recipe for irregular time series: if a missing reading stands for elapsed time, joining its neighbors changes the time axis.
The snippet only shows which outputs agree. The numbers in the rest of the post come from archived runs on frozen inputs:
- an archived reproduction with the same shape as the snippet, 400 values of which 200 survive;
- a seeded AR(1) series of 40 values with
phi = 0.7, used for the figures. AR(1) means each value depends on the one before it.
Two counts matter, and I use these names for them throughout:
n_raw: the length of the array passed in, missing entries included;n_eff: the number of non-missing values that survive the missing-data rule.
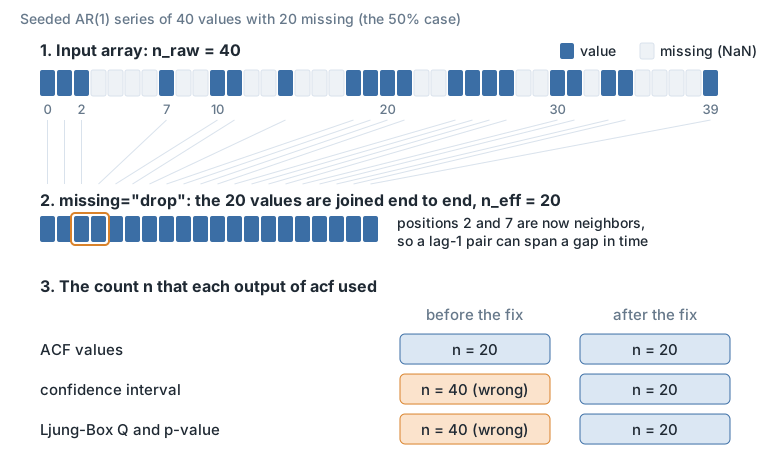
Figure 1. With drop, the ACF estimate, its confidence interval and its Q statistic must all use the same count: the values that survive. Before the fix, only the ACF did.
In the archived reproduction, n_raw = 400 and n_eff = 200. Before the patch, the ACF values followed the 200 survivors, while the interval and Q statistic were still computed with 400.
Why the ACF values were right
acf hands the autocovariance calculation to acovf. In the drop branch, acovf removes the missing values first. So the ACF matched the series shortened by hand.
But acf also kept its own observation count, x.shape[0]: the full array length. It reused that stale count in two places:
- the confidence interval, Bartlett or non-Bartlett;
q_stat(acf[1:], nobs=...).
A test on the ACF values alone could not catch this. A test on the returned interval and Q statistic could.
The source already had a comment asking whether nobs should shrink for missing="drop". The tests had a disabled FIXME for the matching Q-statistic case.
Confidence interval
For a positive lag k, the Bartlett half-width that acf implements is
h_k(n) = z * sqrt((1 + 2 * sum_{j=1}^{k-1} r_j^2) / n)z is the normal quantile for the requested confidence level (1.96 for 95%). r_j is the estimated ACF at lag j. The half-width is the distance from the ACF estimate to one end of the interval; the full width is twice that.
Between the old and the corrected call, the ACF values and z are the same. Only n differs. So the old-to-corrected ratio is
h_k(n_raw) / h_k(n_eff) = sqrt(n_eff / n_raw)This is exact for the Bartlett formula at positive lags. It also holds for the non-Bartlett option, whose half-width is z / sqrt(n). It says nothing about the empirical coverage of either interval, that is, how often it actually contains the true value.
At n_raw = 400 and n_eff = 200, the ratio is sqrt(200 / 400) = 0.7071. The affected code returned a lag-one half-width of 0.097998. The manually dropped reference returned 0.138590.
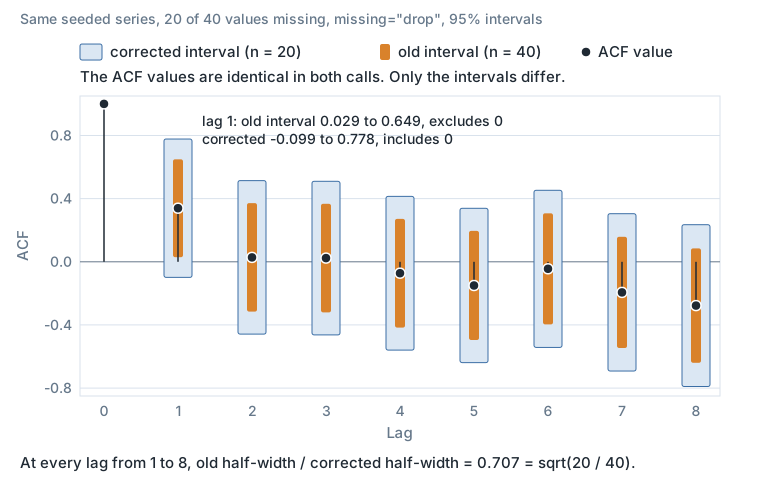
Figure 2. Half the values missing, drop mode: the corrected count widens the interval at every positive lag, and every ACF estimate stays where it was.
There is one set of points because the old and corrected ACF values are bit-identical in this frozen run. Only the intervals change, because their count changes from 40 to 20. At lag 1 this changes what the interval says. The old interval runs from 0.029 to 0.649 and does not include zero. The corrected interval runs from -0.099 to 0.778 and does.
Ljung-Box Q statistic
Statsmodels uses the Ljung-Box formula, summed over lags 1 to m:
Q_m(n) = n(n+2) * sum_{k=1}^m r_k^2 / (n-k)The leading factor n(n+2) suggests that doubling n roughly doubles Q. The (n-k) in each denominator stops that from being exact. Holding the ACF values fixed, the exact old-to-corrected ratio over all m lags is
R_m = [n_raw(n_raw+2) / n_eff(n_eff+2)]
      * [sum r_k^2/(n_raw-k) / sum r_k^2/(n_eff-k)]
For the term of a single lag k, it simplifies to
n_raw(n_raw+2)(n_eff-k) / [n_eff(n_eff+2)(n_raw-k)]So n_raw / n_eff is only a large-n, small-lag approximation: useful when n is large compared with the lags. In the archived 400-versus-200 lag-one case, the approximation gives 2 and the exact single-term formula gives 1.985111293. That exact value depends only on the two counts, because a nonzero r_1^2 appears on both sides and cancels.
Figure 3 repeats this on the seeded series. Values are removed at five missing fractions, 0%, 10%, 25%, 50% and 75%, and each missing set contains the previous one. Each fraction leaves different survivors, so its ACF values can differ from the others. Within one fraction, the old and corrected calculations share the same ACF values; only the count changes.
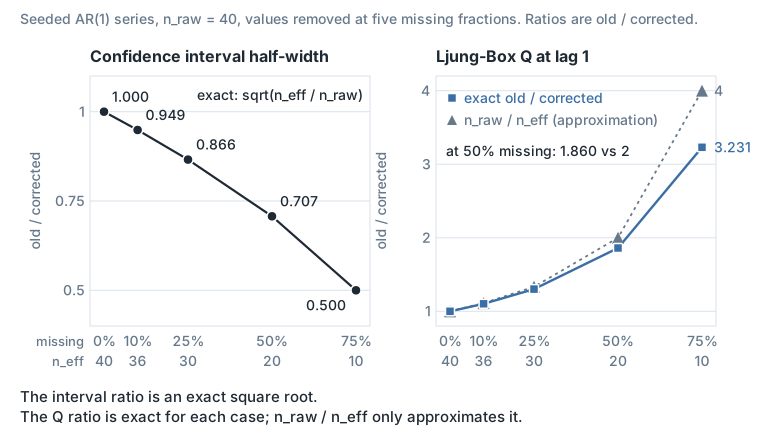
Figure 3. The interval ratio and the computed lag-one Q ratio are exact for each case. Only the n_raw / n_eff line is an approximation to the Q ratio.
Figure 4 keeps the fraction at 50% and changes the lag instead. It uses the same run as Figure 2. The interval ratio stays at 0.707 at every lag. The Q ratio is 1.86 at lag 1 and falls to 1.62 at lag 8, further from 2 as the lag grows, because of the (n-k) terms.
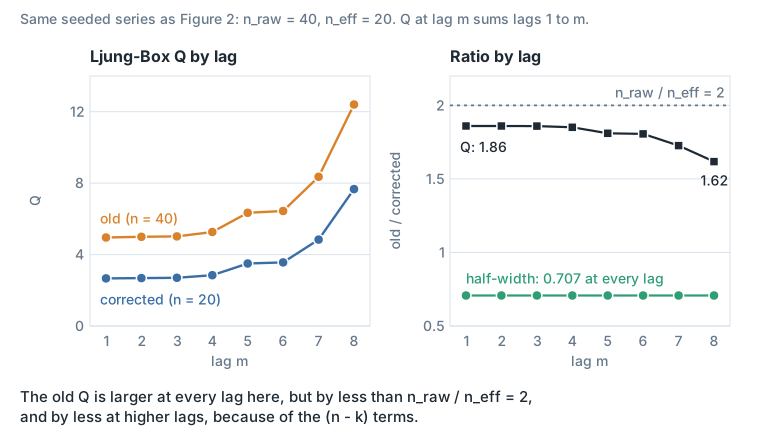
Figure 4. Half the values missing: the stale count inflates Q at every lag here, by a factor below n_raw / n_eff = 2 that shrinks as the lag grows.
In the archived 400-versus-200 lag-one case, in every lag-one case in Figure 3 with values missing, and at every lag in Figure 4, the stale larger count gave the larger Q. That direction is case-specific. The (n-k) terms can reverse the direction for some lag-and-count combinations. Against a fixed chi-square reference distribution, the p-value falls only when Q rises; if Q falls, the p-value rises. None of these calculations measures a false-positive rate. That would need simulations under a null model, across explicitly chosen ways for values to go missing.
The Q that qstat=True returns is also not a universal test for autocorrelation. It is the Ljung-Box statistic, returned as is. For testing the residuals of a fitted model, the dedicated acorr_ljungbox function supports an adjustment for the model’s degrees of freedom.
The fix
statsmodels PR #10017 made the same non-missing count reach every affected path. When the missing mode is drop or conservative, it passes the non-missing count to both interval options, Bartlett and non-Bartlett, and to q_stat. With none or raise, or when the input has no NaNs, the count stays as it was.
The patch added four regression tests checked against stored reference values: confidence intervals and Q statistics, for each of the two missing-data modes. A captured run of test_stattools.py at the tip of the fix reported 223 passing tests and 2 expected failures. Those checks show agreement with the stored references the patch covers.
The fix shipped in statsmodels 0.15.0; releases before it do not have it. When reproducing the before and after, check which version or commit you run.
Limits
The corrected count makes the calculations consistent with the documented convention. It does not settle these questions.
dropchanges the clock. Survivors are joined end to end, so gaps in time disappear. In Figure 1, positions 2 and 7 become neighbors. That is defensible only when this reading fits how the data was generated.conservativeis a different estimator. It keeps every value at its original position. With gaps in the middle andadjusted=True, the autocovariance at each lag can divide by that lag’s number of valid pairs, while the interval and Q still receive one overall non-missing count. The patch makes the count match the stated contract; it does not prove exact missing-data inference for this case.- The default number of lags uses the raw length. The default
nlagsis computed fromn_rawbefore the effective count is known, so with heavy missingness the returned arrays can be truncated. That was outside this patch.
Checklist
When a time-series diagnostic accepts missing values, check five things:
- Write down how the estimator treats gaps: delete them, keep their positions, impute them, or reject them.
- Track separately the sample count used by the point estimate, the standard error, the interval and the test statistic.
- Where the documented contract permits it, compare the missing-data path with an explicit reference transformation.
- Derive the expected ratio before trusting rounded output. Know which numbers are identities, which are approximations and which are just observed.
- Test the whole return tuple. Matching coefficients do not validate their intervals, Q statistics or p-values.
For this bug: under missing="drop", the library call and manual deletion should agree on the ACF, the confidence interval, the Q statistic and the p-value. Before the fix, only the ACF agreed.
Sources
- statsmodels documentation for
acf,acovf,q_stat, andacorr_ljungbox. - statsmodels PR #10017, the fix.
- M. S. Bartlett, “On the Theoretical Specification and Sampling Properties of Autocorrelated Time-Series” (1946), DOI
10.2307/2983611, with a 1948 corrigendum. This is the source for the large-sample sampling covariance behind the interval, and its1/nscaling. It is not evidence about how statsmodels handles missing data. - G. M. Ljung and G. E. P. Box, “On a measure of lack of fit in time series models” (1978), DOI
10.1093/biomet/65.2.297. This is the source for the modified portmanteau (multi-lag) statistic and its use in checking models.