TabPFN-TS forecasts a time series by turning it into an ordinary table and handing that table to TabPFN, a model pretrained on tabular prediction tasks. Some of the columns it adds describe time. One of them places the hour of the day on a circle. At the revision inspected here, that encoding divided by 23 where it should divide by 24, so hour 23 landed on top of hour 0.
The fix is to divide by the period. The project agreed the geometry was wrong, measured the fix, found in a 4-seed study that it made the shipped model measurably worse, and closed the issue and the pull request without merging. Three questions turned out to be separate: whether the encoding is mathematically correct, whether the change fits the pretrained model’s checkpoint (the saved, trained weights), and whether there is enough evidence to ship it in a release.
How TabPFN-TS builds its table
TabPFN is built for supervised prediction on tables. TabPFN-TS adapts it to forecasting by building a table from each series:
- Past target values (lags) become columns.
- Time information becomes columns.
- Other generated features become columns.
- Future target values are what the model predicts.
The public pipeline shows this conversion instead of hiding it behind a time-series-only interface. Each step is a transformation that can be inspected one column at a time.
A pinned main revision here means the exact commit of the project’s main branch that was inspected. The repository’s basic example creates a TabPFNTSPipeline, gives it a dataframe with item, timestamp and target columns, and asks for a forecast horizon (how many steps ahead to predict). Under that small API sits a feature pipeline. At the pinned main revision, the default list of time features is exactly RunningIndexFeature(), CalendarFeature(), and AutoSeasonalFeature(). Release v1.4.0 keeps those three and puts KnownCovariateLagFeature() in front of them. Either way, the calendar encoding feeds straight into the model input.
Thinking in tables forces some questions into the open:
- Which past values are available at the moment of the forecast?
- Which covariates (extra input variables) are really known in advance?
- Is a timestamp a running count, a category, a point on a circle, or several of these?
A pretrained model can bring a strong prior over tabular tasks, but it only sees the representation it is given. Once a timestamp becomes two numeric columns, the shape of those columns is part of what the model expects.
Tables also help with debugging. A suspicious forecast can be traced back through the generated feature table to the function that made a given column. So calendar geometry can be checked cheaply, without downloading a checkpoint or running a benchmark. Questions about model quality stay expensive.
Calendar columns have one useful property: they can be computed for future timestamps without seeing future targets. The forecast horizon already fixes which hours, weekdays or months its rows fall on. That context is modest. It says where a row sits in a cycle, not what will happen there. But it is in every row, so a small geometric defect repeats in every row, and any fix changes a model input across the whole horizon.
Encoding an hour on a circle
Raw hour numbers miss one pair of neighbors. On a number line, hour 23 is far from hour 0, yet they are neighbors across midnight. The usual fix places each value on a unit circle. For a period p and a zero-based value v (counting from 0), use
(sin(2πv/p), cos(2πv/p))
The order is (sin, cos) because that is the order the inspected code uses. Swapping the two only rotates or mirrors the picture. Changing the denominator changes which points exist.
Figure 1 shows the two columns for five hours around midnight, with the denominator the code uses (23) and the one the formula asks for (24).
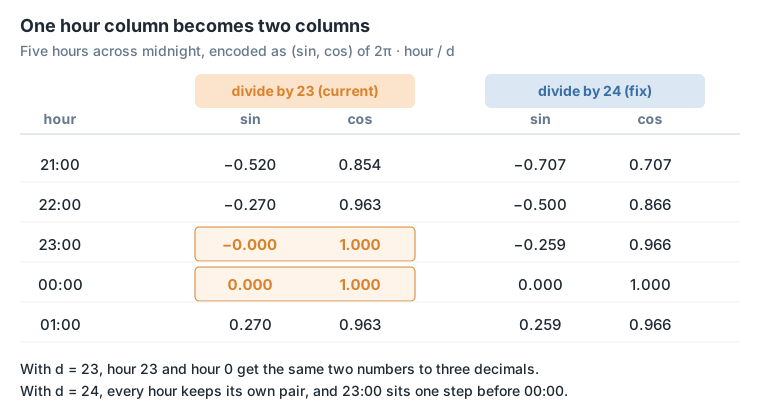
Figure 1. Each hour becomes a (sin, cos) pair. With the current divisor, 23:00 and 00:00 get the same two numbers to three decimals.
The circle gives a sharp test. Neighboring values should be equally spaced, including the wrap from the last value back to zero. With p values, each step is an angle of 2π/p, so the straight-line distance between neighbors (the chord) should always be
2 sin(π/p)
This equal-chord invariant is a stronger check than confirming that both columns hold numbers in [-1, 1]. It tests what the encoding is for: every tick moves one equal step around a cycle.
The right denominator follows from the input:
- The values are
0, 1, ..., p-1. - Dividing by
pgives angles from zero up to2π(p-1)/p. One more step would land back on zero, so the wrap is one ordinary step. - Dividing by
p-1gives the last value an angle of2π, which points in the same direction as the start.
That endpoint needs numerical care. In floating-point arithmetic, sin(2π) comes out as a tiny leftover, not exactly zero. So the two endpoints are different machine values. Under a practical absolute tolerance, though, they count as the same point. “Nearly coincident” is the accurate description; floating point did not make them exactly equal.
Checking the 24-hour case
The script below reproduces the 24-hour case with Python’s standard library only: no TabPFN install, no network. It groups points like this: walk through the hours in order, and keep a point as a new cluster only if it is more than 1e-9 away from every point already kept.
from math import cos, hypot, pi, sin

p = 24
atol = 1e-9

def encode(denominator):
    return [
        (sin(2 * pi * level / denominator), cos(2 * pi * level / denominator))
        for level in range(p)
    ]

def chord(left, right):
    return hypot(left[0] - right[0], left[1] - right[1])

def cluster_count(points):
    representatives = []
    for point in points:
        if not any(chord(point, representative) <= atol for representative in representatives):
            representatives.append(point)
    return len(representatives)

for denominator in (23, 24):
    points = encode(denominator)
    print(
        f"d={denominator}: 0->1={chord(points[0], points[1])}, "
        f"23->0={chord(points[23], points[0])}, clusters={cluster_count(points)}"
    )

print(f"signed sine at level 23 with d=23: {encode(23)[23][0]}")
d=23: 0->1=0.2723332981924932, 23->0=2.4492935982947064e-16, clusters=23
d=24: 0->1=0.26105238444010315, 23->0=0.26105238444010403, clusters=24
signed sine at level 23 with d=23: -2.4492935982947064e-16With d = 23, the 0→1 chord is 0.2723332981924932, but the 23→0 wrap chord is only 2.4492935982947064e-16, so the 24 hours form 23 clusters at atol = 1e-9 with rtol = 0 (an absolute tolerance only).
With d = 24, the 0→1 chord is 0.26105238444010315, the 23→0 wrap chord is 0.26105238444010403, and the same 24 hours form 24 clusters.
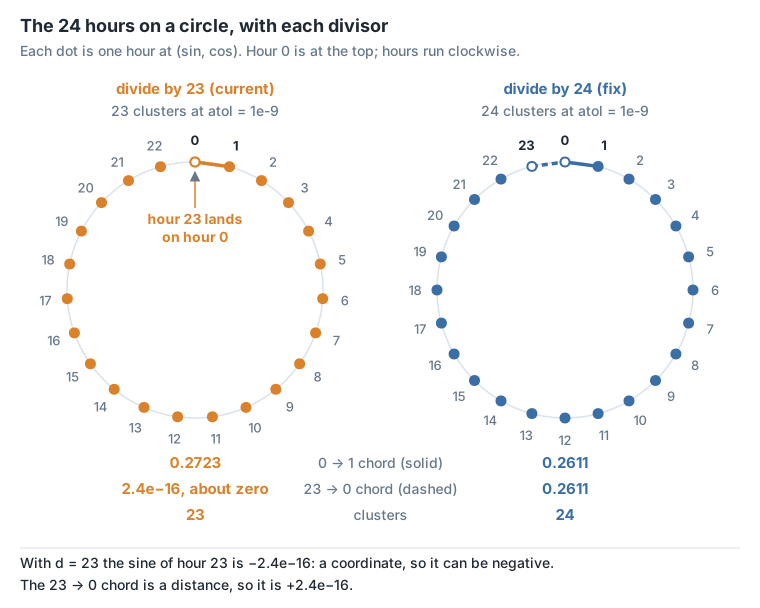
Figure 2. The same 24 hours, both divisors, same scale. Solid line: the 0 → 1 chord. Dashed line: the 23 → 0 chord.
Under d = 23, the sine coordinate of hour 23 is -2.4492935982947064e-16; the wrap chord, being a distance, is the positive 2.4492935982947064e-16. A coordinate can be negative because the point sits a hair to one side of an axis; a distance cannot.
Figure 3 applies the equal-chord test to all 24 steps. Dividing by 23 makes every ordinary step slightly too long and the wrap step almost zero. Dividing by 24 puts every step on the target.
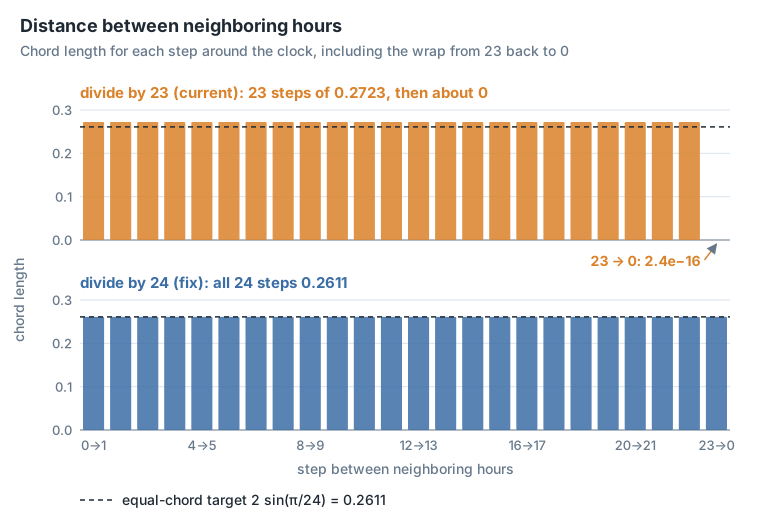
Figure 3. The equal-chord test, step by step. The dashed line is the target 2 sin(π/24).
Dividing by 24 gives the circle the encoding is meant to draw. It says nothing yet about how a pretrained model responds when one pair of its input columns moves.
Where the hour values come from
A denominator can only be judged against the values it receives. Here they come from GluonTS, whose time-feature functions return zero-based indices. The inspected project declares GluonTS v0.16.0 as its minimum version. That version’s source for this file and the separately checked v0.17.0 source are byte-identical, and both give the same ranges:
| Feature | Values |
|---|---|
| seconds, minutes | 0 to 59 |
| hours | 0 to 23 |
| weekdays | 0 to 6 |
| months | 0 to 11 |
So both GluonTS versions give hours as 0..23, and at the pinned main revision TabPFN-TS feeds them through the default CalendarFeature(), which divides by 24 - 1.
The path from dependency to code is short:
- The calendar feature takes the raw time value.
- It reads the declared period and subtracts one.
- It uses the result as the denominator in its sine and cosine angles.
The explainability code has a separate helper for partial-dependence values (the values behind a plot of how a prediction changes with one feature). It makes the same period-minus-one choice. An explainability test at the pinned main revision expects the hour grid to use 23.
Duplicated encoding logic matters because a fix can land in one copy and miss the other. Prediction and explanation must agree on where each hour sits. If an explanation plot uses a different transformation from the one used to predict, its feature axis no longer means what it says.
This also rules out an easy off-by-one defense. Dividing by 23 would be right for values 0..22, or for a deliberately closed curve that repeats its first point at the end. It does not space 24 distinct values 0..23 evenly. The input and the period have to be read together.
The proposed fix
I reported this edge case in issue #145 and proposed the fix in PR #146. The issue’s small reproduction checks the hour cycle and traces the denominator through the feature code, the explanation helper and the existing test. The PR divides by the declared period in both code paths, updating the explainability test, and adding regression tests for this case.
The proposed patch is one commit, changes four files with 50 additions and 3 deletions, updates the feature and explainer paths, and adds representative hour, weekday, and minute regression tests. A second commit, added to the PR later, only changed how tests that need credentials are skipped in the fork’s CI.
When the patch was written, the main revision was a756ae3fb3af82c903c39e1cd71864ff5252bc4d, the parent of the submitted patch commit 8e38bbd950781498e297171638fb51511b9eab60. That made the source comparison exact, but it signaled no approval.
For each of those periods, the tests ask two questions:
- Does each input value get its own coordinate after rounding?
- Does the wrap chord match the first ordinary chord within the stated tolerance?
Together they protect distinct points at the chosen precision and equal spacing. The weekday and minute cases show the tests are written to take any period, but they support no claim about calendar setups beyond the inputs they cover.
Before the patch, a focused run of the three new tests failed all three: 23 clusters instead of 24 for hours, 6 instead of 7 for weekdays, and 59 instead of 60 for minutes. After it, a focused run of selected tests ended with 15 passed and 1 deselected (left out by the selection). These two focused runs are the only test outcomes used here.
They show the new tests behave as intended in the captured setup. They do not replace the project’s CI, a model evaluation, or a release decision.
What the project measured
The account anuragg1209 triaged the issue for the project. Its public response reproduced the 24-to-23 collision, finding 23 distinct hour pairs at the tolerance instead of 24 under the current formula, agreed that for zero-based inputs the divisor should be the period, and applied the triaged label. The same response added that the collision is not exact in floating point and that TabPFN can still separate the two levels through that tiny difference, “so in practice there’s no hard information loss, just wrong geometry”.
The response also supplied a first A/B comparison. In the triage account’s public comment, one 12-dataset GIFT-Eval A/B of the true-period divisor (dividing by p) versus the period-minus-one divisor (dividing by p - 1) was approximately +0.6% on MASE (mean absolute scaled error) and +1.3% on weighted quantile loss, on average; lower is better for both. In other words, dividing by the true period came out slightly worse.
The same comment reports every per-dataset MASE change within ±2.5%. It also shows a condition with angular noise U(-0.2π, 0.2π) (noise drawn uniformly from that range of angles), but where that noise is applied, how finely it is sampled, the seeds, the complete configuration, and its relation to training all remain unknown.
These are rounded figures; the per-dataset tables are images.
That first comment said the project did not want to merge an inference-only change yet, and would check across multiple seeds whether the difference was significant or just noise. On 2026-08-14 it posted the result: a 12-dataset GIFT-Eval A/B with 4 seeds per configuration and a Welch’s t-test per dataset, identical in every respect except the divisor. Its conclusion was that “the inference-only fix measurably regresses the shipped model”. The project closed issue #145 for two reasons, no hard information loss in practice and that regression, and closed PR #146 the same day, “not because the change is wrong”. Its per-dataset results are also posted as an image.
At the first check, the latest release was v1.2.0 at revision 73a134f1dc1ded17d2c079c11c137faa8be58d56, and its CalendarFeature source at that fixed revision retains the period-minus-one implementation. Release v1.4.0, published on 2026-10-28, still divides by the period minus one, in both CalendarFeature and the explainability helper.
The first A/B left two explanations open for why a geometrically correct input could make an existing checkpoint worse:
- Compatibility. A model trained with one coordinate system can react to a shift in its input coordinates in ways the encoder alone cannot predict.
- Ordinary variation across datasets and runs.
The seeded study with a significance test is the project’s answer to the second. Its closing comment says the investigation “taught us something real about featurization/checkpoint coupling”, which points at the first. The same comment says “The report was correct”. The public record still does not show which calendar encoding was used in training.
Three separate questions
Each question needs different evidence:
- Geometry - proved. Check the input values, the denominator, the equal-chord invariant, the tolerance and the regression tests.
- Checkpoint compatibility - unknown. Identify the evaluated checkpoint and the encodings used in its training and at inference before treating a coordinate change as leaving the model’s behavior unchanged.
- Paired multi-seed release evidence - pending. Re-run both encodings on the same data splits and several random seeds, keep the raw predictions, report uncertainty, and only then decide whether a release should change.
Those were the answers when this post was first written, on 2026-08-08. The project’s second study changed the third:
| Question | 2026-08-08 | 2026-10-29 |
|---|---|---|
| Geometry | proved | proved, and the project agreed |
| Checkpoint compatibility | unknown | training encoding not public; the project points to featurization/checkpoint coupling |
| Paired multi-seed release evidence | pending | run by the project: 4 seeds, Welch’s t-test per dataset, a regression |
The pinned sources and the small script settle the first question without any model weights. The second needs the record of how the checkpoint was trained and run. The third needed an experiment with seeds and a significance test, and the project ran one.
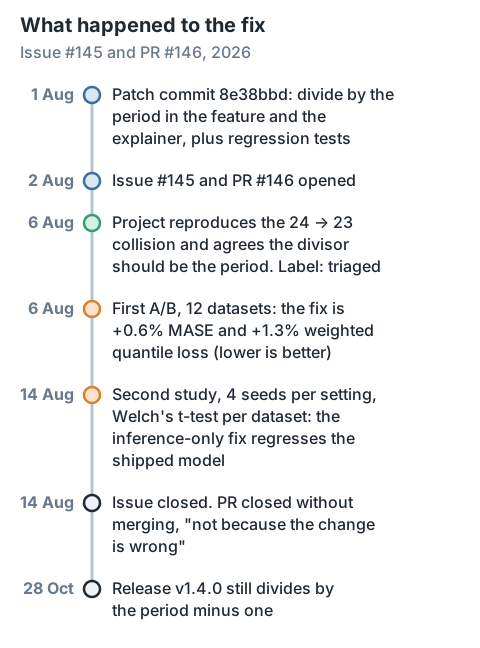
Figure 4. From patch to closed issue. The geometry was accepted; the change was not shipped.
The same split applies elsewhere. A tokenizer repair, a normalization change, a category remapping or an image preprocessing fix can be right at the representation level and still be risky for a model trained or evaluated under the old convention.
Open questions
The evaluation has a checkpoint axis. Should it only swap the inference encoder around the existing checkpoint, or also include a checkpoint retrained or fine-tuned with matched training and inference geometry? The public record does not answer that. The project’s study tested the first option: the inference-only swap. The second asks whether matched geometry in training and inference behaves differently. Their results should be kept apart, because they test different interventions.
The duplicated helper raises a smaller engineering question that needs no benchmark: can prediction and explanation call one shared calendar transformation, so their coordinates can never drift apart? That refactor is separate from the divisor decision, and easier to test on its own.
Primary sources
- TabPFN-Time-Series repository
- README at pinned main revision
- Pipeline at pinned main revision
- Project metadata and dependency floor at pinned main revision
CalendarFeatureat pinned main revision- Explainability helper at pinned main revision
- Explainability test at pinned main revision
- Issue #145
- Project-reported reproduction and A/B comment
- Project’s 4-seed study and closing comment
- PR #146
- PR #146 closing comment
- Submitted patch commit
- Submitted calendar regression tests
- TabPFN-Time-Series v1.2.0 release
CalendarFeaturein v1.2.0- TabPFN-Time-Series v1.4.0 release
CalendarFeaturein v1.4.0- Explainability helper in v1.4.0
- Pipeline in v1.4.0
- GluonTS v0.16.0 time-feature source
- GluonTS v0.17.0 time-feature source