Two studies seem to disagree about tuning LightGBM. In High Per Parameter, six LightGBM rows all reported the same median improvement from tuning: 0.0%. In TabArena, tuning moved LightGBM from 1197 to 1446 Elo (a leaderboard rating, higher is better), at approximately 212.745 times the reported training time per 1,000 rows. The two measured different kinds of tuning, so they do not conflict.
Checking a tuning result also costs fits. In the nested design proposed below, with five outer folds, an early-stopped baseline needs 30 model fits, a 16-trial search needs 255, and a 64-trial search needs 975. The gain from the search, measured on data the search never touched, has to be worth that cost.
My approach: start with a split and metric that match how the model will be used, sensible tree sizes, and early stopping. Then run a small, targeted search, and grow it only when evidence that never touches the held-out data says so. The held-out results, taken together, decide whether the whole procedure is worth deploying. The nested experiment below has not been run; it is what would tell you which published case your problem resembles.
The first section covers how LightGBM works and which parameter acts on which step. The case study is a small search I ran by hand on one sales series.
How LightGBM works
Each parameter in a search acts on one step of how LightGBM builds its model, which tells you what it can change and what it cannot. The companion post goes through the whole deck, from a single decision tree to random forests to LightGBM’s categorical splits.
Boosting
LightGBM is a library for gradient-boosted decision trees. A decision tree asks a chain of yes-or-no questions about the features, such as “is the price above 4.2?”, and ends in a leaf that holds a number: the prediction.
- Boosting trains trees sequentially, each one correcting the errors of the trees before it. The first tree makes a rough prediction. Each next tree is fitted to what the trees so far still get wrong. For squared error, that is the residual: actual minus predicted. In general it is the negative gradient of the loss (the direction in which a small change to the prediction lowers the loss fastest), which is where “gradient boosting” gets its name.
- The learning rate scales the contribution of each tree: each new tree’s output is multiplied by it before it is added. With a rate of 0.1, each tree moves the prediction a tenth of the way it suggests. Small steps need more trees. LightGBM’s parameter-tuning guide lists “small
learning_ratewith largenum_iterations” under better accuracy. - To control how many trees you build, use early stopping and an evaluation set. More trees keep lowering the error on the training rows. At some point they start fitting noise, and the error on held-out rows rises again. Early stopping watches a validation set and keeps the round where that error was lowest. That is why the baseline later in this post gets early stopping too.
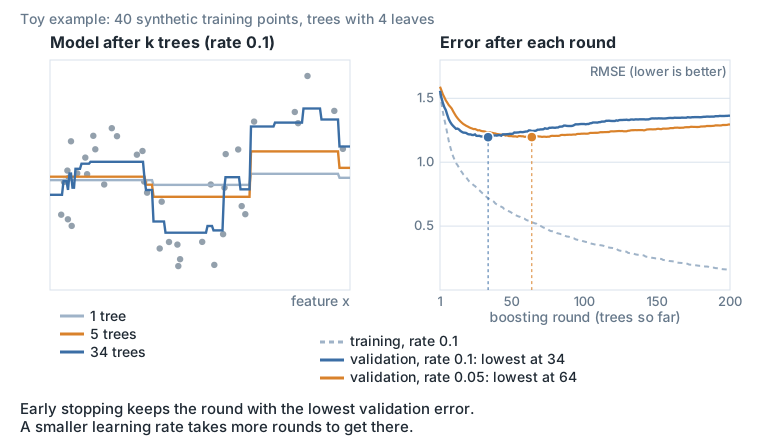
Figure 1. A toy example computed on 40 synthetic points, not real data. Training error keeps falling. Validation error is lowest at round 34 with a learning rate of 0.1, and at round 64 with 0.05.
Leaf-wise tree growth
- Most tree learners grow a tree level by level: split every node at one depth, then go one deeper. LightGBM grows leaf-wise instead. At each step it splits the one leaf whose split lowers the loss the most, wherever that leaf is.
- With the same number of leaves, leaf-wise trees tend to reach a lower loss. They also grow deep in a few places, which can overfit when there is little data, so they need regularization.
So the main capacity knob is the number of leaves, not the depth. The tuning guide calls num_leaves “the main parameter to control the complexity of the tree model”. min_data_in_leaf refuses a split that would leave a leaf with too few rows, and the guide calls it “a very important parameter to prevent over-fitting in a leaf-wise tree”. max_depth still exists as a hard cap, and it limits how many features one path from root to leaf can combine. If you set it, keep num_leaves below 2^max_depth: the guide’s example is that matching it exactly (127 leaves at depth 7) may overfit, while 70 or 80 may do better.
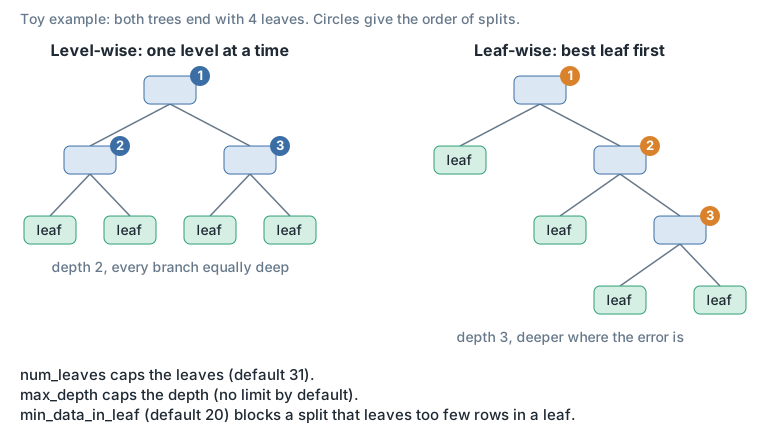
Figure 2. A toy example. Both trees have four leaves. The leaf-wise tree spends its splits where the error is, so it ends up deeper on one side.
Histogram based splitting
Problem:
- To choose a split, a tree learner tries candidate thresholds on every feature. A pre-sorted learner sorts each feature and tries the gap between every pair of neighbouring values.
Solution:
- LightGBM first puts each feature’s values into at most
max_binbins, 255 by default. When a feature has more distinct values than bins, the bin edges are placed so that each bin holds a similar number of rows, rather than at equal widths. - This binning is done once, when the dataset is built, and every tree reuses it.
- During training, LightGBM only adds up the gradients that fall in each bin. Then it tries the bin edges as thresholds.
- Histograms for different features are independent, so LightGBM builds them in parallel across CPU cores.
This saves work in two places. Building a histogram takes one pass over the rows, and scanning it takes one step per bin, far fewer than the rows. And a leaf’s histogram can be computed as its parent’s histogram minus its sibling’s, so only the smaller child is built from the rows. The downside: a split can only fall on a bin edge. The tuning guide lists a large max_bin under better accuracy and a small one under dealing with over-fitting.
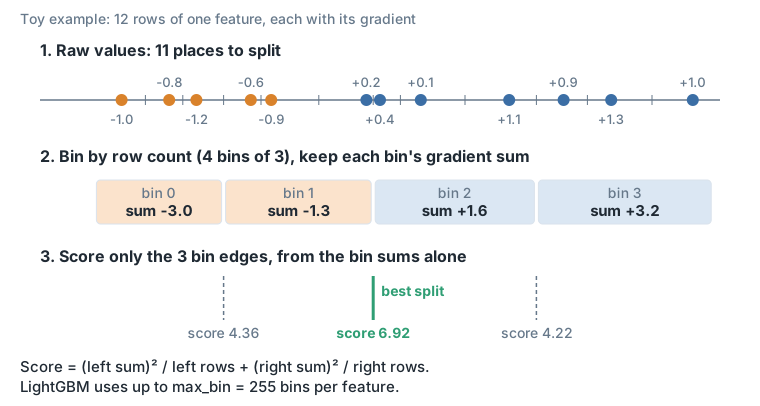
Figure 3. A toy example. Three bin edges are scored instead of eleven gaps. The score is the LightGBM paper’s variance gain, up to a constant factor.
Gradient based one side sampling (GOSS)
GOSS and exclusive feature bundling are the two ideas the 2017 paper that introduced LightGBM added on top of histograms. Both shrink the data each histogram has to cover. GOSS uses fewer rows.
Problem:
- Every training row is used to find the best split.
- Rows with a large gradient are the ones the model still gets badly wrong, and they matter most when choosing a split.
Solution:
- GOSS keeps the top
ashare of rows by gradient size. From the rest, it draws a random sample the size of abshare of all rows, and counts each drawn row(1 − a) / btimes, so the small-gradient rows keep roughly their total weight. - In LightGBM, GOSS is off by default. Since version 4.0 it is chosen with
data_sample_strategy="goss", as the alternative to ordinary bagging, with defaultstop_rate=0.2andother_rate=0.1.
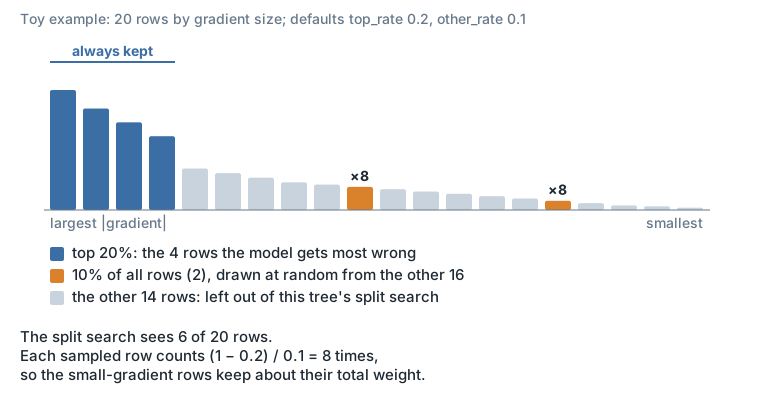
Figure 4. A toy example with LightGBM’s default rates. Six of twenty rows reach the split search. The two sampled rows each count eight times.
Exclusive feature bundling (EFB)
EFB uses fewer columns.
Problem:
- Sparse data often has columns that are rarely non-zero on the same row, such as the one-hot columns made from one category.
Solution:
- EFB merges such columns into one, and gives each original column its own range of bins, so their values can still be told apart.
- Finding the best bundling is NP-hard (no known method is fast on large inputs), so the paper uses a greedy approximation. It can also allow a small share of overlap, trading a little accuracy for fewer bundles.
- LightGBM bundles by default (
enable_bundle=true).
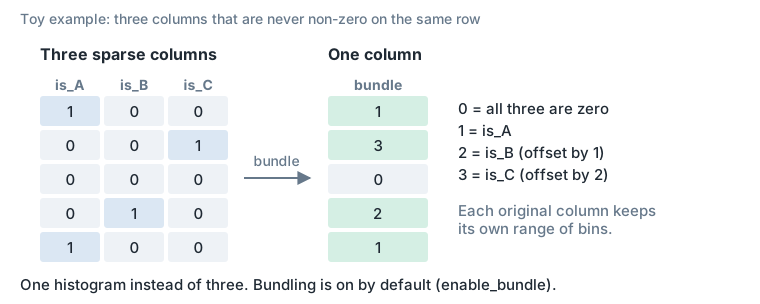
Figure 5. A toy example. Three columns that are never non-zero together become one, so one histogram replaces three.
In the paper’s five benchmarks, adding the two to LightGBM’s own histogram algorithm cut training time per iteration by 1.6 to 21 times, with almost the same accuracy. Neither is a knob that the search below tunes. They make each fit cheaper, so each search trial is cheaper too.
Parameters
LightGBM’s parameters split into the modeling setup (objective, boosting), those that control the ensemble training, such as the number of trees and the learning rate, and those that control the growth of each tree.
| Step | Knobs | What they change |
|---|---|---|
| Boosting | learning_rate, number of trees, early stopping | the step size and how many trees are added |
| Tree shape | num_leaves, max_depth, min_data_in_leaf, min_gain_to_split | how much each tree can fit |
| Leaf values | lambda_l1, lambda_l2 | how far each leaf’s output is pulled toward zero |
| Rows and columns | bagging_fraction with bagging_freq, feature_fraction | which random part of the data each tree sees; smaller fractions also train faster |
| Histograms | max_bin | how finely a split can be placed |
| The loss | objective, boosting | what the trees minimise, and the boosting variant |
In a linear model, L1 and L2 regularization apply to the feature coefficients. In LightGBM, the two regularization knobs act on leaf values, not on features. In LightGBM’s source, a leaf’s value is minus its summed gradient divided by its summed second derivative plus lambda_l2. So lambda_l2 pulls every leaf toward zero. With squared error, where each row adds one to that denominator, leaves backed by few rows are pulled the most. lambda_l1 first shrinks the summed gradient toward zero by lambda_l1, so a leaf with a small summed gradient gets a value of exactly zero. Unlike L1 in a linear model, it does not drop features.
The objective is the loss the trees minimise. The default, regression, is squared error, which aims at the mean. regression_l1 is absolute error, which aims at the median and is less sensitive to outliers than squared error. quantile predicts a chosen quantile instead of the mean, which can be used to build prediction intervals, and gamma and mape are also available. poisson and tweedie use a log link and fit non-negative targets such as counts. With a variance power between 1 and 2 (LightGBM’s default is 1.5), the Tweedie distribution puts a point mass at zero and is continuous above it.
boosting="dart" is a variant that leaves out a random subset of the earlier trees when working out what the next tree should fit, an idea borrowed from dropout in neural networks. The tuning guide lists “Try dart” under better accuracy. It is slower per round: LightGBM’s DART code subtracts the dropped trees from the running predictions and adds them back rescaled, work plain boosting does not do. As noted later, early stopping does not apply to it, so the number of trees has to be fixed another way.
The search proposed later in this post draws six of these knobs: learning_rate, num_leaves, min_data_in_leaf, feature_fraction, bagging_fraction (with bagging_freq fixed at 1), and lambda_l2. The objective is not searched. It belongs to the sensible baseline, chosen to match the problem before tuning starts.
Tuning and selection bias
A search returns the best of its candidates. Give it 64 noisy scores and it returns the largest, even if all 64 candidates are truly equally good. The top score is model quality plus validation noise. A bigger search gives noise more chances to win.
Cawley and Talbot studied this as selection overfitting: the noise in the score used to pick a model can itself be overfit. The resulting loss was sometimes as large as the reported differences between algorithms. So tuning is an adaptive procedure, and all of it, search included, needs evaluating.
That is what nested cross-validation (CV) does. Ordinary CV splits the data into folds, trains on all but one, scores on the one left out, and rotates. Nested CV puts one CV inside another. The outer folds hold data back. Inside each outer-training part, inner folds compare the candidates. Each outer holdout is scored once, at the end.
The useful question is how much the whole procedure beats the baseline, fold by fold, when it is scored on outer folds it never saw, not whether one trial beat another on the inner folds. The procedure includes preprocessing, split logic, objective, metric, early stopping, search space, trial count, pruning policy, seed policy, candidate selection, refitting, and how predictions are combined. Changing any of them changes what is measured.
There is also a product question. A small AUC gain can be worth a lot in a high-volume ranking system and nothing in a low-volume workflow. Flat accuracy can hide a useful change in calibration or latency. And a benchmark gain can vanish once the split respects time, or customers, hospitals, devices, or other entities that appear more than once. Set the smallest useful gain for each problem, in business units.
“Hyperparameter optimization (HPO) worked” is therefore an incomplete result. A tuning result has to state the baseline, the split, the search and validation cost, and whether the score is inner or on untouched data.
Case study: hand-tuning one series
In a deck I prepared on LightGBM, I tuned it by hand on a single series: one product’s weekly sales at one location, with roughly the last year of weeks marked as the test set. Sales were low and intermittent, with many zero weeks. The error measure was WAPE (weighted absolute percentage error): the total absolute error divided by the total actual sales. Lower is better. The numbers depend on the dataset, so each result is given relative to the default run (learning_rate=0.1, default squared-error objective).
Learning rate influence:
learning_rate=0.2raised the error by about 3% against the default.
Objective influence:
tweediecut the error by about 3% against the default.- L1 (
regression_l1) cut it by about 3%. - L2 gave the same error as the default. In LightGBM,
regressionandl2are two names for the same objective.
Hand-picked settings cut the error by about 5% against the default:
- 200 trees,
learning_rate=0.05,num_leaves=20,min_data_in_leaf=20 feature_fraction=0.7,bagging_fraction=0.8withbagging_freq=1lambda_l1andlambda_l2of 0.05objective='tweedie'
DART cut the error by about 13% against the default:
- 200 trees,
learning_rate=0.08,objective='tweedie',boosting='dart'
DART was the best.
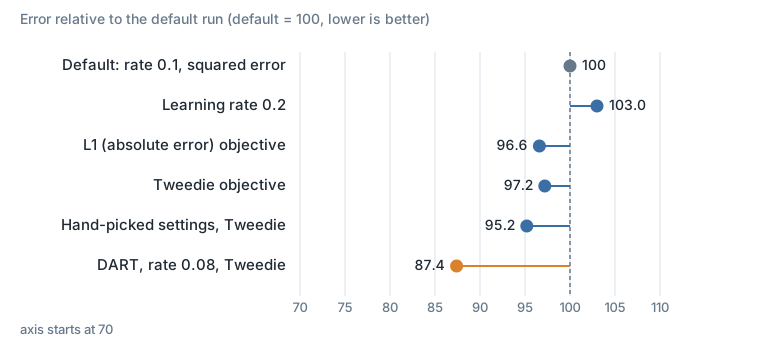
Figure 6. Six configurations on one series, from my deck. Each run’s WAPE is divided by the default run’s, times 100, so the default is 100 and lower is better. The axis starts at 70.
On the same series, the deck also reports a single decision tree and a random forest. Against the default LightGBM run, the tree of depth 20 had about 9% lower error (about 5% and 4% higher at depth 1 and 5), and the random forest had about 16% higher error with 100 trees (about 28% higher with 5). The companion post walks through those trees and forests step by step.
In the terms of the previous section, this is a search over six configurations, each with one score on one series, and DART’s result is the best of six scores, so it is the score selection is most likely to flatter. Both final configurations also list a fixed 200 trees, and DART cannot use early stopping at all. The rest of this post asks how much of DART’s gain would hold on unseen weeks.
What “default LightGBM” means
- Raw package defaults. The settings the library ships with. A reproducible control, not a claim about the best configuration for deployment.
- A sensible baseline. The right objective and metric, a split that matches deployment, reasonable tree complexity, a high cap on boosting rounds, and early stopping.
- A targeted search. A small budget spent on settings that interact: capacity, sampling, and regularization.
- Broad HPO and ensembling. Chases peak benchmark performance, and pays a correspondingly larger bill for selection and compute.
The question I care about is what steps three and four add on top of step two. Comparing step four only with step one measures something else: how much careful search improves an untailored package configuration.
Keeping them apart also stops early stopping from becoming a hidden advantage. If the tuned model gets to find a good number of rounds but the baseline is stuck at an arbitrary n_estimators, part of what the search buys is just the round count. A fair baseline gets the same chance: set a high ceiling, watch the declared validation metric, freeze the best round by a rule fixed in advance, and refit without looking at the outer holdout.
A common recipe in gradient-boosting tutorials runs in three steps: set the number of trees very high, grid-search the tree settings, then raise the number of trees again while lowering the learning rate. Early stopping does the first step automatically, and the last step matches the tuning guide’s advice to pair a small learning rate with many iterations. The grid search in the middle is a selection step like any other: its best score is optimistic until it is checked on data the search never touched, which is what the protocol below is for.
LightGBM’s official early-stopping callback stops when the validation metric fails to improve by at least min_delta for stopping_rounds rounds, and records the best iteration. Early stopping does not apply to boosting_type="dart". As the tour above showed, the tuning guide names num_leaves as the main control on model complexity and min_data_in_leaf as an important guard against overfitting, and a max_depth limit has to stay consistent with the leaf count.
With the round count handled by the baseline, the search only has to test whether capacity, row or feature sampling, and regularization improve the outer-fold score by enough to matter.
High Per Parameter
The High Per Parameter paper (also on arXiv) measured tuning gains across a large grid of experiments, LightGBM among them. It covered 26 algorithms, 250 datasets, six metrics, 96,192 replicates, and 28,857,600 reported algorithm runs. Each algorithm-dataset pair got 30 random 70/30 train/test splits. Random splits treat every row as an independent draw from the same distribution (IID), so this is an IID-style evaluation, not evidence that the real data was IID. For each metric, tuning ran 50 Optuna TPE trials, each scored by five-fold CV. Package defaults were also evaluated 50 times, and the model with the best CV score was kept.
So the comparison is a narrow one: 50-trial HPO against package defaults, not HPO on top of the early-stopped baseline proposed here. Every reported LightGBM median was 0.0%. The spreads reported with them are standard deviations, not confidence intervals: they describe how much results varied, and leave room for large wins and losses on particular datasets. For classification, the published search space lists bagging_fraction but no bagging_freq. LightGBM only uses a bagging fraction below one when the bagging frequency is nonzero. The paper does not report one: activation is undocumented, and bagging_fraction may have had no effect.
The improvement from tuning over package defaults, per LightGBM row:
| Model | Metric | Median | Mean ± SD | Replicates |
|---|---|---|---|---|
| Classifier | Accuracy | 0.0% | 1.2% ± 11.5% | 4,287 |
| Classifier | Balanced accuracy | 0.0% | 1.0% ± 11.9% | 4,287 |
| Classifier | F1 | 0.0% | 0.9% ± 12.1% | 4,287 |
| Regressor | R² | 0.0% | 0.0% ± 25.6% | 3,179 |
| Regressor | Adjusted R² | 0.0% | −1.2% ± 34.4% | 3,179 |
| Regressor | Complement RMSE | 0.0% | 0.4% ± 2.1% | 3,179 |

Figure 7. High Per Parameter: a narrow 50-trial comparison against package defaults, on random 70/30 IID-style splits. The default side kept the best-CV model from 50 default evaluations, and classifier bagging activation is undocumented. This is not the sensible baseline proposed here, and the wide spread leaves room for gains and losses on particular datasets.
Two summaries of the plot are wrong. “The medians are zero, so search cannot help” ignores the tails. “The means are positive, so search usually pays” ignores the zero medians and the very large spread. What the data supports is narrower: in these LightGBM experiments, the typical reported gain from tuning was zero, while particular datasets could behave very differently.
The datasets were small to medium. The 144 classification datasets had at most 10,992 rows and 100 features; the 106 regression datasets had at most 8,192 rows and 100 features. The search spaces were narrow. The classifier search tuned n_estimators (log scale, 10 to 1,000), learning_rate (linear, 0.01 to 0.2), and bagging_fraction (linear, 0.5 to 0.95). The regressor search tuned lambda_l1 and lambda_l2 (log scale, 1e-8 to 10) and num_leaves (integer, 2 to 256).
So the study does not cover data that shifts over time, grouped entities, very large data, or many parameters interacting. It supports starting with a capped budget. It does not say where every search must stop.
TabArena
TabArena is a case where tuning LightGBM wins clearly. The benchmark picked 51 datasets from 1,053 candidates, evaluated 16 models, and fitted roughly 25 million model instances. Each tunable model was tried with one default plus 200 random configurations; TabICL and TabDPT were left out of that search. Scoring used three-fold CV, repeated ten times for datasets below 2,500 rows and three times otherwise.
| LightGBM | Elo | Normalized score | Average rank (lower is better) | Reported train seconds per 1,000 rows |
|---|---|---|---|---|
| Default | 1197 | 0.088 | 25.3 | 1.96 |
| Tuned | 1446 | 0.359 | 13.2 | 416.98 |
| Tuned and ensembled | 1527 | 0.448 | 9.9 | 416.98 |
The tuned regime’s reported training time is approximately 212.745× the default’s.

Figure 8. TabArena’s 200-configuration search shows a strong tradeoff between predictive performance and reported training time. These are three regimes from a public IID benchmark, not a local cumulative-trial curve, and not a universal production budget.
The knobs matter here: tuning gained 249 Elo points and moved the average rank 12.1 places. Peak benchmark performance also costs far more training time. The time figure is reported training time per 1,000 rows under the benchmark’s setup. It does not transfer to other hardware or another pipeline.
The time axis is logarithmic and the Elo axis runs only from 1100 to 1600, so read the gaps from the axis labels, not from how far apart the points look. The tuned and tuned-plus-ensembled points share the same reported time in the source table. The three points are separate regimes, not a curve. They do not show what happened at trial 16, 25, or 64.
TabArena-Lite presents 25 configurations as a cheaper optional screen for a new model when the full benchmark is impractical. That does not make 25 a general rule for LightGBM. A small budget still needs a rule for when to grow it.
The baseline
Early stopping means the baseline makes a choice too: the number of rounds. So it gets the same treatment as the search. In each outer fold, the baseline sees only the outer-training data. It uses the same three inner folds as the search, and each inner fold yields a best iteration. The median of those three becomes a fixed number of rounds. The baseline is then refit on all the outer-training data with three declared seeds, the three sets of predictions are averaged, and the untouched outer holdout is scored once.
The baseline and the search get the same treatment. If the search gets three refit seeds and the baseline gets one, run-to-run variation can pass for a tuning gain. If the baseline’s round count is picked on the outer holdout, the comparison is contaminated before the first trial. If the seeds themselves are searched, they become another hyperparameter and count against the budget.
The split should also match how the data arises. Repeated entities call for group-aware folds, which keep each entity on one side of the split. A model that will forecast calls for rolling-origin evaluation: train on the past, test on what comes after. Any preprocessing that learns from data is fitted inside each training part. The inner folds keep the same time or grouping restrictions as the outer folds.
Choose the metrics here, not at the end. If probabilities drive a decision, a search on accuracy alone can pick a model with poor probabilities. Report log loss, Brier score, and reliability next to the search objective; boosted methods can need calibration, as Niculescu-Mizil and Caruana showed. A ranking system needs its metric at the depth it actually serves. A decision made at a threshold needs expected cost or utility at that threshold. Latency, model size, behavior on subgroups, and variation across folds or seeds can each veto a tiny gain on the main score.
This costs more than a single train/validation split, because it measures the whole procedure. A tuning budget should therefore count validation fits, not just search trials.
Better by Default
The NeurIPS 2024 paper Better by Default asks whether tuning across many datasets at once can produce better starting settings. It learned its defaults on 118 datasets and tested them on a separate 90-dataset benchmark containing 1,000 to 500,000 samples. On the datasets the defaults were learned from, they were competitive with tuning each split. On the separate test datasets, the gap reopened. Picking among strong default models gave an attractive tradeoff between time and performance, but the defaults did not transfer perfectly.
The evaluation setup: LightGBM 4.1.0; ten random 60/20/20 train-validation-test splits per dataset; 50 random HPO configurations per split; one validation split per train-test split; accuracy for classification and RMSE for regression; and numerical rows with missing values removed.
The published candidate defaults:
| Parameter | Classification | Regression |
|---|---|---|
num_leaves | 50 | 100 |
learning_rate | 0.04 | 0.05 |
subsample | 0.75 | 0.70 |
bagging_freq | 1 | 1 |
colsample_bytree | 1.0 | 1.0 |
min_data_in_leaf | 40 | 3 |
min_sum_hessian_in_leaf | 1e-7 | 1e-7 |
max_bin | 255 | 255 |
n_estimators | 1000 | 1000 |
early_stopping_rounds | 300 | 300 |
The bagging_freq=1 row is essential. In LightGBM, a subsample below one has no effect while the frequency stays at zero. Copying the fractions without it changes the candidate. The exact PyTabKit v1.0.0 snapshot also pins the dependencies and the split setup. To reproduce them, use that snapshot, not only the table.
The raw control is separate: LightGBM 4.7.0’s scikit-learn defaults, which are num_leaves=31, max_depth=-1, learning_rate=0.1, n_estimators=100, min_child_weight=0.001, min_child_samples=20, subsample=1, subsample_freq=0, colsample_bytree=1, reg_alpha=0, reg_lambda=0, and max_bin=255. The estimator infers the objective, and these raw defaults do not turn on early stopping.
Keep the three apart: the 4.1.0 values are candidate strong defaults under the paper’s setup, the 4.7.0 values are a current raw control, and the sensible baseline is a proposed procedure that still needs its own objective, metric, split, and early stopping for each dataset. None of the three is a recipe for every dataset.
Proposed experiment
I would compare three budgets, all on the same frozen preprocessing and outer splits: the sensible early-stopped baseline, 16 targeted configurations, and 64 configurations, reached only when the inner evidence clears a useful-effect threshold declared in advance. A 200-trial run can stay a research upper bound for high-value cases. The first measurement should show whether the gains deserve that expense.
This protocol has not been run. The dataset, target, split strategy, primary metric, useful-effect threshold, constraints, and hardware are all unspecified. Every local result is therefore null (not measured), which is not the same as zero.
Use a prefix-stable random search with seed 20260808: the small search is exactly the start of the large one. The exact random-number generator and sampler are not yet specified and must be pinned before a run. Log-uniform means each order of magnitude in the range is equally likely. The draws:
learning_rate: log-uniform on [0.01, 0.2]num_leaves: log-uniform integer on [15, 255]min_data_in_leaf: log-uniform integer on [3, 256]feature_fraction: uniform on [0.6, 1.0]bagging_fraction: uniform on [0.6, 0.95], withbagging_freqfixed at 1lambda_l2: exactly zero 20% of the time, otherwise log-uniform on [1e-8, 10]
Generate 64 configurations once. The 16-trial run uses exactly the first 16; expansion adds the remaining 48 without redrawing.
The other fixed settings: five outer folds and three inner folds; trial budgets of 16 and 64; no pruning (no trial is abandoned partway for looking unpromising); an iteration ceiling of 10,000; early_stopping_rounds=300; min_delta=0; refit seeds 17, 29, and 47; and no search over seeds.
To pick a winner, turn the declared metric into a score where higher is better. Take the candidate with the largest arithmetic mean across the three inner folds, and break ties within 1e-12 by the lower trial index. Freeze the median of its three best iterations. Refit with the three seeds and average the three sets of predictions before scoring. The outer holdout is scored once per procedure per fold, and it cannot decide whether the budget grows.
For classification, the average is the arithmetic mean of the predicted probabilities; for regression, the mean of the predictions. This rule is fixed before any holdout score exists.
The cost in fits: in each outer fold, every candidate is fit once per inner fold, and the winner is refit three times. Across five outer folds, the baseline costs 5 × (3 + 3) = 30 fits; 16 trials cost 5 × (16 × 3 + 3) = 255; 64 trials cost 5 × (64 × 3 + 3) = 975.
outer_folds = 5
inner_folds = 3
refit_seeds = (17, 29, 47)

baseline_fits = 5 * (3 + 3)
targeted_16_fits = 5 * (16 * 3 + 3)
expanded_64_fits = 5 * (64 * 3 + 3)

assert outer_folds == 5 and inner_folds == 3 and len(refit_seeds) == 3
assert (baseline_fits, targeted_16_fits, expanded_64_fits) == (30, 255, 975)
Figure 9. The proposed protocol, which has not been run. Across five folds it needs 30, 255, and 975 fits for the baseline, 16-trial, and 64-trial runs. Only inner-CV evidence can open the expansion branch; the outer holdout never opens it.
Only inner-CV evidence may expand the search from 16 to 64 trials. The outer holdout is scored once after the adaptive inner procedure finishes. Once every outer fold is done, the final decision rests on the paired outer differences (tuned minus baseline on the same fold), not on the best inner score.
Inner and outer scores
The winner’s inner improvement minus its outer improvement estimates selection optimism: how much the search’s own score overstated the gain. A large inner lift with little outer lift suggests the search picked up validation noise. Plot both by outer fold or by dataset, so the gap is visible instead of hidden in an average.
Varma and Simon’s nested-validation study supports the general conclusion: putting feature and parameter selection inside a nested procedure can remove selection bias. Its SVM numbers disagree between the abstract and the table, so this post quotes no exact SVM percentage.
Nested CV is not always needed. Wainer and Cawley tested 12 algorithms on 115 real binary datasets. When only a few hyperparameters were tuned, flat (non-nested) CV generally selected a practically similar algorithm. Their paper keeps nested evaluation as the safer way to measure an adaptive procedure, without requiring it for every low-stakes choice among a handful of configurations.

Figure 10. A future diagnostic, with no local result. Here null means not-run or not-specified, and never zero: the dataset, metric, split, threshold, constraints, and hardware must be declared before any point can exist.
The frame is empty because no result exists; a made-up diminishing-returns curve would say nothing about a real dataset. Once results exist, show inner and outer differences together, paired by outer window or by dataset. For a claim across several datasets, aggregate within each dataset before bootstrapping datasets, so a dataset with more folds does not count more.
Judge the outer result against the smallest effect worth having, not just a significance test. A result that is not statistically significant does not prove the options are equivalent. Weerts and colleagues demonstrate an equivalence-style analysis over 59 OpenML datasets. Their study supports this: declare the margin that would change the decision before you see the result.
When to search more
A 16-trial cap is a starting budget. Spend more when:
- the baseline clearly underfits or overfits;
- early stopping keeps hitting the ceiling;
- the first trials show consistent inner improvements above the useful-effect threshold;
- a small change in ranking is unusually valuable.
Unusual class imbalance, sparse or noisy data, hard monotonicity or fairness constraints, and room for an ensemble can also make a deeper search sensible.
Choose what to search from the symptom: hitting the iteration ceiling points to learning rate or capacity. A wide gap between training and validation scores points to leaves, minimum leaf size, sampling, or regularization. Missing a latency target points to leaves, depth, iteration count, and model size. Changing everything at once does not show which change helped.
Better defaults do not end tuning. Probst, Boulesteix, and Bischl’s JMLR study is about XGBoost, not LightGBM. Their defaults, tuned across datasets, captured some of the improvement over package defaults, but measurable gains from tuning remained. Because it is a different model, its numbers cannot be copied into a LightGBM claim. What carries over: better defaults can shrink the value of search without removing it.
Search can also pay when the main metric is flat but a secondary constraint improves. A configuration with similar AUC may be better calibrated, use less memory, or meet a latency limit. That counts as a success if the constraint and its measurement were declared in advance. It is not evidence that another hundred unconstrained accuracy trials will help.
Stopping rule
Before the first trial, write down the primary metric, a split that matches deployment, the smallest useful improvement, secondary constraints, the maximum search budget, and the inner evidence needed to expand it. Then:
- Build the sensible early-stopped baseline, and check that its iteration ceiling and split behave as intended.
- Work out which parameter family is likely to matter, instead of starting with a broad search.
- Run 16 targeted, prefix-stable configurations inside each outer-training part.
- Stop at 16 when inner evidence cannot clear the useful-effect threshold under folds that match deployment.
- Expand to 64 or beyond only inside the inner procedure. Never let an outer result reopen the search.
- Finish every outer fold, aggregate the paired differences, and accept tuning only when the lift survives the declared constraints.
In product units, the final test is:
probability-adjusted lifetime value of lift
>
search compute + engineering + validation + added monitoring cost
Keep going when the paired outer lift clears the declared margin and survives the secondary constraints. Stop when it does not.
Sources
- Moshe Sipper, “High Per Parameter: A Large-Scale Study of Hyperparameter Tuning for Machine Learning Algorithms”, with the arXiv full text.
- Holzmüller et al., “Better by Default: Strong Pre-Tuned MLPs and Boosted Trees on Tabular Data”, and the pinned PyTabKit v1.0.0 repository.
- Erickson et al., “TabArena: A Living Benchmark for Machine Learning on Tabular Data”.
- LightGBM, early-stopping callback and parameter-tuning guide.
- Cawley and Talbot, “On Over-fitting in Model Selection and Subsequent Selection Bias in Performance Evaluation”.
- Varma and Simon, “Bias in Error Estimation When Using Cross-Validation for Model Selection”.
- Wainer and Cawley, “Nested Cross-Validation When Selecting Classifiers Is Overzealous for Most Practical Applications”.
- Probst, Boulesteix, and Bischl, “Tunability: Importance of Hyperparameters of Machine Learning Algorithms”.
- Niculescu-Mizil and Caruana, “Predicting Good Probabilities with Supervised Learning”.
- Weerts et al., “Importance of Tuning Hyperparameters of Machine Learning Algorithms”.
- Ke et al., “LightGBM: A Highly Efficient Gradient Boosting Decision Tree”, NeurIPS 2017.
- LightGBM, features overview, parameters, and the leaf-value code.
- Rashmi and Gilad-Bachrach, “DART: Dropouts meet Multiple Additive Regression Trees”.
- Rob J. Hyndman, “WAPE: Weighted Absolute Percentage Error”.