I tested tabular foundation models (TFMs) against the LightGBM model we use to forecast weekly store sales, in two tests: a small experiment, then a backtest (forecasting from past dates and comparing with what sold) against the model in production. A third test runs a simpler version of the comparison on public data, so anyone can rerun it.
In the backtest, TabICLv2 (Inria’s TFM, the one I tested most) came within one WAPE point (weighted absolute percentage error) of LightGBM on every sales band (products grouped by how much they sell) but the slowest sellers, and never beat it. The only thing I tuned was the choice of context rows, and it mattered: with random rows, TabICLv2’s forecasts ran 9% of sales lower than LightGBM’s on the best sellers (a bias gap, not an accuracy one). On public data it was a draw. It is much slower to serve and harder to explain.
How these models predict, step by step, is in the companion post, How a tabular foundation model predicts, step by step. This one is about using them on a real case.
The models
- TabPFN: PFN for prior-data fitted network, by Prior Labs
- TabICL: ICL for in-context learning, by the SODA team at Inria; TabICLv2 is its second version, the one I tested in the backtest and on public data
- TabFM: FM for foundation model, by Google
- Kumo-Tabular: NVIDIA’s model, below
With LightGBM, fit() is where the work happens. With a TFM, fit() mostly stores your table, and the work happens in predict(), where the stored rows (the context) and the rows you want answered go through the network together. The weights never change. In short (each point is explained in the companion post):
- a transformer that attends between features and between rows; row order does not matter
- TabICL reads each value against its column, compresses each row into one vector, then lets the query rows attend to the labelled rows; TabPFN-3 moved to the same column-then-row design
- pretrained on synthetic datasets (about 130 million for TabPFN v2); TabPFN treats regression as classification over bins (cross-entropy), TabICLv2 predicts quantiles (pinball loss, which penalises a quantile’s misses asymmetrically so that, for example, the 90% quantile ends up above 90% of outcomes)
- the TabICLv2 paper found quantiles beat TabPFN v2’s bins on RMSE (root mean squared error, which punishes large misses) in preliminary tests; on the TALENT benchmark (a public collection of tabular datasets) TabICLv2 beats TabPFN-2.5 on RMSE, while TabPFN-2.5 keeps a slight edge on MAE (mean absolute error), which the authors suggest may come from its bins
- test rows attend only to training rows, never to other test rows
- ensembling by default (
n_estimators, the number of ensemble members); handles NaNs and non-informative features out of the box
How much context they take, for TabPFN:
- v2: 10k rows
- v2.5: 50k rows (in its report; the docs list 100k as of October 2026)
- v2.6: 100k rows
- v3 and v3.5: 1M rows
The TabICLv2 paper runs million-row tables too, with CPU or disk offloading.
Kumo-Tabular is NVIDIA’s model, released on 29 September 2026 in three sizes (28M to 215M parameters) by a team that includes TabICL’s first author; its name comes from Kumo AI, whose purchase by NVIDIA was reported in June 2026. It combines the TabPFN and TabICL designs (how, in the companion post), was pretrained on contexts of up to 60,000 rows, and NVIDIA warns accuracy “may degrade on tables far beyond the training ranges or when the query rows come from a different distribution than the context rows”, which is the normal case when forecasting.
It ships in NVIDIA’s structured-data-models library, next to TabICLv2, TabFM and a relational model (KumoRelational, built on KumoRFM-2).
Licences
- The TabPFN-2.5 model weights can be used for research and internal evaluation, but not for commercial purposes without paying for a commercial licence from Prior Labs. The licence also counts using the results for commercial decision-making, or in production systems, as commercial: a forecast that drives orders is commercial use. The TabPFN-2.6, TabPFN-3 and TabPFN-3.5 weights are non-commercial too, and TabPFN-3.5 has been the default in the
tabpfnpackage since version 9.0 (September 2026). A commercial user must load the v2 weights explicitly (TabPFNRegressor.create_default_for_version(ModelVersion.V2)) or buy a licence. - The older TabPFN v2 weights are under the Prior Labs License: Apache 2.0 plus an attribution requirement (“Built with PriorLabs-TabPFN”). Commercial use is allowed.
- TabICL is under the BSD 3-Clause License, code and weights; its forecasting module, derived from TabPFN-TS, is Apache 2.0.
- TabFM: the code is Apache 2.0, the released weights are non-commercial. They are also big: about 6.6 GB each for classification and regression.
- Kumo-Tabular: the weights are under OpenMDW 1.1, which permits commercial use; the code is Apache 2.0.
In practice, for a commercial forecast, that leaves TabICL, TabPFN v2 and Kumo-Tabular, unless you buy a commercial TabPFN licence.
Leaderboard
The reference is TabArena, a continuously updated benchmark of tabular models.
- When I checked in early July 2026: TabFM > TabPFN v3 > TabICLv2 > TabPFN v2. TabFM (Google) had been introduced 6 days before.
- Since then, Prior Labs released TabPFN-3.5 (September 2026). On the live board on 29 October 2026 it ranks fourth, behind Kumo-Tabular, LimiX-2 (another tabular foundation model, flagged on the board with a leakage warning) and Kumo-Tabular-Medium, and ahead of TabFM; TabICLv2 is further down. Every TFM named in this bullet, with default settings, ranks well above LightGBM, CatBoost and XGBoost even when those are tuned and ensembled. TabArena’s datasets are tables of independent rows scored on random splits, with no time-based forecast among them.
- The strongest TabPFN versions, the Plus and Thinking variants of TabPFN-3 and TabPFN-3.5, are API or enterprise only.
- In the Nature paper, on regression with default settings, TabPFN v2 is worse than AutoGluon, an AutoML system that trains many classic models and stacks them. It gets better if you tune it and add post-hoc ensembling (PHE: keep the best tuned configurations and average them): in the Nature paper, tuned for 300 s with PHE, it beats a 4-hour AutoGluon. The TabPFN-2.5 report says its default model already matches a 4-hour AutoGluon 1.4. On the board on 29 October 2026, AutoGluon ranks below the best single TFMs.
What to expect before testing
Accuracy
From the first TabPFN paper: TabPFN learns smooth decision boundaries. On small classification datasets (up to 1,000 training rows, 100 numeric features and 10 classes), that paper reports TabPFN clearly beating boosted trees and performing on par with state-of-the-art AutoML systems (such as Auto-sklearn 2.0, which searches pipelines with Bayesian optimisation and ensembles the best), up to 230 times faster. TFMs learn a lot from few rows: the Nature paper shows TabPFN matching default CatBoost’s accuracy with half the training samples.
The papers show this with decision boundaries on toy datasets. I recomputed that picture with TabICLv2 instead of TabPFN (TabPFN’s current weights are gated behind a licence click-through and a login); TabICL in these two figures means TabICLv2. Every panel below is a model trained for this post, seed 0:
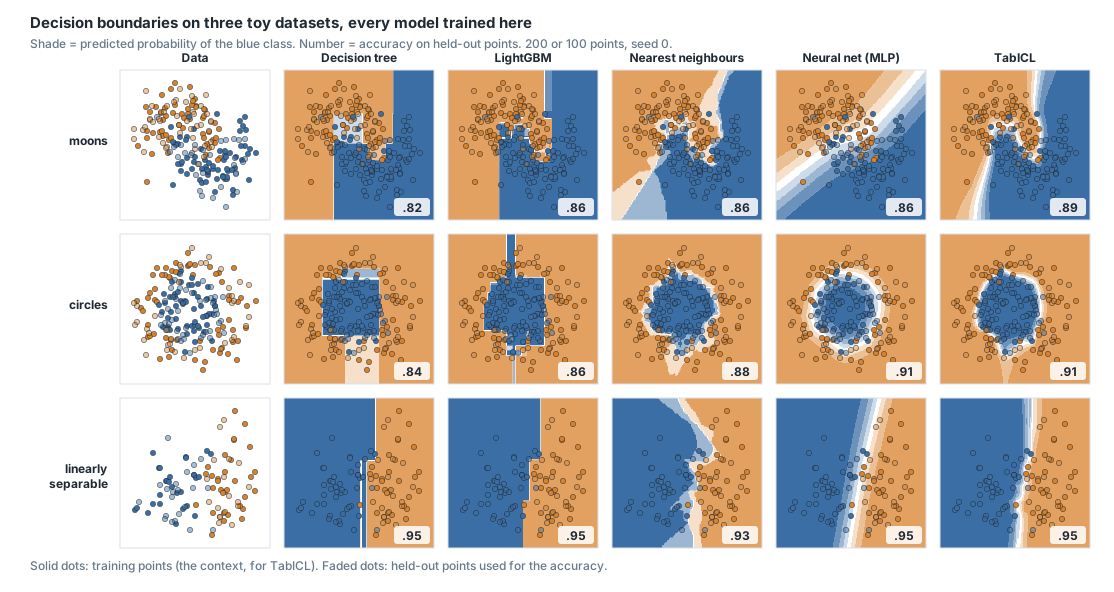
Toy data. The number in each panel is accuracy on held-out points; with 40 to 80 held-out points, a difference of 0.03 is one or two points.
- Trees cut the plane into rectangles: every split is “feature above or below a threshold”, so a decision tree and LightGBM draw a circle as a staircase.
- TabICL draws curves, but not perfectly smooth ones. Its boundary follows each dataset’s shape, like nearest neighbours and the neural net, with a thin uncertain band, but the edge bends around single points and leaves small spurs. It is smoother than a tree, but less smooth than a small neural net.
- Accuracy is close: TabICL is best or tied on all three datasets, 0.07 higher accuracy than the decision tree on moons and circles (5 or 6 more held-out points right), and at most 0.03 above the MLP and nearest neighbours.
The TabPFN papers also show it fitting a very broad class of functions, where traditional methods struggle to fit some of them. I ran that too, on six toy curves:
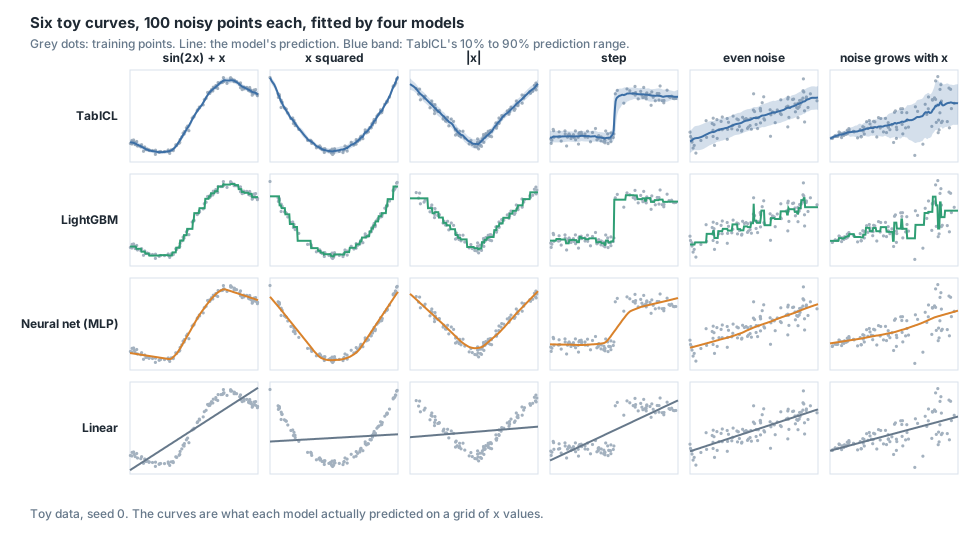
TabICL follows every shape, including the step and the kink of |x|, with no tuning. LightGBM gets there as a staircase that also chases the noise. The neural net rounds off the step. TabICL’s 10% to 90% band widens on the last panel, where the noise grows with x: it returns a distribution, not just a number.
A smooth model suits continuous effects and small tables. Trees cut sharp thresholds, such as a promotion flag, a price break or a stock-out, exactly; TabICL draws them slightly rounded (the step panel in the second figure). Retail has both, so the two kinds of model could make different mistakes. In my backtest their forecasts mostly moved together.
Speed
TFMs are much slower at inference than LightGBM. In a credit-risk benchmark by Mission Lane, a US credit-card company, LightGBM on a 64-vCPU machine was 100 to 1,000 times faster than the TabICL version they tested on T4 and A100 GPUs, and the gap widened for single-record predictions. In my tests LightGBM was at least 100 times faster than TabICL; Test 3 measures the gap on public data. In production you will probably want a GPU: TFMs are much faster there, though even on a GPU they come up short against LightGBM on CPU. On CPU, the tabpfn package refuses runs above 1,000 rows (5,000 for TabPFN-3 and later) unless you set TABPFN_ALLOW_CPU_LARGE_DATASET=1 or ignore_pretraining_limits=True.
Most of the time goes into reading the context, not the rows you ask about. And the more context you have, the slower it gets, faster than linearly: the attention between context rows grows with the square of their number (see How the cost grows).
Between the two TFMs, TabICL was 3 times slower than TabPFN on CPU in my Test 1 notes; the TabICLv2 paper reports the opposite for TabICLv2 against TabPFN-2.5, on all the hardware it tried at 100 features, CPU included.
Features
The feature set we built for LightGBM works unchanged with a TFM, and Test 1 shows that some choices, like the year feature, matter for it too, and so does normalising the target.
Text columns work if you embed them first with an LLM embedding model and pass the embedding columns as numeric features. Without that, TabPFN-3.5, the package default, expands a pandas string column with more than 30 distinct values into up to 30 features (tf-idf over character n-grams, reduced by SVD; its checkpoint turns this on), while an object column is still ordinal-encoded. Older TabPFN checkpoints ordinal-encode free text as a category and warn, and only TabPFN-3-Plus, through the Prior Labs API or an enterprise licence, reads string columns natively. TabICL treats strings as categories too. Text-aware TFMs also exist: ConTextTab and TabSTAR.
Time series
Use a time-series extension (TabPFN-TS, or TabICL’s own TabICLForecaster, which its README calls heavily inspired by TabPFN-TS: pip install "tabicl[forecast]"), or add time-based features (we already do week of year, year, month). TabPFN-3.5 also expands a column with a datetime dtype (not a date string) into calendar features itself.
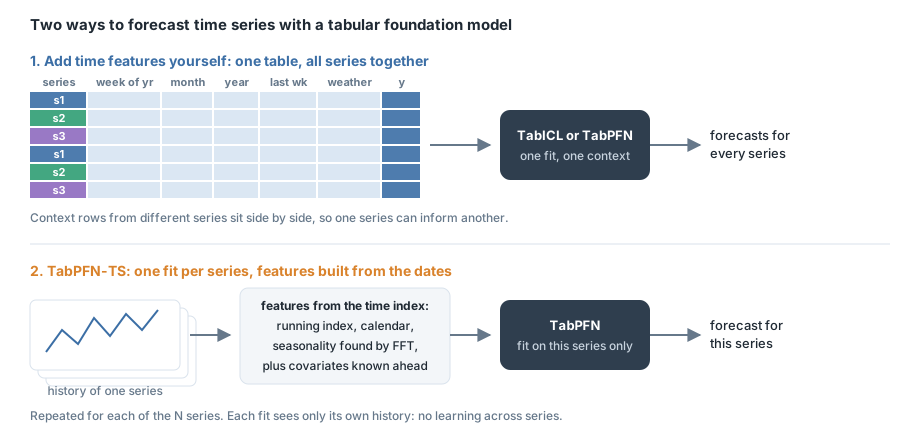
Time-based features. Put every series in one table, with calendar columns and anything else you know, and fit once. This is what we do for LightGBM, and how I ran all three tests below (Test 3 has a single series). With many series, the context mixes their rows, so one series can inform another.
TS extension. TabPFN-TS uses a general TabPFN model underneath (the paper used plain TabPFN v2; the package defaults to TabPFN-3.5 as of October 2026, with an optional checkpoint fine-tuned for time series), and does some signal processing on top. The pipeline:
- For each of the N time series, it builds a table from that series’ own history: a running index, calendar features, seasonal features whose periods are detected with a Fourier transform (FFT), and your covariates.
- It calls
TabPFNRegressor.fit(X_series_i, y_series_i)for each series.
So it is N separate fits of the same network, each seeing only its own (store, product) history: no cross-series learning at all, unlike regular tabular models.
Two more limits from its documentation: it only uses covariates whose future values you supply (past-only and static covariates are dropped), and a multivariate target is split into independent univariate forecasts.
In forecasting terms, TabPFN-TS is a local model (one per series) and LightGBM or TabICL on the full table is a global one. Time-series foundation models such as Chronos-2 are a third kind: pretrained on many series, and able to learn across the series they are given at prediction time (cross-learning). That is for a separate post.
Explainability
Use SHAP. For TabPFN, the separate tabpfn-extensions package has a SHAP integration (pip install "tabpfn-extensions[interpretability]"); TabICL has its own tabicl.shap module (pip install "tabicl[shap]"), which masks a feature by setting it to missing (TabICL then imputes it) instead of drawing it from background rows. For a tree model SHAP is exact and near instant; for a TFM each explanation costs many full predictions; caching the context (kv_cache) cuts that cost.
How I measured
- WAPE: the sum of absolute forecast errors divided by total sales. Lower is better.
- Bias: (sum of forecasts minus sum of sales) divided by total sales: positive means the forecast leans high, negative low.
- Points: a difference between two WAPEs or two biases, in percentage points.
- MAE: the average absolute error, in units sold.
- Cutoff: the date the forecast is made.
- Horizon: how many weeks ahead a predicted week is.
Test 1: a small experiment
Scope:
- five stores
- one product category
- target: the weeks around one high-sales week at the start of the season
- features added for this test: weekly delta (current week minus previous week), plus temperature and precipitation
- models: LightGBM, TabPFN and TabICL (for TabICL, only its speed is reported, under Speed)
TFM out of the box. Without choosing the training samples, it can perform better than LightGBM in some cases and worse in others.
Training samples (the context). More training samples do not necessarily perform better (chosen randomly). This choice may depend on the size of the initial dataset. I ran TabPFN with growing numbers of random context rows on two datasets of different sizes: in run 1 the context grew from 1,000 to 91,000 rows, in run 2 from 1,000 to 9,000.
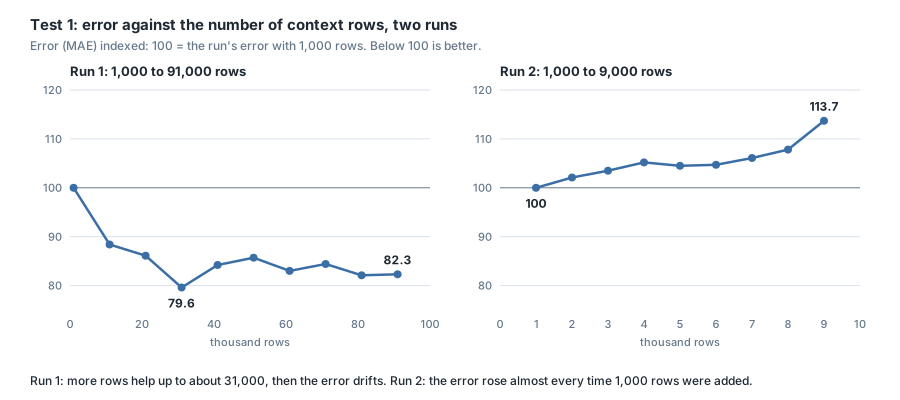
Error (MAE) indexed so 100 is each run’s error with 1,000 rows.
In the first run the error fell up to roughly 31,000 rows, then stopped improving. In the second, almost every step up from 1,000 rows made it a little worse.
TabPFN with a smart context (the same 10-week period last year plus recent weeks, what Test 2 calls a seasonal context) gave about 5% less error than LightGBM on the first forecast week, but it under-forecast more than LightGBM.
Problematic features. The year and week of month features (to a lesser degree) held the forecast down for the high-sales week. Effect of removing year, on the first forecast week, in a separate run from the smart-context one above, so its numbers differ:
Error with year | Error without | Bias with year | Bias without | |
|---|---|---|---|---|
| LightGBM | 100 | 84 | too low | too low, half as much |
| TabPFN | 88 | 100 | too low, a little less than LightGBM | too high |
Error is WAPE indexed so LightGBM with year = 100 (TabPFN without year happens to equal it). Lower is better.
With year, TabPFN had less error than LightGBM. Without it, LightGBM improved a lot, while TabPFN lost accuracy and swung from too low to too high. In this comparison, TabPFN forecast higher than LightGBM both with and without year.
Effect of normalisation. Normalising the target improves TabPFN considerably. Without it, TabPFN missed the jump in sales in the peak week. With it, TabPFN was closer than LightGBM in the peak week, though it overshot the week after. TabPFN already standardises the target as a whole internally, so a plain global rescale changes nothing; the normalisation that helps has to do more than that.
The same holds for the input features: these models already rescale each column themselves, and their ensemble members vary the preprocessing or the feature order, so a global rescale of an input changes nothing either. Only a normalisation the model cannot do itself, such as scaling each product’s sales by that product’s own level, can add something. I have not tested raw inputs; normalising the target is what I tested, and it helped.
Test 2: a backtest against LightGBM in production
The larger test: a backtest of TabICLv2 against the LightGBM model in production. A backtest means standing at a past date, forecasting the following weeks, and comparing with what really sold.
Both models saw the same features, built for LightGBM, in these groups: long-term trend (a baseline sales level); short-term trend (last weeks’ sales, last month’s average); seasonality (month, week of month, week of year, the same weeks last year); product attributes (where the product sits in the catalogue); store and geography; weather; holidays.
Backtest perimeter:
- one product category
- three cutoffs ten weeks apart, from summer to late autumn
- horizons 1 to 8
- compared with LightGBM, the model in production
- weeks with a shortage removed from the metrics, so lost sales do not distort the bias
Context sample choices, the only thing I tuned:
- context length: 10k, 20k, 30k rows
- cutoff specialisation: random rows (a random context), or rows from a similar week of year (the same weeks last year, in a 4- or 8-week window) plus the most recent weeks before the cutoff (a seasonal context)
Results over the first four weeks of each forecast (horizons 1 to 4):
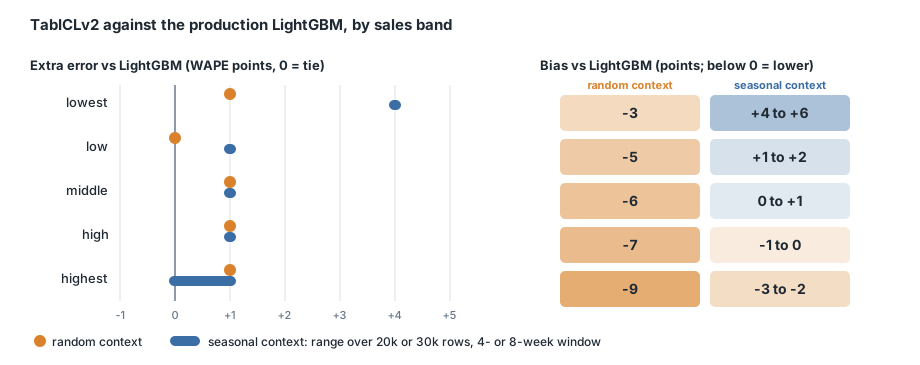
Products are grouped into five bands by average weekly sales; the lowest band sells less than one unit a week on average. Error and bias are shown relative to LightGBM, in points.
- LightGBM and TabICLv2 have almost the same performance. In every band except the lowest, TabICLv2 is within one WAPE point of LightGBM, never better. In the lowest band it is one point worse with a random context and four with a seasonal one.
- Context choice can have a big impact. A random context gives almost the same WAPE but forecasts lower than LightGBM on every band, most on the highest: 9 points of bias lower. A seasonal context cuts that gap to 2 or 3 points on the highest band, but on the lowest it flips to 4 to 6 points above LightGBM. On one product at its seasonal peak (not shown), the random-context forecast fell well below LightGBM’s forecast, while the seasonal contexts and LightGBM stayed close.
- The slowest sellers are over-forecast by every model, by a wide margin. This is intermittent demand: most weeks sell nothing, so even a small over-forecast in units is a large share of the few units sold.
- 20k and 30k rows gave almost the same results.
Two products: the TabICLv2 and LightGBM forecasts compared with each other, indexed so 100 is the product’s average week. Actual sales are not shown, for confidentiality.
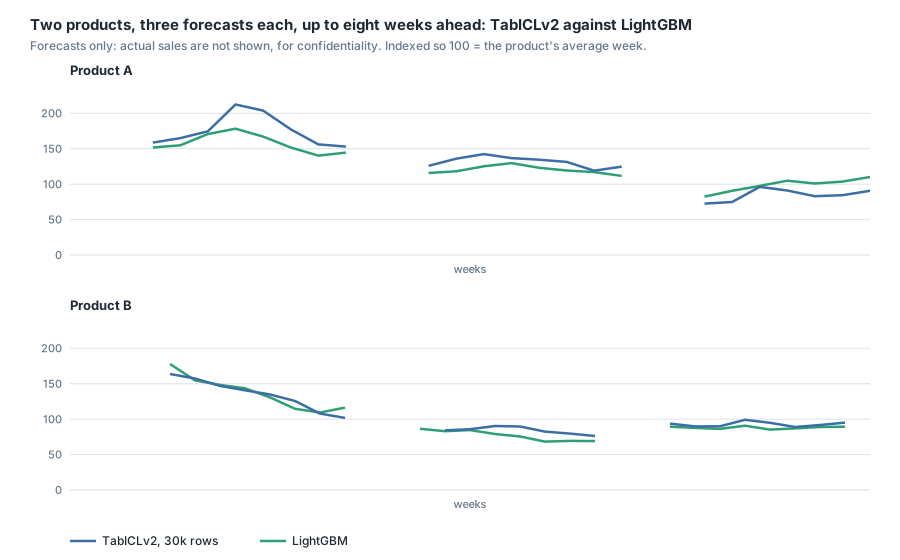
The two forecasts follow the same shape; their levels can differ by up to about a fifth, as on Product A’s first forecast.
Test 3: a simpler comparison on public data
The store data is confidential, so I repeated the comparison on a public demand dataset anyone can rerun: hourly bike rentals in Washington DC (OpenML 42712: 17,379 hours with calendar and weather columns, 2011 and 2012). Each of three months, July, September and November 2012, is forecast from every hour before it. Both models get the same 12 columns, with the observed weather, as if the weather forecast were perfect, and no lagged rentals, and run with their defaults (LGBMRegressor() and TabICLRegressor(), seed 0): no tuning, no context selection. TabICLv2 runs on an 8-thread CPU machine, no GPU, with tabicl 2.2.0 and lightgbm 4.7.0.
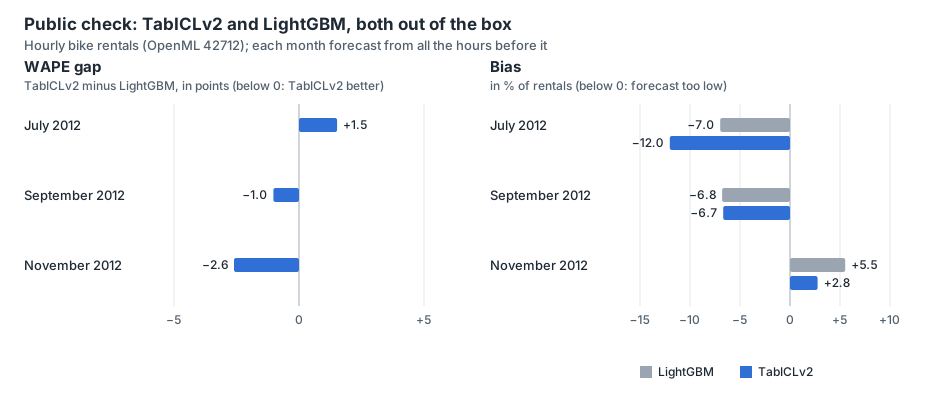
WAPE and bias as defined in How I measured. Each month has about 720 hours to forecast and 13,000 to 16,000 hours of history.
- Accuracy is a draw out of the box. TabICLv2’s WAPE was 1.5 points worse than LightGBM’s in July, and 1.0 and 2.6 points better in September and November: 0.7 points better on average.
- Both models forecast July too low, TabICLv2 more so (12% of rentals against 7%). In September their bias is the same; in November TabICLv2 is less biased (+2.8% against +5.5%).
- Speed is not a draw. LightGBM trained in under a tenth of a second and predicted a month in 2 milliseconds. TabICLv2’s
fit()took under a second, since it only stores and preprocesses the table, but predicting a month took 2.4 to 3.3 minutes. - Predicting one hour took about 95% as long as predicting the whole month. If you predict against the same context more than once, turn on
kv_cache=True:fit()then reads the context once (3.4 minutes for November, about as long as one uncached prediction), and a later one-hour prediction took 0.2 seconds and the whole month 8.6 seconds, with the same WAPE as without the cache, at the cost of memory. For a single batch forecast per cutoff it saves nothing. - More context, more than proportionally slower. November had 22% more history than July and took 37% longer to predict: more than linear, less than the square, because part of the work grows linearly (one run per month, so indicative).
On a GPU these times should shrink (not measured here), but the shape stays: TabICLv2 costs one pass over the context, LightGBM almost nothing.
Conclusion
- TFM offers great value for effort: a first good model needs no hyperparameter tuning, only a choice of context; but each forecast costs far more compute than LightGBM, and in production probably needs a GPU
- TabICLv2 came close to our LightGBM model but never beat it, and the public check found a draw; the leaderboard gap did not show up on a time-based forecast
- the features built for LightGBM worked unchanged with the TFM; I did not test how much they add
- if you need forecast explanations, gradient-boosted trees are still the better choice: explaining them is exact and cheap
- several of the strongest models are not free for commercial use
The Mission Lane team reached the same verdict on credit-risk data: “In summary, while TabICL delivers exceptional performance parity without tedious tuning, it currently comes with a substantial operational latency cost that must be carefully considered for high-speed, low-batch inference environments.”
What next
To test next
- time series extensions (TabPFN-TS,
TabICLForecaster) - Kumo-Tabular: first on TabArena and usable commercially
- TabFM
- feasibility of inference for our use case, using a GPU
Ideas for going further
Choosing the context:
- optimise the sample used for training: make it like the validation dataset, only bigger
- product-specialised context: only rows from the same family
- the tabpfn-extensions large-data mode, which subsamples and ensembles over a big table (still relevant for TabPFN v2; TabPFN-3 takes up to 1M rows natively but is non-commercial)
Combining with LightGBM:
- average the TFM and LightGBM predictions, and see if it gives better results: their errors are not perfectly correlated. In the backtest they often missed in the same direction, so this needs testing. PFN-Boost is one published way to combine them: the boosted trees learn the residual of the transformer’s prediction.
- TFM embeddings as LightGBM features: the tabpfn-extensions embedding module extracts TabPFN’s representation of each row
Adapting the model and its inputs:
- fine-tuning, to adapt to a specific dataset
- try the models on input features without our normalisation
- pretraining on real data: TabDPT, from a Canadian team, pretrains on real tables and reports performance improving as a power law with model and data size
Serving cost:
- output a smaller network or a GAM (generalised additive model) that is good for our dataset, for faster inference. MotherNet (ICLR 2025) does it with a hypernetwork: one forward pass outputs the weights of a small network for the task, with no gradient descent. Prior Labs sells a distillation engine with its Enterprise Edition that turns TabPFN into a compact MLP or tree ensemble. Otherwise, you can train an MLP on the foundation model’s predictions, but in my opinion that would be worse than training on the actual target.
Baselines:
- comparison against an AutoML baseline: Auto-sklearn 2.0 or AutoGluon
Further reading
Related PFN work covers prompt-tuning (TuneTables, NeurIPS 2024, learns a compact context instead of passing the whole table), data generation, density estimation and outlier detection (the Nature paper and the tabpfn-extensions unsupervised module). There are also separate PFN models for data that drifts over time (Drift-resilient TabPFN, NeurIPS 2024, relevant to forecasting), counterfactual fairness (FairPFN) and interpretable GAM output (GAMformer).
Sources
From my notes:
- Mission Lane, TabICL under the microscope: benchmarking tabular foundation models for enterprise credit risk
- Exploring TabPFN: a foundation model built for tabular data, Towards Data Science
- TabPFN: how a pretrained transformer outperforms traditional models on tabular data, Medium
- TabPFN v1 paper
- Kaggle notebook: TabPFN 2.5 demo
- Gaël Varoquaux, TabICL: pretraining the best tabular learner
- TabFM weights (large download)
- tabularfoundationmodels.com, a free online book by Christoph Molnar
- nanotabicl, a small, readable reimplementation of TabICLv2
- Auto-sklearn 2.0 (ASKL2)
- Data Language Models, another kind of tabular foundation model
- TabArena leaderboard
Primary sources for the facts above:
- TabPFN v2: Nature paper and code
- TabPFN-2.5 report and licence; TabPFN v2 weights licence
- TabPFN-3.5 report
- TabPFN-3 report and model card; Prior Labs model list
- TabICL: paper, TabICLv2 paper, code and licence
- TabFM: Google Research blog
- TabArena paper
- TabDPT
- TabPFN-TS: paper and code
- PFN-Boost
- ConTextTab and TabSTAR
- tabpfn-extensions embedding module
- Kumo-Tabular: NVIDIA Kumo page, Fortune on the acquisition, NVIDIA blog post, model card, structured-data-models library, OpenMDW 1.1 licence
- KumoRFM-2