A made-up insurance claim, SYN-CLM-0042, lands in a human review queue with the label INVESTIGATE. The label on its own says almost nothing. The reviewer’s first question is: what exact evidence path produced this route?
They should be able to answer it without replaying a model’s hidden reasoning or trusting a polished summary. That means knowing which files arrived, byte for byte. Which facts came from which place in which file. Which sources share an origin. Which rule fired first. Which fields were never filled in. Without those answers, the recommendation carries more weight than it should.
The claim is a fully synthetic training fixture, not a customer record, and it uses no product traces or deployment observations. Below, I build its evidence record step by step: files, facts, the graph that links them, the rules, and the human decision. The claim stays uncertain at the end. The record lets another person trace and check that history.
What the record should hold
Suppose a claim system returns a fraud score of 0.78. The number suggests a decision but does not say what it is based on. A reviewer can raise the threshold, lower it, or add another model, and still have no lasting record of what the score was based on. If the decision is appealed later, someone has to rebuild a run that no longer exists from logs, prose, and memory.
I would rather start with the record. At minimum, it holds the exact input files with their hashes and timestamps; the extracted facts, each with the place in the file it came from; the search queries and the ranked results they returned; the policy clauses that apply; contradictions; shared dependencies; software versions; the rule, from an ordered list, that set the machine’s state; and every human action that followed. The recommendation is one field among all of these.
A cautious recommendation needs this too. INVESTIGATE could mean a suspected loss, a missing timestamp, two locations that disagree, or a catch-all fallback label. Each of those calls for different work. Reason codes and links to the evidence tell the reviewer which question is still open.
The record also has to survive change. A document may be corrected, a policy excerpt replaced, or a reviewer may resolve a contradiction. If you overwrite the old summary, you lose the basis for the earlier route. An append-only history (entries are added, never edited) lets a second reviewer see what the machine knew at the time and compare it with what was added later.
The check for the rest of this post: another person starts from the frozen inputs, retraces the path to the machine’s state (one of a small fixed set), challenges any link along the way, and records a different human outcome, while the original uncertainty stays on record. Any link they cannot find is a concrete defect in the evidence graph.
Five artifacts, seven facts
The fixture has five artifacts, meaning input files. Each one is exact UTF-8 text ending in a newline. Their IDs are plain labels for tracking where evidence came from. They say nothing about the conclusion.
| Artifact | File | Bytes | Full SHA-256 |
|---|---|---|---|
| A1 | claim-intake.json | 175 | b511d8221b95ddb65148d588df427d2a434813eabc314557ddebe1fcb74f3812 |
| A2 | driver-statement.txt | 164 | 1b73e0ded3b8d43c6731ac368ced0432c898bcaed7185ccdf1a62d2a2abfeae3 |
| A3 | inspection-note.txt | 128 | 583e61cd2e1338c2c5fbbf3bef3c5dae6d55c63a602b704af77afa5244ab9bf5 |
| A4 | repair-estimate.csv | 61 | a096b9d95e47b90184680a870f280073e95a5d53ecfe051885a37a8018d4b54d |
| A5 | policy-excerpt.txt | 161 | 0529516b3970638a94e9225b9a236ea4d2049a99f196485a276e57f55fc6bf7b |
A hash is a fingerprint of a file’s exact bytes. Change one byte and the hash changes. It does not certify that the content is true: a claimant can repeat the same error in three files and get three valid hashes. In this fixture, A1, A2, and A4 all belong to the same claimant_intake_package, so their independence is not established. When A4 agrees with A1, that agreement comes from inside one package.
A3 has a different weakness: its source image timestamp is unavailable. The note reports which area was observed, but the timestamp field is empty. Treating it as timestamped image evidence would fabricate provenance, the record of where evidence came from. A5 is a wholly synthetic policy excerpt and not a real policy or legal rule. Its 30-day notice window exists only so the fixture has a rule to check.
Extraction turns these files into seven facts. Each fact keeps its coordinates, the exact place in the file it came from. The one calculated fact, the gap in days, points back to both dates.
| Fact | Name | Value | Coordinate or derivation |
|---|---|---|---|
| F1 | loss_date | 2026-02-14 | A1 /loss_date |
| F2 | reported_date | 2026-02-18 | A1 /reported_date |
| F3 | notice_gap_days | 4 | deterministic UTC date difference: F2 minus F1 |
| F4 | claimed_damage_area | rear_left_bumper | A1 /claimed_area; A2 L2:C40-55 |
| F5 | observed_damage_area | front_right_fender | A3 L2:C16-33 |
| F6 | estimated_repair_area | rear_left_bumper | A4 row 2 field 2 |
| F7 | notice_window_days | 30 | A5 L2:C16-17 |
F4, the claimed area, comes from the intake JSON and the driver statement, both from the same package. F6, the repair estimate, names the same rear-left area. F5 comes from the inspection note and names the front-right fender. So the output is an explicit conflict between the claimed and observed locations, plus a warning that the agreeing sources’ independence is not established. A majority vote for “rear left” would erase both.
This post has two small standard-library Python examples, which check the fixture and are not production code. The first pins A4’s exact bytes, including the final newline.
from hashlib import sha256

artifact = b"item,area,amount_eur\npaint_and_labor,rear_left_bumper,850.00\n"

assert len(artifact) == 61
assert sha256(artifact).hexdigest() == "a096b9d95e47b90184680a870f280073e95a5d53ecfe051885a37a8018d4b54d"
Change a comma or remove the newline and the assertion fails. Before two people argue about a conclusion, they can check that they worked from the same bytes.
The evidence graph
A transcript tells a story in order. An evidence graph records which claim each file can support, how each fact was worked out, and where two facts disagree. Every link has a type. For this claim there are eleven links:
A1 → F1-extracts.A1 → F2-extracts.A1 → F4-extracts.F1 → F3-derives.F2 → F3-derives.A2 → F4-supports.A3 → F5-observes.A4 → F6-estimates.A5 → F7-governs.F4 ↔ F5-contradicts; bidirectional conflictCG1, unresolved.F6 → F4-consistent_with; independence unverified.
The types keep different kinds of evidence apart. supports marks the claimant’s own statement. observes marks the inspection note. consistent_with records that two facts agree without claiming they are independent. governs applies only within the declared synthetic policy. The two derives links tie F3 to both dates, so a calculation is never passed off as a third source file.
The graph also records what is missing. The missing source-image timestamp remains unavailable; filling it in from the inspection date would invent provenance. That empty field feeds the ordered decision rules in the next section and becomes a reason code for human review.
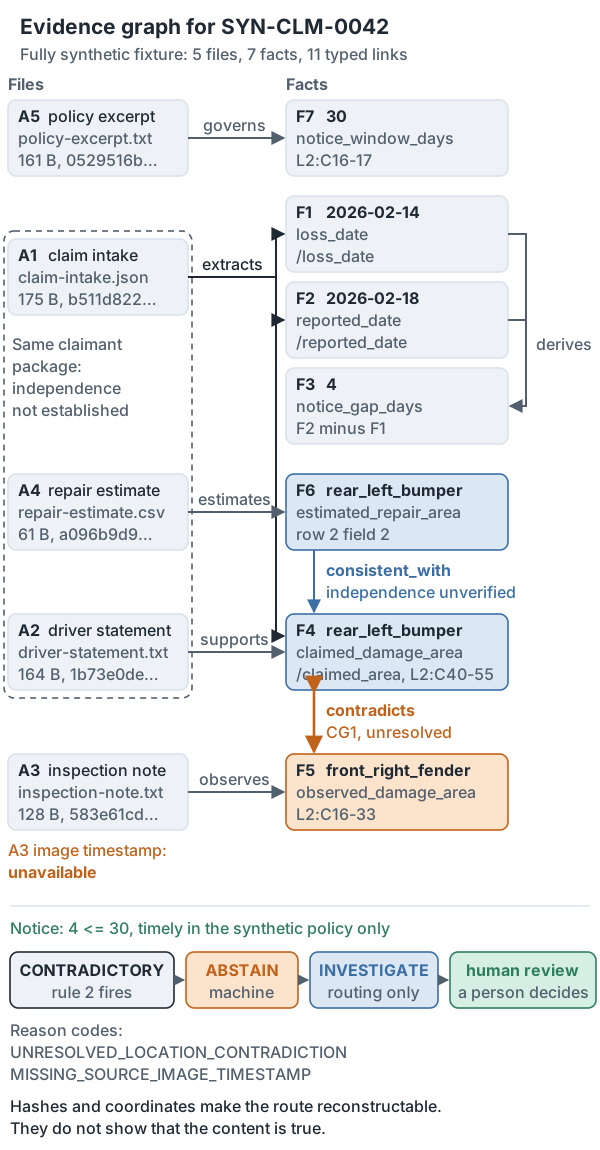
Figure 1. The evidence graph for the fully synthetic claim. The hashes and coordinates make the route reconstructable. F4 and F5 contradict each other, so the machine abstains and INVESTIGATE routes the record to human review.
Ordered rules and abstention
Abstaining means the machine declines to decide. It is sometimes treated as a trick for evaluation scores: move the threshold until the system answers fewer cases. In a product, abstention needs fixed rules about which condition wins, and a useful next step. The fixture applies these rules in this exact order:
OUT_OF_SCOPE- no applicable policy.CONTRADICTORY- unresolved material conflict.INSUFFICIENT- missing required provenance.SUPPORTED- required evidence and no unresolved conflict.
The order decides the outcome. Whether the policy applies is checked first. An unresolved material contradiction wins next, even when the other required fields are present, so a complete-looking bundle with conflicting locations is still contradictory.
The notice check is simple. The claim was reported 4 days after the loss and the synthetic policy allows 30, so 4 <= 30 supports timely notice only inside the wholly synthetic policy fixture. The location check is different: F4 conflicts with F5 in CG1, and that conflict is unresolved. The machine disposition is ABSTAIN, with reason codes UNRESOLVED_LOCATION_CONTRADICTION and MISSING_SOURCE_IMAGE_TIMESTAMP.
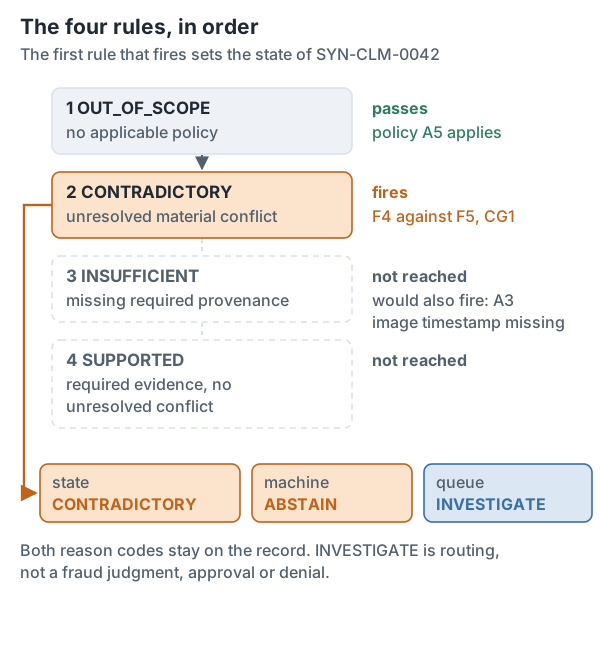
Figure 2. The four rules run in order and the first one that fires sets the state. For this claim, rule 2 fires. If the conflict were resolved, the missing timestamp would still fire rule 3, so it stays on record as a reason code.
INVESTIGATE means workflow routing only; it is not a fraud judgment, approval, denial, confidence score, or adverse action. It sends the evidence bundle to a person with two concrete questions: which damage location should count, and can the original image’s provenance be recovered?
The second example computes the date gap, keeps the rule order, and shows the contradiction winning over the missing provenance.
from datetime import date

loss_date = date.fromisoformat("2026-02-14")
reported_date = date.fromisoformat("2026-02-18")
notice_gap_days = (reported_date - loss_date).days

RULE_ORDER = ("OUT_OF_SCOPE", "CONTRADICTORY", "INSUFFICIENT", "SUPPORTED")

def classify(*, applicable: bool, unresolved_conflict: bool, missing_provenance: bool) -> str:
    if not applicable:
        return RULE_ORDER[0]
    if unresolved_conflict:
        return RULE_ORDER[1]
    if missing_provenance:
        return RULE_ORDER[2]
    return RULE_ORDER[3]

state = classify(applicable=True, unresolved_conflict=True, missing_provenance=True)
machine = "ABSTAIN" if state == "CONTRADICTORY" else state
queue = "INVESTIGATE" if machine == "ABSTAIN" else None

assert notice_gap_days == 4
assert (state, machine, queue) == ("CONTRADICTORY", "ABSTAIN", "INVESTIGATE")
The example is small enough to check by hand. A production rule engine would add policy versions, authorization, and more states, while keeping the rule order visible and keeping a route separate from a verdict.
Recording the human decision
Human review needs the same history as the machine path. A resolution requires a reviewer pseudonym, reason, timestamp, and cited evidence, and each human decision record keeps those with the resolution, override, and appeal together. If the reviewer accepts F5, rejects it, or obtains a timestamped source image, that action gets a new record. The machine output stays as it was.
An override points both ways: back to the machine state, reason codes, and cited files, and forward to the new human state and its justification. An appeal record does the same. A later reviewer can then tell “the machine abstained because the locations conflicted” apart from “a person resolved the conflict after obtaining a new image.”
In the fixture, the human record is still empty: the reviewer fields are null and the appeal has not started. An empty field is a prompt to gather more context, not a score. The same goes for confidence, overrides, and appeal history: a useful record says what is known and what needs attention next.
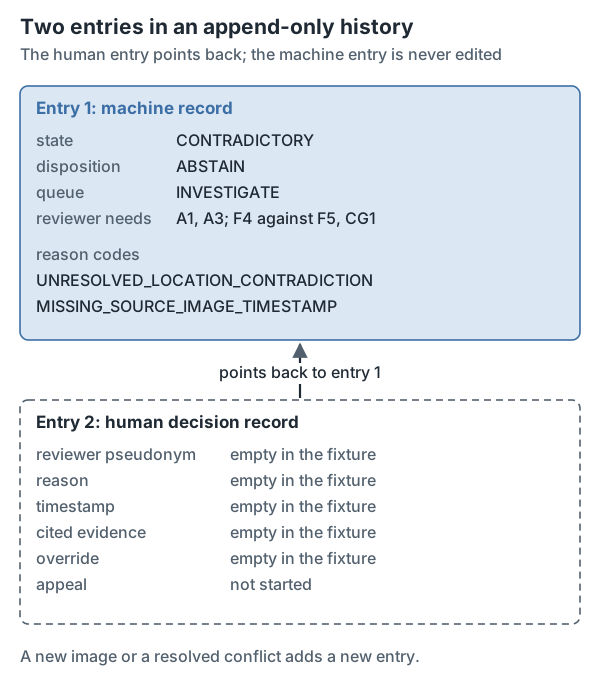
Figure 3. The human decision is a new entry that points back to the machine record. In the fixture its fields are still empty.
For SYN-CLM-0042, the assigned reviewer needs A1 and A3, the F4/F5 conflict, both reason codes, and the coordinate links behind them. Access to the wider claim file adds no evidence for resolving CG1, so the queue record should stay tied to this one review task.
Where FidelityAI fits
FidelityAI grew out of the November 2025 Pioneers AI Hackathon, where our team explored evidence-led insurance workflows. It is a useful lens for the practical question behind this article: how should a system carry its reasons forward when a claim is incomplete or contradictory?
The team presented and explored a five-phase claim-review concept. The public pitch deck, an immutable static page pinned to one commit, shows five workflow phases, ten roles, ingestion and retrieval stages, a voice interview, adversarial analysis, a final-judge stage, human-readable Markdown artifacts, and a named technology stack.
The current site describes multimodal evidence, five workflow stages, per-stage artifacts, recommendations for adjusters, audit exports, and tenant-aware controls. Those details belong to the product story. This article stays with the design questions that carry over to other systems: evidence lineage, contradictions, and decision records.
The visible link between the deck and this article is the deck’s claim of human-readable Markdown artifacts. The design here takes that idea further. Every file gets a hash, every fact gets a coordinate, every dependency is named, contradictions stay open, and the machine is allowed to abstain.
Two kinds of stage in the deck raise their own record questions: retrieval, and several analysis roles working on the same claim. The next two sections treat them as generic patterns, separate from any team code.
Searching for related evidence
Retrieval means searching the claim’s documents and related material. It helps when there is more material than a person can read. A generic retrieval pattern runs two kinds of search. Sparse search matches on words, as keyword search such as BM25 does, so it can find an exact policy phrase or part number. Dense search matches meaning, so it can find a similar description that shares few words. Fusion merges the two candidate lists into one, and a reranker, a slower and more expensive model run only on those candidates, reorders the combined list.
Each candidate is a lead. Proof needs a matching event, an applicable product, the right date, and the right jurisdiction. A reranker score only sets the order for inspection. Whether the evidence is enough is decided later.
So I would keep the query, the sparse and dense candidate IDs, their original ranks, the fusion method, the reranker version, the final ranks, and the exact passages later cited. The review step can then ask separate questions: was the candidate relevant, did it establish the point, did another source contradict it, and did the source apply?
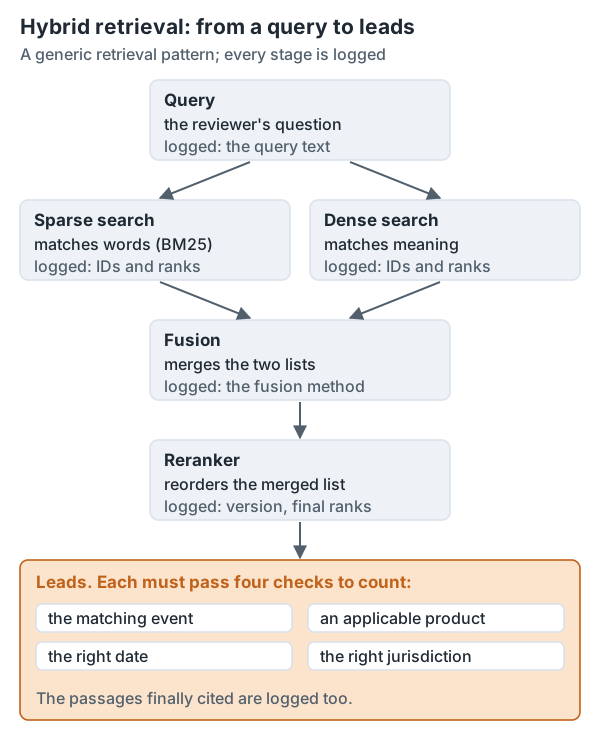
Figure 4. Every stage of the search is logged, and its output is a ranked list of leads. A lead counts as evidence only after the four checks.
This description follows Qdrant’s public hybrid-search material as a generic retrieval pattern. It is a starting point for thinking about how retrieval, evidence bundles, and human review can work together.
Agents that share inputs
Specialized roles can help because they ask different questions. A coverage_hypothesis role may look for missing material, an inconsistency_hypothesis role may challenge facts that do not fit together, and a review_synthesizer may organize the result for a person. The trouble starts when different role names are mistaken for independent evidence.
In this example, all three share extraction_snapshot, context_bundle, base_model, and prompt_family: the same extracted facts, the same context, the same underlying model, and the same family of prompts. That makes agreement correlated: one extraction error, missing document, model blind spot, or prompt assumption could pass through every role.
So the record lists the shared dependencies next to each role’s output. A reviewer can then tell whether two claims came from separate observations or from two prompts over the same context. Counting agents while hiding what they share gives false confidence, because three readings of the same inputs look like three pieces of evidence. No judge role can turn correlated guesses into ground truth by voting.
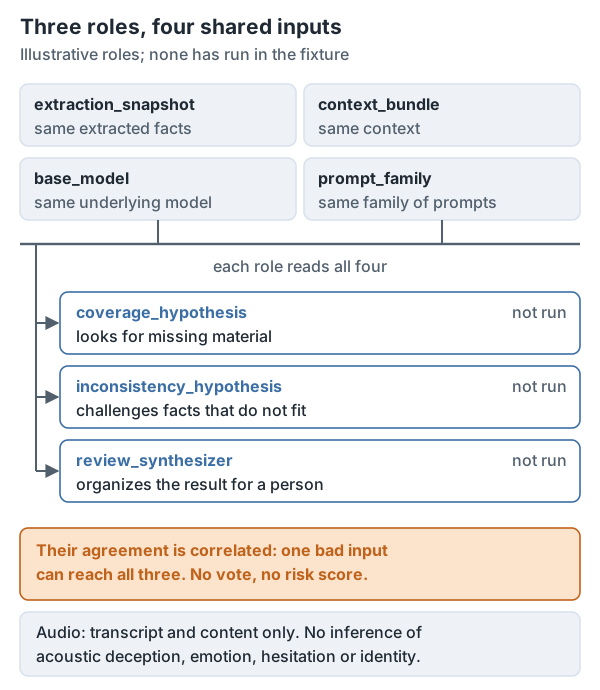
Figure 5. All three review roles read the same four inputs, so an error in any one of them can reach every role. There is no vote or risk score, and audio is limited to transcript and content evidence.
What these roles usefully produce is a list of hypotheses to check: a missing timestamp, a possible contradiction, a citation worth inspecting. Agreement between agents may help decide what to look at first. It leaves the strength of the source unchanged.
Audio gets the same treatment. In this design, audio supplies transcript and content evidence only: what was said. Acoustic deception, emotion, hesitation, and identity inference stay outside the evidence model. A statement can be cited by its timestamp or its place in the transcript. How someone sounds is never used as a hidden fraud signal.
How to test the design
A good evaluation starts with a controlled set of claims, clear denominators (what each rate is counted out of), and agreement on what every score is meant to capture.
Build a blinded set of frozen claims. Mix in complete evidence, missing provenance, planted contradictions, irrelevant search results, and adversarially similar cases. Keep each original rating plus a separate adjudication record with the final call, then evaluate in five stages.
Stage 1 - Reconstructability. Ask a second reviewer to recover every cited passage and every rule decision, in order, from the frozen files. Report citation precision and unsupported-claim rate, each with its denominator.
Stage 2 - Decision behavior. After defining the target and denominator, report the calibration curve, expected calibration error, and Brier score, which check whether predicted probabilities match what actually happened. Declare the confusion threshold (the cut-off score) and publish the true positive, false positive, true negative, and false negative counts.
Stage 3 - Cost and subgroup analysis. Attach a false-positive cost and a false-negative cost to that threshold. For every fairness result, state the subgroup identity, denominator, and fairness metric.
Stage 4 - Robustness. Test missing evidence, contradictory evidence, and adversarial evidence as separate slices. One merged robustness average would hide which kind of evidence failure breaks the route.
Stage 5 - Operations and review. Report latency p50 and latency p95 (median and 95th-percentile response time), reviewer agreement, override rate, and the appeal result when there are appeals. Each value keeps its denominator and status.
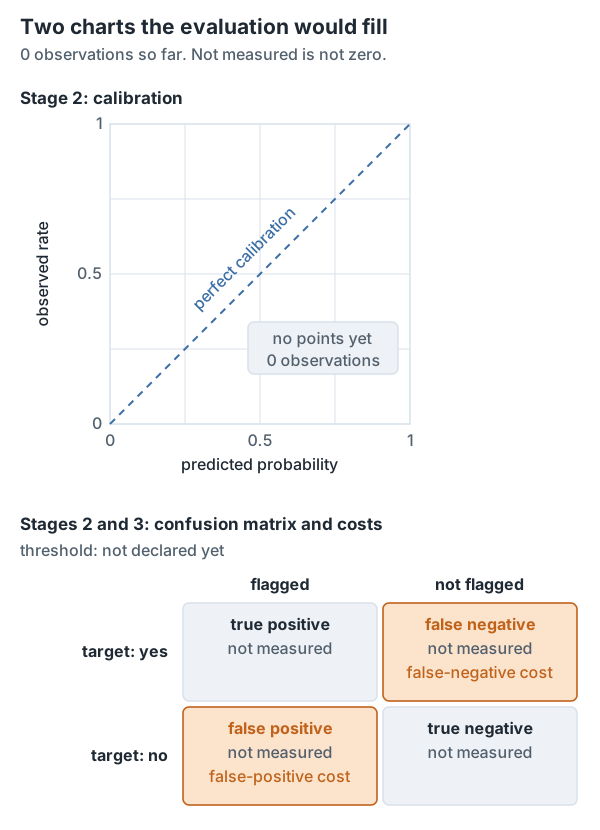
Figure 6. The two charts stage 2 and stage 3 would fill. Nothing has been measured yet, so every cell reads not measured, and any future number needs its denominator beside it.
The design would be falsified by any of these: citations that cannot be rebuilt from the frozen files, contradictions that disappear when the evidence is summarized, unsupported cases that skip abstention, or reviewers who cannot tell why a case reached their queue. It could also fail in practice if the evidence record takes longer to inspect than the claim itself, or if reason codes do not help reviewers choose what to do next.
What to build first
These controls are easier to build if you record where evidence came from before you coordinate multiple roles. I would use this order:
- Freeze each input’s exact bytes, media type, hash, acquisition time, and dependency group.
- Extract typed facts with source coordinates and preserve absent provenance as absent.
- Record derivations, support links, contradictions, and independence assumptions as typed edges.
- Retrieve candidates with logged queries, fusion inputs, ranks, and reranker versions.
- Apply the ordered evidence rules before any recommendation or route is exposed.
- Store model, prompt, tool, calibration, and shared-dependency versions beside every run.
- Make abstention actionable with reason codes and a routing-only human queue.
- Record reviewer identity, reason, timestamp, cited evidence, override, and appeal lineage.
- Evaluate citations, costs, calibration, fairness, robustness, latency, review, and appeals with declared denominators.
Each step is useful before the whole system exists. Exact bytes and coordinates already make incidents easier to review. Typed contradictions already stop a written summary from smoothing over facts that do not fit. A fixed abstention route already gives a person a clearer task. Coordinating multiple roles comes after these controls, because extra roles pass any earlier provenance error to every role.
To check the result, give a second reviewer SYN-CLM-0042 without the original chat transcript, and ask for the exact inputs, the fact links, the conflict, the rule, and the human task. For SYN-CLM-0042, that trail is short: A1 → F4 carries the claimed rear-left area, A3 → F5 carries the observed front-right area, and CG1 keeps their conflict on record. The ordered rules therefore yield ABSTAIN. A later reviewer can resolve that route with cited evidence or leave the contradiction open. Either way, the outcome is stored with the path that produced it.
Sources
- The public pitch-deck commit records five phases, ten roles, human-readable Markdown artifacts, and a named technology list.
- The separate team presentation repository records the hackathon’s team context.
- The current public site describes how the product is positioned today.
- EIOPA’s supervisory discussion gives European context on assisted AI under human oversight, explainability, hallucination, data protection, and vendor risk.
- The NAIC model bulletin announcement describes regulator expectations around governance, accuracy, fairness, documentation, and legal compliance. The NAIC calls the bulletin a guiding document, not a model law or regulation.
- NIST AI RMF 1.0 is a voluntary general framework for risk management, testing, documentation, and transparency, not an insurance regulation.
- Qdrant’s hybrid-search and reranking tutorial explains dense search, BM25 keyword search, fusion, and reranking. It supports the generic retrieval description above; any specific product’s architecture remains outside its scope.
Together, the EIOPA, NAIC, and NIST documents supply governance context; product validation remains outside their scope.