A completion certificate can be a good search result and poor compliance evidence. It names a learner, a course and a passing result, so it is clearly about training. But that result does not prove that the learner’s needs were analysed before training. The certificate does not say who assessed the needs, when, or what was done about them.
This gap between “about the right topic” and “proves the requirement” is the main engineering problem in this post. It comes down to two questions:
- Retrieval relevance: is this passage about the right topic?
- Evidence sufficiency: does it prove the requirement, for this organization, at the right time, from a source another reviewer can check?
A search system answers the first. A compliance check needs the second. This post designs a pre-audit around the second question. A pre-audit is a check run before the official certification audit. The design has six steps, in this order:
- Decide which requirements apply.
- Check relevance and sufficiency separately.
- Keep a trail back to every source.
- Extract facts without filling gaps, and surface contradictions.
- Allow a verdict only when its evidence conditions are met.
- When there is no verdict, say which record is missing.
The goal: each claim cites its source, and each gap names the record that would close it.
The problem: a relevant document that is not proof
Suppose a reviewer asks: “Show that needs were analysed before the training plan was finalized.”
A semantic retriever is a search that matches on meaning rather than exact words. It sees learner, training and result in the completion certificate and ranks it highly. That ranking is fair: the certificate is about training. But it records a later event. It never says who assessed the need, when that happened, or what followed. The error happens when a later step treats “on the right topic” as proof of an earlier process.
This usually happens at the hand-off: “retrieve a few chunks, then ask a model for yes or no.” The retrieved passages are only candidates. Each one still needs a qualification record:
- which part of the requirement it supports;
- which part is missing;
- whether another source contradicts it;
- who reviewed that judgment.
A similarity score is useful for finding candidates. The compliance status has to come from the qualification record.
The wording of the answer matters too. “No” sounds like a negative finding about the organization. Compare: “I found a related certificate, but it does not show that anyone analysed the needs, who did it, or that it happened before training.” That is a narrower claim. It tells the reviewer what the system saw, why it stopped, and what evidence would settle the question.
Background: Qualiopi and the limits of a pre-audit
Qualiopi certification checks training providers against France’s national quality reference framework. The French decree establishing that framework organizes it around seven quality criteria. The 2019 framework splits those criteria into 32 numbered indicators. Décret n° 2026-728 keeps the seven criteria and has 33 indicators from 1 November 2026; this post and Figure 1 follow the 32-indicator version and its v9 reading guide. In engineering shorthand, not official quotations, the seven criteria cover:
- public information about the service, access, and results;
- identification of objectives and adaptation to beneficiaries;
- adaptation of welcome, pedagogical support, monitoring, and evaluation;
- adequacy of pedagogical, technical, and supervisory resources;
- staff competence and continuing development;
- engagement with the provider’s professional environment; and
- collection and handling of feedback and complaints.
Checking a criterion takes more than one document search. Whether a requirement applies can depend on the provider, the action category, the audience, and whether the provider is a new entrant. A requirement may call for a document, an observed practice, an interview answer, or a judgment across several sources.
The Ministry’s Qualiopi reading guide v9 describes an audit context that can include interviews, documentary verification, observation, sampling, and special treatment for new entrants. A pre-audit that reads uploaded documents cannot do all of that. A document-based pre-audit is most useful when it organizes the file, exposes gaps, and prepares sharper questions. Some claims still need evidence from outside the uploaded PDFs.
Where AuditMalin fits
AuditMalin is built around this pre-audit problem: turning scattered evidence into indicator-level, cited guidance. The public experience centers on grounded review and clear next steps.
The AuditMalin homepage presents an AI-assisted Qualiopi pre-audit workflow: collect uploaded documents, crawl the organization’s public website for evidence, analyze at indicator level, provide cited guidance, and prioritize remediation. The public application surface asks for organization profile inputs, action categories, applicable criteria, new-entrant status, a website to crawl, document uploads, an analysis tier, a custom reference document upload, and additional instructions. That workflow links evidence, gaps and next questions.
The homepage’s sample audit conversation (as of 29 October 2026) shows the certificate case from the top of this post. A user attaches attestation.pdf, and the reply begins: “Cette attestation prouve un résultat, pas l’analyse du besoin.” In English: this certificate proves a result, not the needs analysis.
The rest of this post is a proposed reference design. It is not a description of AuditMalin’s internals. The lineage, contradiction model and state machine below show the kind of record that makes the hand-off easier to inspect.
Step 1: decide which requirements apply
Searching the whole framework before fixing the scope creates false gaps. Suppose a requirement does not apply to the organization’s action category. If the system reports “no evidence found”, the absence looks like non-conformity. The correct status may be “not applicable”. The search was asking the wrong question.
The reading guide shows how much scope can change. Six indicators open with a condition in their own wording. Others, such as indicator 15 on informing apprentices, also concern only some action categories; the guide says which. Indicator 3, for example, starts “Lorsque le prestataire met en œuvre des prestations conduisant à une certification professionnelle”: when the provider delivers services leading to a professional certification. For new entrants, the guide adapts the audit of 11 of the 32 indicators. The initial audit checks that the process is written down, and the later surveillance audit checks that it is carried out.
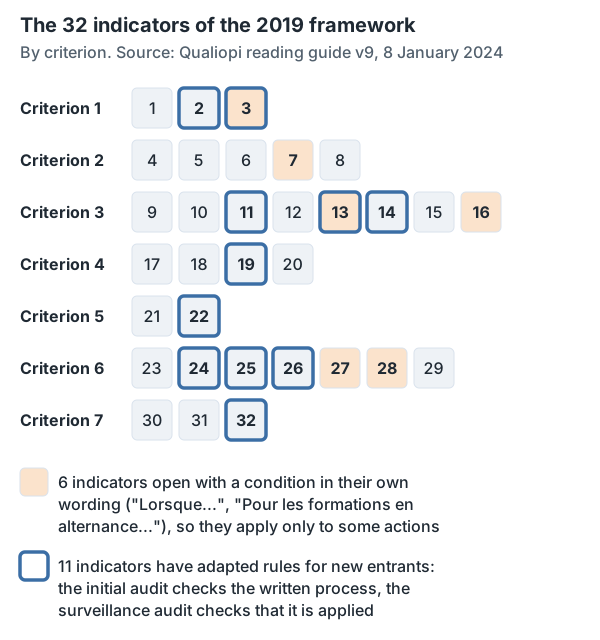
Figure 1. The 32 indicators of the 2019 framework, grouped by criterion. Indicators shaded orange start with a condition in their own wording. Outlined indicators have adapted rules for new entrants. Source: Qualiopi reading guide v9.
So the applicability record should be explicit and reviewable. At minimum it holds:
- the organization profile;
- the action category;
- the applicable criteria;
- the new-entrant status;
- the rule or reviewer decision that set the scope;
- an uncertainty state.
The order matters: settle or review applicability before searching for evidence. If the available context cannot settle the scope, mark it unknown and send it to human review. Do not turn uncertainty into a negative verdict.
Scope also fixes a denominator used later. Evidence coverage divides the requirements that have reviewed evidence by all applicable requirements, not by every requirement in the catalogue. A change of scope creates a new applicability decision, so an old score keeps its meaning.
The same rule applies to documents. A website crawl, an uploaded procedure, a certificate and a custom reference document come from different places. The pre-audit keeps those origins while applying one scoped set of requirements. A source added for context must not become evidence for a requirement that was never declared applicable.
Step 2: check relevance and sufficiency separately
To make the split testable, take a synthetic fixture called ILL-NEEDS-01, a small made-up test case. It asks whether a document supports an illustrative requirement: evidence of needs analysis before training. Evidence sufficiency checks three required elements: actor, timing before training, and needs-analysis action.
There are three test documents:
- Document A names a training coordinator, an interview, recorded needs, and a plan adapted before delivery. A is relevant and sufficient for the synthetic requirement.
- Document B is a completion certificate. B is relevant but insufficient: it proves a later result, not earlier analysis. B is the hard negative: a negative example that looks like a positive one.
- Document C is about a room and its facilities. C is unrelated and insufficient. It is the easy rejection, and takes less of a reviewer’s attention than the related certificate.
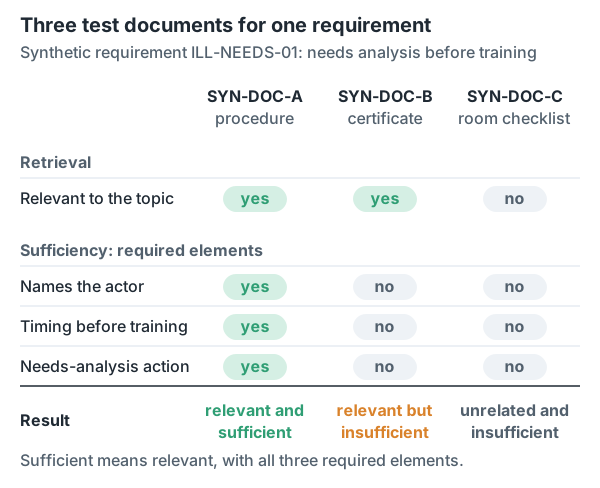
Figure 2. A synthetic example. Retrieval can nominate a candidate, but a document on the right topic still needs evidence for each element of the requirement.
The two judgments are separate but not independent: a document cannot be sufficient without being relevant. Keeping them as two fields is still worth it. A retrieval failure and a qualification failure need different debugging, different evaluation and different fixes.
Step 3: keep a trail back to the page
A citation is useful only if another person can recover the exact evidence that was judged. That trail is the evidence’s lineage, or provenance: where it came from. For each candidate, I would keep:
- a source identifier;
- a stable page or section identifier;
- the exact excerpt;
- its UTF-8 byte count (the length of the text as stored);
- a SHA-256 content hash (a fingerprint that changes if any character changes);
- a chunk identifier;
- a derived fact identifier.
Later records then link the fact to the requirement, the evidence decision, the verdict and the remediation.
It shows that the reviewed excerpt has not changed. A hash does not show that the passage is true or sufficient; that remains a reviewed judgment.
This short snippet, using only the standard library, computes the stored record for the certificate.
from hashlib import sha256

excerpt = "Certificate of completion: the learner completed the Data Analysis workshop and received a passing result."
encoded = excerpt.encode("utf-8")
record = {
    "source_id": "SYN-DOC-B",
    "page_id": "SYN-DOC-B#page-001",
    "excerpt_bytes": len(encoded),
    "excerpt_sha256": sha256(encoded).hexdigest(),
}

assert record["excerpt_bytes"] == 106
assert record["excerpt_sha256"] == "a37380948cc1dcebc1e7f552795394ab207e2b48646d2c8cf36a6cd2e2b2c5c5"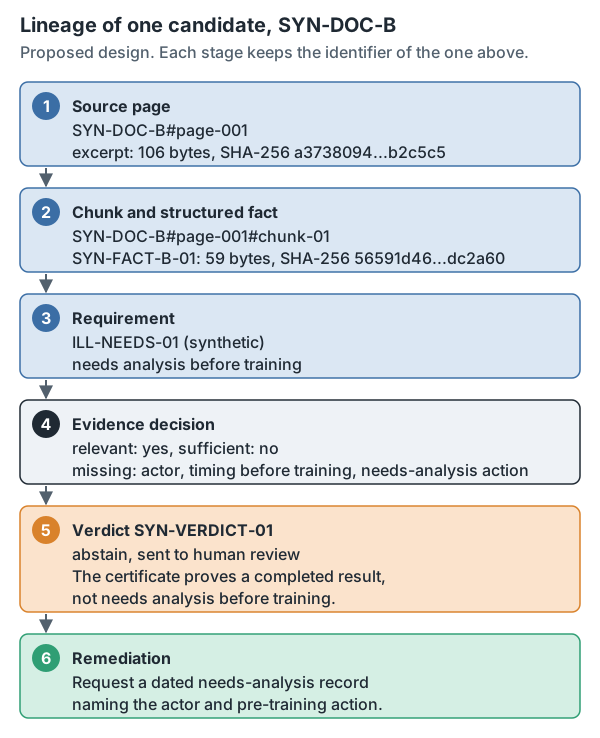
Figure 3. A reference design that ties SYN-DOC-B to its provenance and to a bounded decision. Each stage keeps the identifier of the stage before it.
This lineage survives re-indexing. A position in a vector store is an implementation detail; source + page + hash is the handle a reviewer can rely on. If extraction changes, the system can show that a new fact came from a new version of the excerpt, instead of overwriting what an earlier verdict was based on.
The three test records
These are the full records for the three documents. The hash covers only the text inside the curly quotation marks. The quotation marks, Markdown emphasis and list punctuation are presentation, and are left out.
SYN-DOC-A
- Page identifier:
SYN-DOC-A#page-002 - Exact excerpt: “Before each training session, the training coordinator interviews the learner, records the identified needs, and adapts the learning plan before delivery.”
- Excerpt encoding: exact UTF-8, 154 bytes
- Excerpt SHA-256:
60ed0957ce5d647adb020cfaaa6adae694677c787c0f1a1bcdeed2f916a0cff8 - Structured fact: “A training coordinator records learner needs and adapts the plan before delivery.”
- Fact encoding: exact UTF-8, 81 bytes
- Fact SHA-256:
919a9a2c7e952cfd5aedc3ee9616d81fd70464fe8d3e822a22119bcc4ab9da55 - Qualification: relevant and sufficient
The excerpt covers all three required elements, so within this synthetic exercise it counts as eligible evidence.
SYN-DOC-B
- Page identifier:
SYN-DOC-B#page-001 - Exact excerpt: “Certificate of completion: the learner completed the Data Analysis workshop and received a passing result.”
- Excerpt encoding: exact UTF-8, 106 bytes
- Excerpt SHA-256:
a37380948cc1dcebc1e7f552795394ab207e2b48646d2c8cf36a6cd2e2b2c5c5 - Structured fact: “A learner completed training and received a passing result.”
- Fact encoding: exact UTF-8, 59 bytes
- Fact SHA-256:
56591d463030fb093fda7e6620131dc93895054a22c0d61d3e75924812dc2a60 - Qualification: relevant but insufficient
Its words make it a plausible search result, but its event and its timing fail the support test.
SYN-DOC-C
- Page identifier:
SYN-DOC-C#page-004 - Exact excerpt: “Room checklist: projector tested, seating arranged, and emergency exits kept clear.”
- Excerpt encoding: exact UTF-8, 83 bytes
- Excerpt SHA-256:
b1ca93e2c20198c4b5a6eeb26d1052440fff9c6d1c32c54a2c0afa3abd371f0e - Structured fact: “A room and its facilities were checked.”
- Fact encoding: exact UTF-8, 39 bytes
- Fact SHA-256:
8beecd2ae11d7b247aaf04e04cdb86956324a14b66f2fd99836ff6b9976b8774 - Qualification: unrelated and insufficient
Step 4: extract facts and keep contradictions
Chunks are the pieces a document is split into for search. They are units for retrieval, not ideal units for reasoning. So each structured fact keeps its actor, event or action, object, time and source span, when those fields exist. Missing fields stay missing. The certificate fact says a learner completed training and received a passing result. Extraction cannot invent a coordinator or a pre-training date.
Once facts have fields, contradictions can be inspected. A procedure may say the coordinator records needs before every session, while a dated case file shows the assessment happened afterward. Both passages are relevant. The contradiction cannot be averaged away into “probably conforming”, or settled by keeping whichever source scores higher. Keep the pair, name the field that conflicts, and ask a reviewer to resolve it.
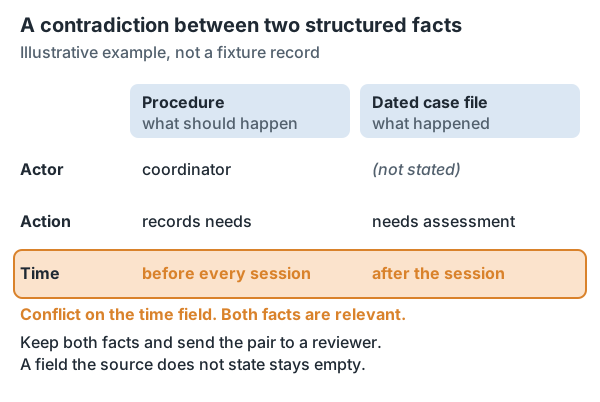
Figure 4. The contradiction example as two structured facts. The conflicting field is named, the empty field stays empty, and both facts are kept for the reviewer. This is an illustration, not a fixture record.
The schema also separates two kinds of gap:
- One candidate that fails to name an actor triggers abstention, meaning the system declines to give a verdict. It does not trigger
incomplete. - After a reviewer has examined the declared evidence set, “no reviewed source names the actor” may support
incomplete.
A reviewed contradiction such as “source X says before delivery; source Y says after delivery” may support non-conforming. These findings call for different questions and different fixes.
Step 5: allow a verdict only when the evidence supports it
A verdict is a state change with conditions. Start at unverified. Record the evidence scope and its review status before choosing a branch:
- A single candidate with insufficient or uncertain support - including SYN-DOC-B on its own - routes to
abstain; it does not establishincomplete. - The
incompletestate is available only after a reviewer has examined the declared scoped evidence set and confirmed a requirement-level gap. - Sufficient reviewed support can support
conforming. - A reviewed contradiction can support
non-conformingafter review.
For SYN-DOC-B, the declared support is insufficient, so the path is SYN-DOC-B → abstain → human review, with its citation and missing elements kept. That path says exactly what was judged: one retrieved candidate. The outcome for the whole evidence set stays open until that set has actually been examined.
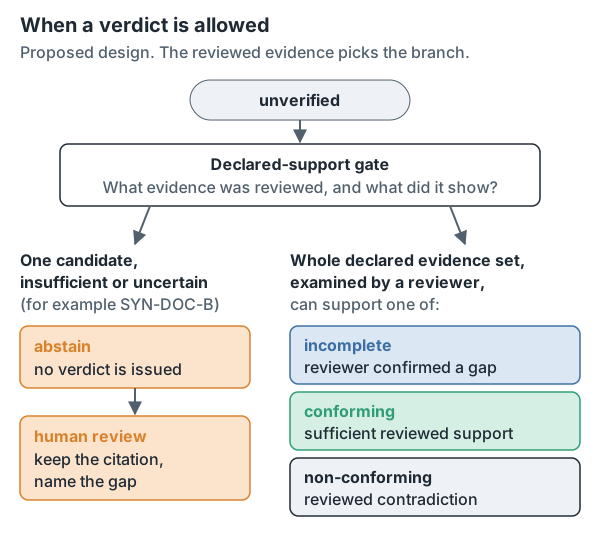
Figure 5. A single candidate with insufficient or uncertain support stays on the abstain path. Verdicts about the whole evidence set need reviewed evidence.
Here is a second example, again using only the fixture. It keeps retrieval relevance separate from the sufficiency gate.
from dataclasses import dataclass

REQUIRED = frozenset({"actor", "timing before training", "needs-analysis action"})

@dataclass(frozen=True)
class Candidate:
    relevant: bool
    support: frozenset[str]

def gate(candidate: Candidate) -> str:
    if not candidate.relevant:
        return "unrelated"
    if not REQUIRED <= candidate.support:
        return "abstain"
    return "eligible-for-human-reviewed-verdict"

assert gate(Candidate(True, frozenset())) == "abstain"
assert gate(Candidate(False, frozenset())) == "unrelated"
assert gate(Candidate(True, REQUIRED)) == "eligible-for-human-reviewed-verdict"
The gate controls when the system may present a judgment based on the documents, and what provenance must come with it. The reviewer still decides whether to accept the procedure, reject the certificate, or ask for another sample.
Step 6: when the system abstains, ask for the missing record
For SYN-DOC-B, preserve SYN-DOC-B#page-001, record the missing actor, pre-training timing, and needs-analysis action, then request a dated needs-analysis record naming the actor and pre-training action. The claim, the candidate inspected, the missing evidence and the next action travel together.
The stored remediation text is short on purpose: Request a dated needs-analysis record naming the actor and pre-training action.
Compare that with “more documents”. The precise request tells the organization which record would close the gap, and why. If no such record exists, the same instruction becomes a process fix: decide who performs the analysis, capture it before delivery, and keep the dated result.
So the output record holds the applicability, status, claim, source and page, excerpt or structured fact, the reason the evidence is or is not sufficient, missing elements, remediation, and review state. A user can then move from incomplete to ready for review without mistaking a suggested next action for an audit finding.
Remediation also closes the provenance loop. A new record gets its own source identifier and hash, and the requirement is re-evaluated against the new evidence set. The earlier abstention stays explainable instead of vanishing from history.
How to test the design
This section is a test plan; no results are reported here.
A useful evaluation begins with a blinded fixture, clear denominators, and a record of every reviewer decision. Blinded means the reviewers label the cases without seeing the system’s answers. The fixture should cover:
- applicable and non-applicable requirements;
- sufficient evidence;
- related hard negatives and unrelated negatives;
- missing documents;
- seeded contradictions, planted on purpose.
Freeze the source bytes and the expected lineage before evaluating. Qualified reviewers label applicability, citation support, sufficiency, contradictions and verdict state independently. Adjudication, the step that settles their disagreements, is recorded separately and does not replace the original ratings.
Report each measure with its denominator:
| Measure | Formula |
|---|---|
| Citation precision | qualified supported citations / all returned citations |
| Unsupported-verdict rate | non-abstained verdicts without sufficient reviewed support / all non-abstained verdicts |
| Evidence coverage | applicable requirements with reviewed evidence / all applicable requirements |
| Selective risk | errors among non-abstained cases / all non-abstained cases |
| Selective coverage | cases receiving a verdict / all evaluated cases |
| Contradiction precision | correctly flagged reviewed contradiction pairs / all flagged contradiction pairs |
| Contradiction recall | correctly flagged seeded contradiction pairs / all seeded contradiction pairs |
| Krippendorff’s alpha | 1 - observed disagreement / expected disagreement |
Plot selective risk against selective coverage as the abstention threshold changes. A system that issues fewer verdicts may cut its error rate by declining the hard cases. If you report only risk, a system that declines the hard cases looks best. If you report only coverage, a system that answers everything looks best. The curve shows the trade-off, and no single threshold suits every deployment.
For contradictions, declare the number of seeded contradictions before testing. Precision without recall can look strong if the system flags one obvious pair and misses the rest.
Krippendorff’s alpha measures agreement between reviewers, and reaches 1 when they never disagree. Publish the reviewer count, item count, missing ratings and adjudication count with it, and say when expected disagreement makes the statistic undefined.
The design is falsifiable: these results would show it is wrong. It fails if:
- relevant hard negatives repeatedly cross the sufficiency gate;
- returned citations do not support their claims;
- contradictory facts are flattened into a confident verdict;
- reviewers cannot rebuild the lineage from the public record; or
- in operation, abstentions leave out an evidence request that could resolve them.
Any of these should change the gate or the evidence model. It should not be hidden inside one overall assistant score.
Build order
Start with the audit trail, not the text generator:
- Define an applicability record and require a reviewed scope or explicit unknown state.
- Give every source and page a stable identifier; hash the exact bytes used for review.
- Extract structured facts without filling absent actors, actions, or dates.
- Retrieve candidates per applicable requirement and keep relevance separate from sufficiency.
- Store support, missing elements, and contradiction links as inspectable fields.
- Gate public statuses on declared evidence; route uncertainty to abstention and human review.
- Produce a precise remediation request tied to the missing elements.
- Evaluate citations, unsupported verdicts, coverage, selective risk, contradictions, and reviewer agreement with declared denominators.
Generation comes after those controls. Its job is to explain a bounded record in useful language, not to invent the record. With this order, a wrong answer can be traced to the stage, or stages, that produced it: scope, retrieval, extraction, qualification, contradiction handling, state gating, or explanation.
The completion certificate still shows that training happened and a result was recorded. It cannot carry the earlier needs-analysis claim on its own. The design fails if a related completion certificate can cross the support gate without evidence of the actor, pre-training timing, and needs-analysis action.
Sources
- French decree establishing the national quality reference framework, for the seven-criteria framework.
- Décret n° 2026-728 du 1er août 2026, for the 33-indicator framework in force from 1 November 2026.
- Ministry Qualiopi reading guide v9, for the official reading, the limits of the audit context, the indicator wording and the new-entrant rules in Figure 1.
- AuditMalin public site, for the product’s observable pre-audit positioning, workflow and sample audit conversation.
- AuditMalin application surface, for the visible applicability, website-crawl, and instruction inputs described above.