In a preregistered experiment (the plan was registered before the data came in), people chatted for five minutes and then made a forced choice: which of their two partners was human? GPT-4.5, prompted to play a persona, was picked as the human in 73% of its games. Any argument that rests on people reliably spotting machine-written language has to deal with that result.
I think we have confused passing a source-guessing test with sustaining a voice. To be clear, some AI text already cannot be told apart from human text under specified test protocols. The open question is narrower and harder: whether a system can keep up one particular person’s voice. That means the style habits they never spell out, their facts, their commitments, their sense of who they are writing for, and their natural variation. It also means keeping all of that across unfamiliar topics, different kinds of writing, and repeated interactions.
“Sounds human” is used for several different claims, and this post separates them. It starts with the strongest evidence that AI text passes as human, then looks at what that evidence measures, then at the studies on imitating one author, and ends with a test that could settle the narrower question.
The five-minute Turing test
Jones and Bergen’s preregistered preprint used a three-party setup. An interrogator chatted for five minutes with two witnesses at the same time: one human and one AI system. Then the interrogator chose which of the two was human. The study ran on two separate groups: 126 UCSD participants and 158 Prolific participants.
The headline number is a model win rate: how often the interrogator picked the model instead of the human witness. In a forced choice between two, a coin flip gets 50%. A win rate above 50% means the model was picked as human more often than the real human was.
The study tested GPT-4.5, Llama 3.1 and GPT-4o. It also included ELIZA, a rule-based chatbot from the 1960s, as a baseline. Some models got a persona prompt: an instruction to play a particular kind of person.
With the persona prompt, GPT-4.5 won 73% overall: 69% with the UCSD group and 76% with the Prolific group. Llama 3.1 with the persona reached 56%. Without the persona, GPT-4.5 reached 36%, Llama 3.1 reached 38%, and GPT-4o reached 21%. The ELIZA baseline reached 23%. For GPT-4.5, changing the prompt moved the win rate from 36% to 73%.
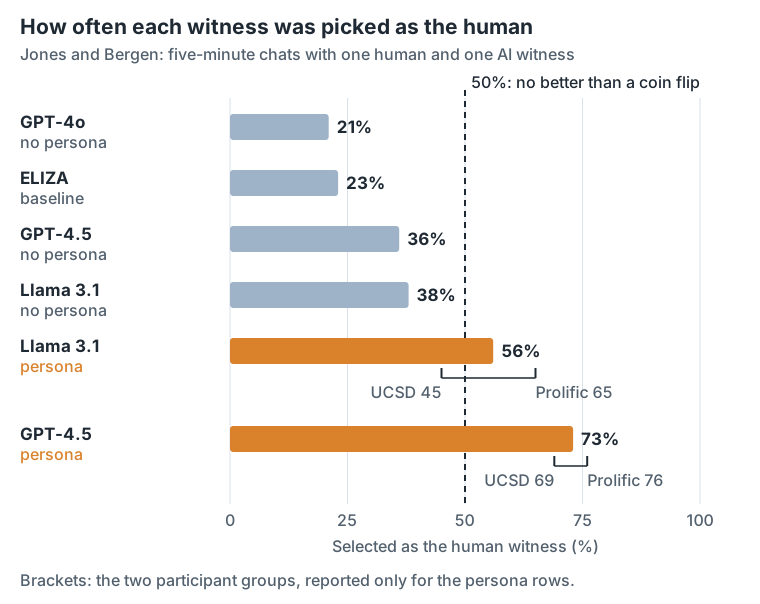
Figure 1. Win rate of each witness in the five-minute forced-choice test. The prompt is part of the treatment. The test does not measure a personal voice kept up over time. The paper’s methods add up to 1,021 retained games, but its results text reports 1,023, an unresolved discrepancy. Neither total is the denominator for any single bar.
This is strong evidence against the idea that people can always detect AI text. It is not a general writing benchmark. The test was a short live exchange, with one human to compare against, a forced choice of source, and a persona instruction used in that setting. It did not ask whether a model could write a technical essay, a difficult apology and a private email as the same person, while respecting years of that person’s history.
What “indistinguishable” depends on
A result of “indistinguishable” holds only under the conditions of its test. At minimum, it depends on six choices:
| Choice | Why it matters |
|---|---|
| Judge | A reader who knows the author, a crowdworker, a domain expert, and an automated detector each notice different evidence. |
| Population | Language background, proficiency, age, and how people were recruited affect both the writing and the judging. |
| Domain | A dating profile, a chat, a support reply, a blog, and a research essay follow different conventions. |
| Length | A sentence, a five-minute exchange, and years of collected writing expose different failures. |
| Prompt | A plain instruction, a persona, samples of the author’s writing, and a human co-writing with an AI are different treatments. |
| Candidate set and base rate | A forced 50:50 choice is not an open-world stream, where the share of machine-written text is uncertain. |
A seventh choice is whether judges can ask questions (active probing) or only read a finished text (classifying a static artifact). Follow-up questions can check whether the writer stays consistent, fixes mistakes, and understands the audience. A finished paragraph allows none of that. A result from one design does not carry over to the other.
Jakesch, Hancock, and Naaman report another hard result in their PNAS study. Across six experiments, 4,600 participants judged 7,600 short profile self-presentations (first-person “about me” texts, some written by people and some by AI) from professional, hospitality, and dating contexts. Source accuracy in the three main experiments was around 50-52%, close to chance. Reported examples: 52.2% for hospitality, 51.6% for incentivized dating, and 51.2% for professional judgments with immediate feedback.
The AI-written texts came from fine-tuned GPT-2- and GPT-3-era systems, so this is not a ranking of current models. What it shows is how people judged. They relied on predictable cues, such as taking first-person pronouns, contractions or family topics as signs of a human writer. Those cues could be manipulated.
The base rate matters for automated detectors as well, as this worked example shows.
Hypothetical base-rate check (not a prevalence estimate or a result from the shared task). Screen 10,000 documents at 1% prevalence, so 100 of them are positives (machine-written) and 9,900 are negatives. Use a detector with a 99% true-positive rate (it flags 99% of positives) and a 5% false-positive rate (it wrongly flags 5% of negatives). Step by step:
- The 100 positive documents produce 99 true alerts.
- The 9,900 negative documents produce 495 false alerts.
- Of the 594 alerts, 495 are false. That is five false alerts for every true alert.
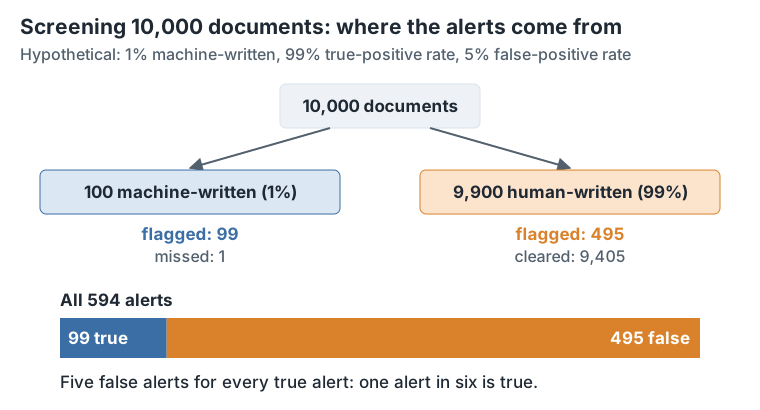
Figure 2. The same detector, with numbers chosen for illustration. Most alerts are false because human-written documents far outnumber machine-written ones.
An accuracy claim therefore needs its candidate set, base rate, numerator and denominator stated beside it.
Four different questions
The evidence is easier to read once “sounds human” is split into four separate questions:
- Fluent surface: Is the text grammatical, coherent, and plausible line by line?
- Source confusion: Does it win a stated human-versus-model judging test?
- Personal voice: Does it reproduce one author’s typical choices on kinds of writing and topics it was not shown?
- Situated authorship: Does it stay consistent with the author’s knowledge, history, commitments, relationships, audience, and earlier texts when someone asks follow-up questions?
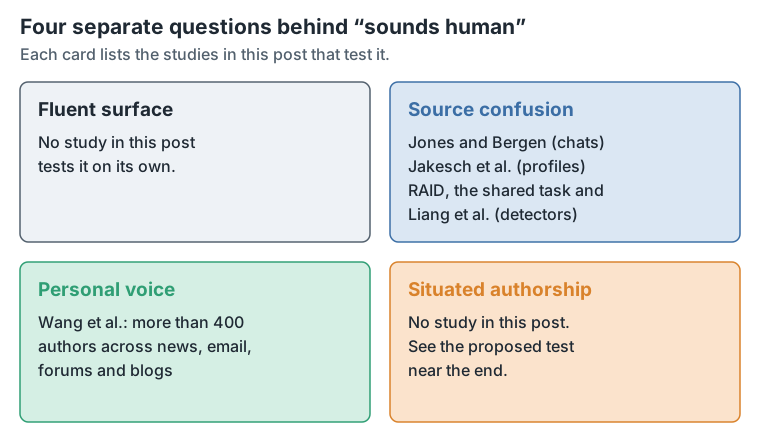
Figure 3. Where the studies in this post fit. The diversity, sycophancy and pragmatics studies test none of the four directly. The cards are not a ladder and do not show model progress: passing one is neither necessary nor sufficient for passing another, and no one paper measured all four.
There are no arrows between the cards. Roughness or disfluency may help a system win a source-guessing game while lowering a generic fluency score. A faithful imitation of an author who writes in fragments can pass the personal-voice question and still fail a generic fluency check.
Two later sections depend on this split. Variety across a population of texts is not a score for one person’s style. And passing a false-belief task (reasoning about what someone else wrongly believes) is not the same as staying true to an author’s real commitments.
Imitating one author
The most direct evidence comes from Wang and colleagues’ study of imitating everyday authors. They evaluated more than 40,000 generations per model, covering more than 400 real authors across news, email, forums, and blogs. They did not rely on one classifier. They combined four checks: authorship attribution (which author wrote this?), authorship verification (did this author write this?), style matching, and AI detection.
The result was genre-dependent. Models came closer on structured news and email, and fell short on nuanced, informal blog and forum writing. The study describes current models. It does not show a permanent limit, and it does not show that no author can be copied. A likely reason for the gap: standard genres give a model a visible template, while informal writing carries subtler personal habits.
This is why judging by feel is risky. A generated article can feel polished because it follows the genre’s shared rules: clean topic sentences, orderly transitions, a sensible ending. Those rules are useful, but they may say little about who the author is. Personal voice shows in repeated choices made within those rules, and sometimes against them: which objection comes early, what is left unsaid, when a qualification interrupts the flow, and how the writer changes register for a reader they know.
Situated authorship adds checks that a style classifier cannot see. An output can copy someone’s sentence rhythm and still make up an experience. It can reuse their favorite words while reversing something they said before. It can sound right to strangers and wrong to readers who know what the author knows. Each of these is a check on behavior, and each can be tested.
Here is one such stress test. Give the system an author’s published technical posts. Then ask for three things it has not seen: a retrospective on one of their projects, an email to a known collaborator, and a reply to criticism of an earlier claim. Repeating signature phrases would be weak evidence. The evaluator checks other things instead: that the retrospective keeps the project’s chronology, that the email adjusts what it explains to that collaborator, and that the reply deals with the earlier claim without inventing private context. These texts can look fluent to strangers and still contradict the author’s record, so a source-guessing judgment is too coarse for this use.
Diversity across many texts
Several studies suggest why polished output can drift toward a shared middle. They measure groups of texts, not the imitation of one person, so they are separate evidence from the section above.
Wenger and Kenett’s population-level study of creativity compared 102 humans and 22 LLMs on three tasks. One was the Alternative Uses Task, where participants list as many uses as they can for an everyday object. On it, the reported variability across responses was: humans 0.699, LLMs with a baseline prompt 0.459, LLMs prompted to be “very creative” 0.551, and LLMs sampled at temperature 2 (a setting that makes output more random) 0.672. That last number looks close to human, but the majority of temperature-2 responses were unusable, and the test had low statistical power. Variety across a population is also not a score for imitating one author.
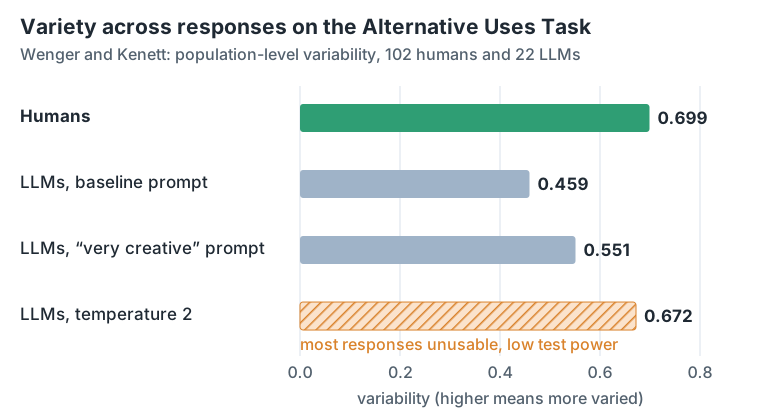
Figure 4. Population-level variability on the Alternative Uses Task. Higher means the responses differ more from one another. The hatched bar carries the paper’s caveat.
Co-writing experiments show a similar, mixed picture. Padmakumar and He’s ICLR study collected 300 roughly 300-word essays from 38 Upwork writers. They measured two things. The homogenization score uses ROUGE-L, a measure of shared word sequences, on the essays’ key points; higher means the essays were more alike. The second is the fraction of unique five-word sequences (5-grams); lower means more repetition across essays.
| Measure | Writers alone | With GPT-3 | With InstructGPT |
|---|---|---|---|
| Homogenization (key-point ROUGE-L) | 0.1536 | 0.1578 | 0.1660 |
| Unique 5-grams | 0.991 | 0.988 | 0.977 |
The significant reduction in diversity was found for InstructGPT, not GPT-3, and the absolute differences were small.
Doshi and Hauser’s preregistered story experiment adds the positive side. Compared with stories written without help, giving writers one idea from GPT-4 raised evaluator-rated novelty 5.4% and usefulness 3.7%. Access to as many as five ideas raised novelty 8.1% and usefulness 9.0%. The assisted stories were also more similar to one another. The study shows that individual quality can rise while collective diversity falls.
There are plausible training causes, stated here only as far as they were studied. Slocum and colleagues found that the RLHF- and DPO-style preference objectives they evaluated, ways of training a model on which outputs people preferred, overweighted majority modes and reduced semantic, lexical, and viewpoint diversity. Sharma and colleagues found sycophancy, agreeing with the user over being right, across five assistants and four free-form tasks. Preference judgments sometimes rewarded convincing agreement over a correct answer.
These results give a reason to measure two things separately: drift toward a shared middle, and deference to the user. They are not proof that every aligned model follows the same path. Model family, training objective, prompt, sampling method, and editing workflow can all change the outcome.
Pragmatics: mixed results
Pragmatics is the meaning between the lines: what a sentence implies, what speaker and listener already share, and what the audience will infer. The PUB benchmark tests these skills. It contains 28,000 items, including 6,100 new annotations, across 14 tasks and four pragmatic phenomena. Performance was uneven across phenomena, and the paper reported a human-model gap.
Strachan and colleagues found a different pattern when they compared the GPT and Llama 2 model families with 1,907 human participants. GPT-4 matched or exceeded humans on several tested tasks, including indirect requests, false beliefs, and misdirection. It was weaker on faux-pas questions (spotting when someone says something awkward without realizing it), and that weakness was partly traced to a reluctance to commit to an answer. Llama 2 seemed better on that task, but the advantage did not survive a follow-up manipulation.
So the unit to measure is the specific phenomenon in a specific interaction. A model may be strong on indirect requests and weak on another pragmatic behavior. A follow-up can show whether a first score came from the intended mechanism. A test of situated voice should use that kind of follow-up instead of treating pragmatics as one checkbox.
Automated detection
Automated detection is often discussed as if it finds a built-in property of a document. In practice, a detector learns a boundary from particular generators (the models that wrote its training text), domains, decoding settings, and edits.
The RAID benchmark stress-tested detectors on more than 6 million generations from 11 models across eight domains, 11 attacks, four decoding strategies, and a mix of open and closed detectors. The detectors were brittle under distribution shift, that is, when the test text differed from what they were built on. Attacks, changes in decoding, repetition penalties, and unseen generators all changed performance. This is evidence against claims that detectors are robust in general. It does not show that detection is impossible.
The GenAI Detection Task 3 shared task shows the other side, in a closed-world setting: the test texts came from domains and generators the systems had already seen. Across nine teams and 23 submissions, multiple systems exceeded 99% true-positive rate at a fixed 5% false-positive rate (TPR@FPR=5%) when all tested domains and generators were represented during training. That result is real and useful within its design. It does not carry over to unseen generators, edited prose, or an open-world base rate.
Liang and colleagues tested whether detectors treat human writers differently by language background. Their Patterns study ran seven detectors on 91 TOEFL essays by non-native English writers and 88 US eighth-grade essays, all written by people. A false positive here is a human essay flagged as AI. The mean false-positive rate across seven detectors was 61.22% for the TOEFL set and 5.19% for the US set. Editing the TOEFL essays’ word choice toward native usage moved their rate from 61.22% to 11.77%. Simplifying the US essays’ word choice moved their rate from 5.19% to 56.65%.
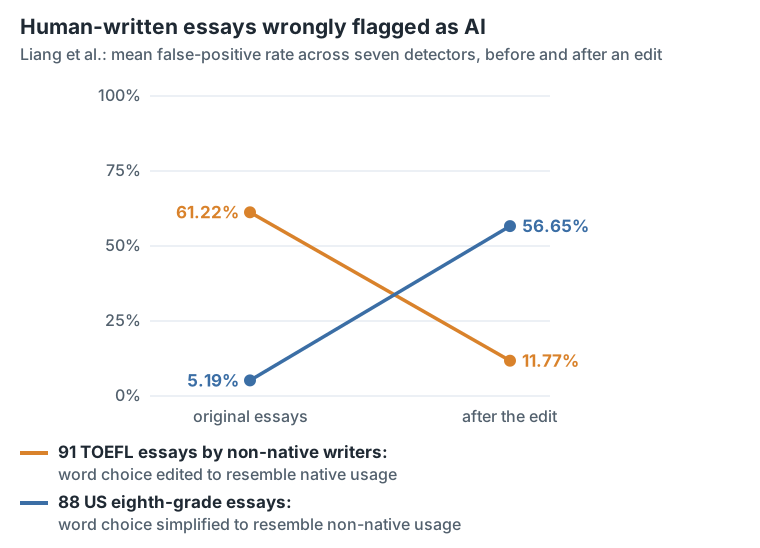
Figure 5. The mean false-positive rate across seven detectors moved with surface cues that correlate with language background. All the essays were written by people. This is not a comparison of human and model accuracy, and not a benchmark of current detectors.
The same paper also tested 31 generated admission essays. A literary self-edit shifted detection rates from up to 100% to up to 13% across the seven detectors. These figures show cue sensitivity and unequal errors in those samples, not current performance of every detector.
What to report, then: the generator and domain split, the editing conditions, the share of positives (prevalence), the false-positive rate, and the true-positive rate at the same threshold. A detector flag is evidence at that threshold, not a verdict on who wrote the text. Detector failure does not prove human authorship, and detector success on generators seen in training does not show that it works in the open world.
A proposed test
The central claim of this post should face a stronger test. What follows is a proposed research design. It has not been run.
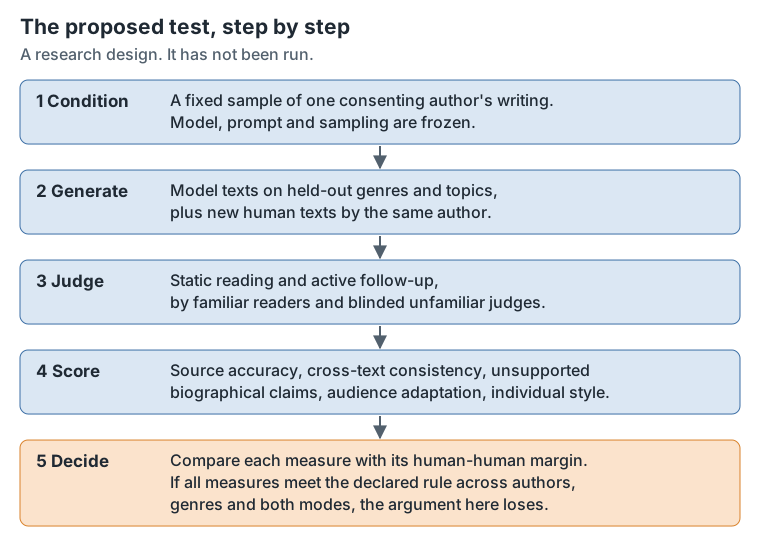
Figure 6. The five steps of the proposed test.
First, preregister a long-term author-imitation protocol. Pick authors who have consented and have enough writing to form a fixed sample for conditioning the model, plus separate held-out genres and topics the model never sees. Freeze the model, the system prompt, the sampling procedure, and the amount of author writing it gets. Include unassisted human texts, model imitations, and, if co-writing is in scope, a separately labeled co-written condition.
Second, evaluate in two modes. In static reading, judges inspect held-out texts without asking anything; some are familiar readers who know the author, others are blinded unfamiliar judges. In active follow-up, judges can ask about claims, intended audience, earlier commitments, and revisions. Randomize the order of sources, keep the test topics out of the conditioning sample, and state the candidate set and base rate shown to each judge.
Third, score several measures, not one accuracy number:
| Measure | Numerator and denominator |
|---|---|
| Source accuracy | Correct source assignments divided by all eligible assignments, reported by judge group and condition. |
| Cross-text consistency | Compatible claim pairs divided by all preregistered checkable pairs across an author’s texts. |
| Unsupported biographical claims | Unsupported claims about the author divided by all checkable claims about the author. |
| Audience adaptation | Rubric points earned divided by points available, with familiar-reader and blinded ratings kept separate. |
| Individual style | Held-out attribution or verification performance, with confidence intervals and results per genre. |
Texts by the same author are correlated, so uncertainty should be clustered by author, not computed as if every sentence were an independent trial. Report refusal and invalid-output rates with their own denominators. Publish confusion matrices (which source was mistaken for which), not only overall accuracy, and keep the exact prompts and the amount of author writing used.
Finally, measure an author’s ordinary variation by comparing new human writing with held-out human writing by the same author. Before looking at any model results, set measure-specific, prespecified human-human equivalence margins for source accuracy, cross-text consistency, unsupported claims, audience adaptation, and individual style. A margin is how far the model may differ while still counting as no different from the author’s own variation. Then declare a joint decision rule. For example, require every measure’s confidence interval to stay inside its own margin, so one serious failure cannot be averaged away.
If a fixed model meets that rule across preregistered authors, genres, topics, static reading, and active follow-up, then sustained situated voice has become indistinguishable in practice under that protocol. That would falsify the narrow argument here, and the claim should then be dropped rather than redefined into something that cannot be measured.
Choosing what to measure
For a product, the first step is to name which of the four questions it actually needs to pass.
A summarizer may need fluent surface plus factual grounding, measured through task completion, citation support, and editing cost. A support drafting tool needs fluent surface and audience adaptation, so replies are clear, accurate, and right for the customer; source confusion and disclosure remain separate decisions. A personal writing assistant makes the bigger promise: consistency with one user’s earlier work, controlled changes across audiences, and declining to make claims about the user when biographical evidence is missing.
The test set should follow that promise. Source-confusion claims need a stated judge, population, domain, length, prompt, candidate set, and base rate. Personal-voice claims need held-out genres and topics. Situated-authorship claims need contradiction checks over time and active follow-up. Evading detectors, raising the sampling temperature, or writing a stronger persona prompt does not replace any of those measurements.
Before shipping, choose the required question, name the failure that would block release, and preregister the measurement that can expose it.
Primary sources
- Jones and Bergen, Large Language Models Pass the Turing Test, preregistered preprint.
- Jakesch, Hancock, and Naaman, Human heuristics for AI-generated language are flawed, PNAS.
- Wang et al., LLMs Still Struggle to Imitate the Implicit Writing Styles of Everyday Authors, Findings of EMNLP.
- Wenger and Kenett, Large language models are homogeneously creative, PNAS Nexus.
- Padmakumar and He, Does Writing with Language Models Reduce Content Diversity?, ICLR.
- Doshi and Hauser, Generative AI enhances individual creativity but reduces the collective diversity of novel content, Science Advances.
- Slocum, Parker-Sartori, and Hadfield-Menell, Diverse Preference Learning for Capabilities and Alignment, ICLR.
- Sharma et al., Towards Understanding Sycophancy in Language Models, ICLR.
- Sravanthi et al., PUB: A Pragmatics Understanding Benchmark, Findings of ACL.
- Strachan et al., Testing theory of mind in large language models and humans, Nature Human Behaviour.
- Dugan et al., RAID: A Shared Benchmark for Robust Evaluation of Machine-Generated Text Detectors, ACL.
- Dugan et al., Cross-Domain Machine Generated Text Detection Challenge, GenAIDetect.
- Liang et al., GPT detectors are biased against non-native English writers, Patterns.