A private review of the auditMalin repository recorded 110 passing tests, and the repository checks it named were green. The same review found a seam, a place where two components meet, that those narrower checks had missed: the FastAPI-to-ADK integration path could call asyncio.run() inside an already active event loop. Python does not allow that call. asyncio.run() raises a RuntimeError when another event loop is running in the same thread.
This was a review finding, not evidence of harm in a live system. A later attributable regression test exercised that API-to-runner seam directly. Green checks were not proof that the code was correct, and none of them crossed the boundary where the failure lived.
I still prompt. I stopped treating the prompt as the thing that makes the result reliable. The prompt starts a run and states the intent. The engineering work is what goes around the agent, which can give a different answer each time it runs: project rules it can read, checks it can run, review criteria, and saved state that a failed run can be recovered from.
In this workflow, confidence is not one of the conditions for accepting a change. Three questions direct the search for evidence instead. Below, a “sensor” is any check that can flag a bad change. The questions are which sensor can produce a counterexample, whether that sensor reaches the seam where the failure would live, and which release check, outside the agent, still applies after the agent finishes its turn.
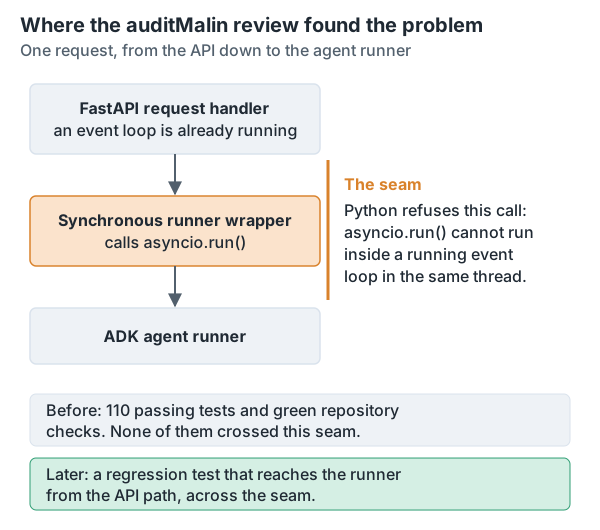
Figure 1. The seam in the auditMalin review, and the regression test that later crossed it.
A small retry function with two hidden bugs
The auditMalin code is private, so the rest of the argument uses a small function anyone can run. A retry delay doubles on each attempt until it reaches a cap:
function retryDelay(attempt, cap = 8) {
  return Math.min(2 ** attempt, cap);
}

for (let attempt = 0; attempt <= 10; attempt += 1) {
  console.log(attempt, retryDelay(attempt));
}
Save that as retry-delay.mjs and run it with Node. Attempts 0, 1, and 2 give 1, 2, and 4. These are easy examples to write first: short, familiar, and all below the cap. They are also weak evidence, because two plausible bugs give the same three answers.
A mutant is a deliberately broken copy of the function. I use two:
- The no-cap mutant is
2 ** attempt. It forgets the upper bound. - The cap-minus-one mutant is
Math.min(2 ** attempt, cap - 1). It gets the bound wrong by one.
With cap = 8, both mutants return 1, 2 and 4 for the first three attempts. One step further, at attempts 3 and 4, the reference (the correct function) returns 8 and 8. The no-cap version returns 8 and 16. The cap-minus-one version returns 7 and 7. The function has not changed; only the inputs have. The inputs now reach the part of the behavior where the three versions differ.
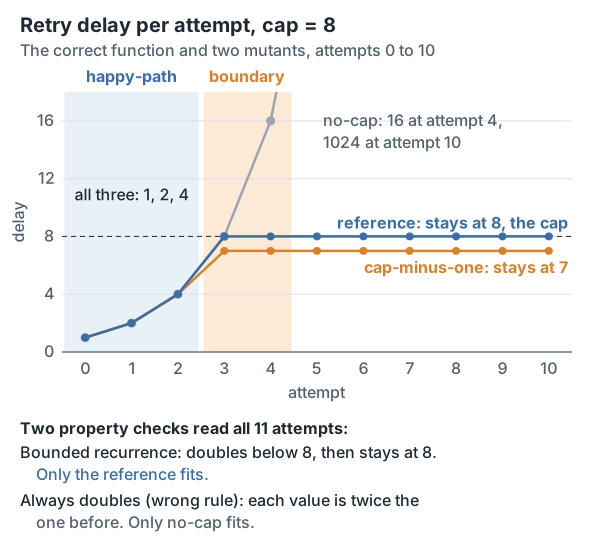
Figure 2. The three versions agree on the happy-path examples and split at the cap. The always-doubles oracle fits the wrong line: a false rejection of the reference and a false acceptance of no-cap.
An example checks one input. A property checks a rule over a whole range of inputs. For attempts 0 through 10, a useful property says three things: the output stays in [1, 8], it doubles while the previous output is below 8, and it stays at 8 after that. This is a bounded recurrence: each output is defined from the one before, under a ceiling. It rejects both mutants on that range.
A property can look rigorous and still state the wrong rule. Suppose I write “every output is twice the one before”. It covers the whole range and compares neighboring outputs, so it looks stronger than three examples. But it has dropped the cap from the oracle, the rule that decides which outputs are correct. From attempt 3 on, it rejects exactly the behavior the function is supposed to have.
The experiment is frozen so it can be rerun exactly. It runs four sensors against the reference and the two mutants. pass means the sensor accepts that version; reject means it flags it.
| Sensor | Reference | No-cap | Cap-minus-one |
|---|---|---|---|
| Happy-path examples | pass | pass | pass |
| Boundary checks | pass | reject | reject |
| Valid bounded recurrence | pass | reject | reject |
| Invalid always-doubles property | reject | pass | reject |
The always-doubles oracle falsely rejects the correct reference and falsely accepts the uncapped mutant. It checks all 11 attempts, but the rule it checks is wrong.
Goodenough and Gerhart’s early theory of test-data selection showed that familiar structural coverage criteria (statement, predicate and path coverage) are not generally sufficient for reliable testing. Barr and colleagues call the deeper difficulty the oracle problem. Inputs make a program produce observations; an oracle decides whether those observations are acceptable. QuickCheck showed how properties written as code could be checked over generated inputs, but the property still has to express the intended behavior. Generated inputs only help if the property states the right rule.
The acceptance rule
The event-loop seam and the retry mutants have the same shape. A proposed change passes some checks. Then a named counterexample shows that the current sensors did not cover a behavior that mattered. The change goes back for repair with that counterexample attached.
Written down, the acceptance rule is:
accept(p_t) = spec(p_t) ∧ focused_tests(p_t) ∧ integration_tests(p_t) ∧ fresh_review(p_t)

latest_counterexample = api_runner_inside_active_loop
p_(t+1) = repair(p_t, latest_counterexample)
p_t is the proposed patch at turn t. ∧ means “and”: all four terms must hold. Each term is a yes-or-no check on that patch and the repository state it applies to:
specchecks the stated behavior and what is explicitly excluded.focused_testsgives fast local evidence around the change.integration_testscrosses the real boundary. In the running example, that is the path from the API into the runner while an event loop is active.fresh_reviewlooks for contradictions, missing cases and unsupported claims, once the patch and its test evidence exist.
One false term returns a counterexample instead of an acceptance. The counterexample needs a name. Feedback like “try again” carries little information. “api_runner_inside_active_loop failed because the synchronous wrapper entered an active loop” names a reproduction. It can become a regression test, be rerun, and outlive the chat session.
Written down, the rule records why a patch was accepted and which term failed.
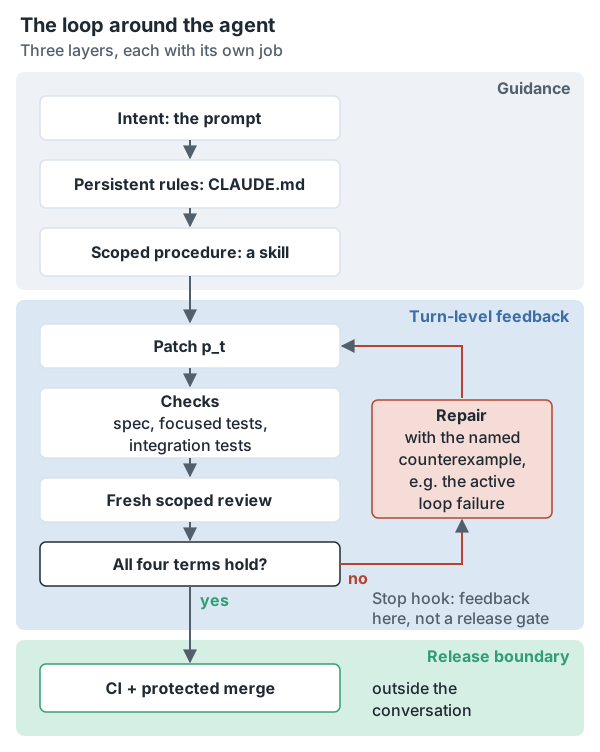
Figure 3. Each rejection sends named feedback back to repair. CI and protected merge form the release boundary, outside the conversation, so the agent accepting its own work is not permission to merge.
Three layers: guidance, feedback, release
Figure 3 groups the loop into three layers. Each has a different job.
Guidance. Repository guidance means CLAUDE.md, imported rules, and skills (reusable procedures whose full content loads when invoked). It tells the agent how the codebase is organized, which commands are authoritative, what evidence is allowed, and which procedure applies. Guidance shapes the agent’s choices, but it is context, and nothing enforces it.
Feedback. Turn-level feedback means tests and hooks. A failing focused test gives a concrete counterexample while the work is in progress. A hook runs a fixed command at a chosen point in Claude Code’s lifecycle, such as when Claude stops, and can feed a failure back into the same turn. These controls sit close to the agent and give fast repair.
Release. The release boundary is CI plus a protected merge policy. It checks the committed code, outside the agent’s own decision to stop. A local hook can be skipped, misconfigured, or cut off by a liveness rule (a cap on how many times in a row it may block). Protected merging is where required checks become a condition for merging the patch.
Each layer relies on the next: a short rule can name make test. The test encodes the behavior. CI runs it in a clean environment. Protected merge refuses a result that lacks the required status. A skill can describe how to review evidence, while a hook makes sure a must-run command actually runs at the chosen point.
Loading the rules into Claude Code
The frozen auditMalin evidence for this article tracks AGENTS.md but no CLAUDE.md. When that evidence was recorded, in August 2026, the official Claude Code documentation described CLAUDE.md as project memory, and Claude Code did not automatically load AGENTS.md just because another agent convention uses that filename.
The proposed bridge was one line:
@AGENTS.mdPut it in the relevant CLAUDE.md, start a fresh session, and run /context to check that the import appears. The check matters because a file named in a document is not necessarily a file the session loaded.
Claude Code has changed since. Version 2.1.277, released on 18 September 2026, added AGENTS.md support: in a project with no CLAUDE.md, Claude Code reads AGENTS.md instead. The documentation still gives the @AGENTS.md import for a project that also has a CLAUDE.md, and for sessions that cannot load AGENTS.md directly. The /context check applies either way: the documentation says to run it and look at the list under “Memory files”.
Keep the imported rules short and navigational: name the source of truth, the required commands, the privacy boundaries, and where the longer procedures live. The official guidance separates persistent project instructions from skills, whose full content enters context when invoked. That split keeps the always-loaded guidance small and puts longer, task-specific steps in a procedure the agent can find.
Even when it is loaded correctly, CLAUDE.md is still context. The memory documentation says Claude treats these files “as context, not enforced configuration”. A sentence saying “always run the checks” may influence behavior. A test command or a hook produces evidence you can see.
A proposed Stop hook
The hook below is a proposed addition. It is not currently deployed in the frozen auditMalin evidence. It is kept small so its control flow is easy to follow. Claude Code passes hook input as JSON on stdin, and the sample runs an existing repository command instead of copying that command’s logic into the hook.
import { readFileSync } from "node:fs";
import { spawnSync } from "node:child_process";

const input = JSON.parse(readFileSync(0, "utf8"));

if (input.stop_hook_active) {
  process.exit(0);
}

const result = spawnSync("make", ["check"], { stdio: "inherit" });
if (result.status === 0) {
  process.exit(0);
}

console.error("make check failed; repair the reported counterexample");
process.exit(2);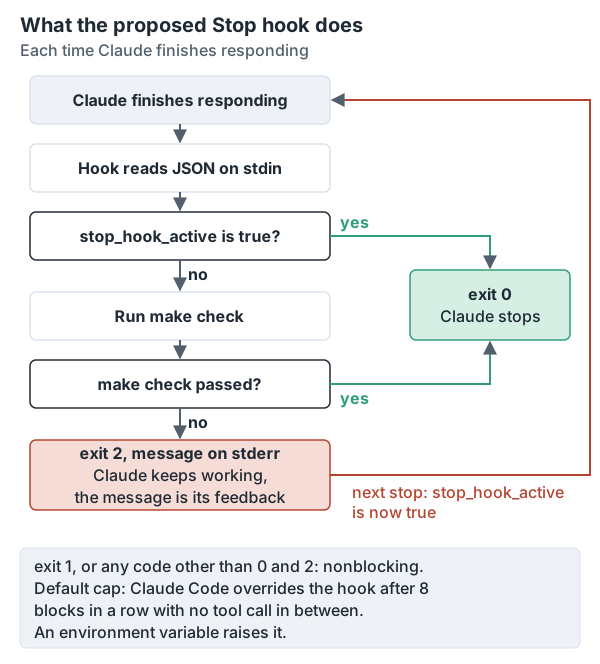
Figure 4. The proposed hook, one branch at a time. A failing check gets one more pass of work, then the hook lets Claude stop.
For a Stop hook, exit code 2 tells Claude Code to block stopping and to use stderr as feedback for continued work. Any other nonzero exit, including exit code 1, is nonblocking. So a hook that returns 1 by mistake after a failed command reports a hook error but does not continue the agent’s turn.
The stop_hook_active field needs its own branch. Claude Code sets it to true when the turn is already continuing because a Stop hook blocked. stop_hook_active does not guard against recursion by itself: the hook must check it and allow stopping while it is set. Otherwise the same failing check can keep blocking its own continuation. In the sample, that check means a failing make check gets one repair pass, and the next stop is allowed.
Stop fires after the main agent finishes responding. It is not a signal that the task is actually complete. Claude Code overrides the hook after eight consecutive blocks by default; the current hooks guide counts blocks in a row with no tool call from Claude in between. CLAUDE_CODE_STOP_HOOK_BLOCK_CAP can raise that cap. That configurable liveness cap limits how long turn-level feedback may continue. It does not guarantee eight retries, and it does not change the separate release boundary.
The sample is turn-level feedback. CI plus protected merge remains the release gate. Before enabling a real hook, check that its command fits the event’s runtime budget, keeps its diagnostic output, and has been tested with controlled JSON inputs for the inactive, active, passing and failing cases.
Fresh review
A fresh review with a narrow scope can catch a contradiction that the author and the focused tests share. It is one more sensor. Its errors can match the author’s, so it is not a statistically independent oracle and its verdict is not a vote. “Fresh” means the reviewer receives the current patch, requirements and test evidence after implementation. It does not mean the reviewer’s errors are uncorrelated with the worker’s.
Knight and Leveson’s journal article is useful only within its recorded scope. The experiment’s details come from the technical report UVA TR-85-11: for one specification, 27 versions were prepared independently at two universities and run against one million test cases. Coincident failures exceeded what the independence model predicted. That one experiment is not a universal law about diverse software. It is even less a reason to treat two language-model reviews as independent because their prompts or sessions differ.
Kim and colleagues measure correlated errors in language models on specific tasks and datasets. The practical step is to vary the kinds of evidence. A deterministic boundary test, a type checker, a browser assertion and a scoped semantic review fail for different immediate reasons. An LLM review can still help, but two LLM verdicts should not be combined as though they were independent trials.
Give the reviewer one narrow question. “Review this patch” invites taste and summaries. “Check whether the FastAPI request path can invoke the synchronous runner from an active loop; cite the line and supply a reproducer” asks for a result that can be checked and shown wrong. When that result exists, turn it into the cheapest lasting check that keeps the behavior covered. The later API-to-runner regression test is worth more than remembering that a reviewer once noticed the seam.
Replay capsule
A long agent run is hard to reconstruct from its transcript. A replay capsule is a saved record of the state a run depended on. Suppose api_runner_inside_active_loop fails during repair. The capsule for that run pins six things, shown in Figure 5, from the Git commit and diff to the output hash. Two of them are specific to this failure: the exact regression-test invocation used for that run, and the fixture (the prepared test setup) in which a FastAPI request reaches the synchronous runner from an active event loop.
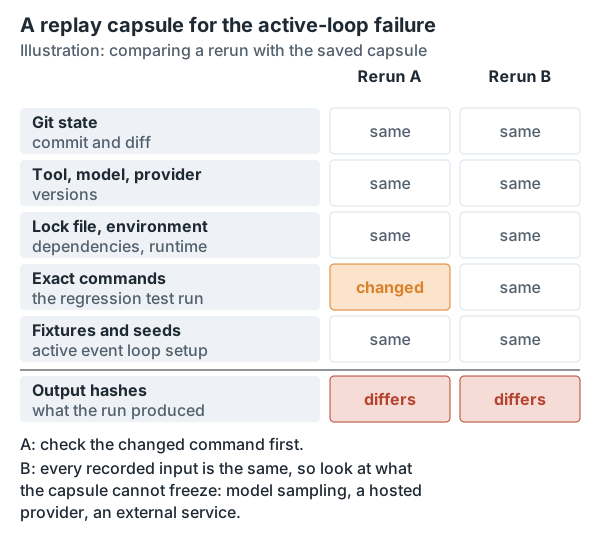
Figure 5. An illustration, not a recorded run: comparing a rerun with the saved capsule shows where to look first. It helps diagnosis; it cannot make a hosted model’s rerun byte-identical.
The next pass can then tell whether the code, the invocation, the fixture, the executor or the generated result changed, instead of guessing from the earlier response. The output hash answers one concrete question. If the same recorded Git state, command and active-event-loop fixture produce a different hash, the divergence is known before anyone compares explanations. The hash does not identify the cause. It narrows the next check to the recorded inputs and the executor.
Claude Code and Git cover parts of this. A saved conversation can resume through Claude Code’s documented session controls. Changes made with Claude’s editing tools can be rewound through checkpointing. Git records software state across commits and diffs. Checkpointing is not version control: it does not replace named commits, reviewable diffs, durable tests or protected history. None of these controls freezes hosted model or provider execution, so the capsule improves diagnosis but does not promise identical replay.
Limits
- One review finding. The private review’s 110-test gate and event-loop seam show one missed integration boundary in one repository. They do not show user impact, and the regression test that followed does not show that the rest of the repository is correct.
- The acceptance rule passes what its terms miss. It makes evidence inspectable, but it does not prove correctness. A missing requirement, or an invalid oracle like always-doubles, can get through all four terms.
- The retry table is tiny on purpose. Its 12 outcomes are exact only for the two named mutants and this frozen input domain: one reference,
cap = 8, attempts 0 through 10. It is not a Claude Code benchmark and not a general mutation score. It does not estimate an agent’s accuracy or how well a test suite would catch bugs it has never seen. - Claude Code changes. The behavior described here comes from Claude Code’s documentation, read in August 2026 and checked again in October 2026.
AGENTS.mdloading changed between those two dates. Check the current hooks and memory pages before copying the hook or the import.
Checklist
- Put short guidance in
CLAUDE.md, import existing rules explicitly, and check what loaded with/context. Move repeated procedures into a versioned skill. - Write the acceptance rule before implementing. Name the counterexample that each false term returns.
- Aim focused tests at an observable defect and integration tests at the boundary where the code is consumed. Test the oracle itself against a correct implementation and plausible mutants.
- Parse and test the Stop hook’s input, including
stop_hook_activeand exit-2 feedback. Keep CI plus protected merge as the release boundary. - Give fresh review one narrow question whose answer can be shown wrong. Turn a lasting finding into an executable check when practical.
- Save a replay capsule before a long run. Compare its output hash before diagnosing prose or model behavior.
Primary sources
- Anthropic, “How Claude remembers your project”, especially the distinction between
CLAUDE.mdinstructions and enforced configuration, and itsAGENTS.mdsection. - Anthropic, “Automate actions with hooks” and the hooks reference, for stdin input, Stop timing, exit behavior,
stop_hook_active, and the default/configurable consecutive-block cap. - Anthropic, “Best practices for Claude Code”, for concise project instructions, hooks, and reusable skills.
- Anthropic, “Manage sessions”, “Checkpointing”, and “Extend Claude with skills”, for the recovery and procedure features used above.
- Anthropic, Claude Code changelog, version 2.1.277, for the added
AGENTS.mdsupport; release date from the npm registry. - Python documentation,
asyncio.run(), for the rule that it cannot be called when another event loop is running in the same thread. - J. B. Goodenough and S. L. Gerhart, “Toward a theory of test data selection” (1975), on the limits of familiar test-selection criteria.
- E. T. Barr, M. Harman, P. McMinn, M. Shahbaz, and S. Yoo, “The Oracle Problem in Software Testing: A Survey” (2015), on the difference between producing observations and judging them.
- K. Claessen and J. Hughes, “QuickCheck: A Lightweight Tool for Random Testing of Haskell Programs” (2000), on executable properties and generated test data.
- J. C. Knight and N. G. Leveson, “An Experimental Evaluation of the Assumption of Independence in Multiversion Programming” (1986), cited for the journal citation identity only.
- University of Virginia, UVA TR-85-11, whose registered abstract describes the experiment: 27 versions of one specification, prepared at two universities and exercised with one million tests, with coincident failures exceeding the independence model’s expectation. This report record is separate from the journal citation above.
- E. Kim et al., “Correlated Errors in Large Language Models” (2025), used for its task- and dataset-specific correlated-error findings, not as a universal rate.