Aeon’s PeriodogramTransformer turns each time series into a periodogram: how strong each frequency is in the series, read from a Fourier transform. Series of equal length fit in one 3-D array. An unequal-length collection, where the series differ in length, comes as a list of arrays instead. With padding turned on, the transformer pads each series before computing its periodogram. The list and the array go through different preprocessing code to get there.
That split once made PeriodogramTransformer(pad_series=True, pad_with="mean") reject a valid unequal-length collection with this error:
ValueError: unsupported keyword arguments for mode 'mean': {'constant_values'}
The caller chose the mean padding mode. The argument NumPy rejected, constant_values, belongs to a different mode, constant.
When a tool accepts more than one input type, each input type has to give the same result under each parameter mode, and the tests have to check the two together.
Setup
A 3-D array has a shape such as (cases, channels, time), so every series in it has the same length. You cannot stack series of different lengths into one ordinary 3-D array until their time axes agree. That is why the transformer also accepts a list.
With pad_series=True, each series is padded to its own next power of two before its periodogram is taken. The transformer keeps half of each spectrum. The running example uses two series with two channels each:
x0has 20 time points. It pads to 32, and its periodogram is 16 values wide.x1has 33 time points. It pads to 64, and its periodogram is 32 values wide.
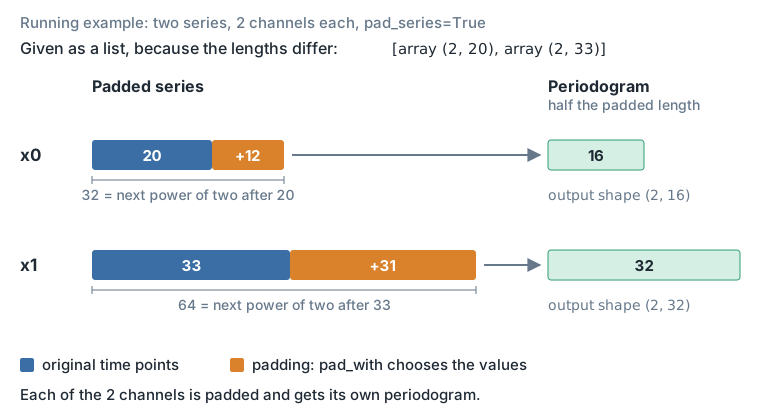
Figure 1. Each series is padded to its own next power of two, and the periodogram keeps half of that length.
pad_with chooses what goes into the new positions. It is passed on to NumPy’s np.pad as the mode. The default, constant, fills them with a fixed value. mean, the mode in this post, fills them with the series mean.
Reproducing the error
This example keeps only the public behavior that matters: two fixed unequal-length inputs, the non-default mean mode, two shape checks, and one value comparison of x0 against the 3-D path. It runs against the merged source revision named in “The fix” below. It is not a statement about a packaged Aeon release: the latest release checked at the research cutoff came out before that merge.
import numpy as np
from aeon.transformations.collection import PeriodogramTransformer

X = [
    np.random.RandomState(0).random((2, 20)),
    np.random.RandomState(1).random((2, 33)),
]
transformer = PeriodogramTransformer(pad_series=True, pad_with="mean")
Xt_list = transformer.fit_transform(X)
assert Xt_list[0].shape == (2, 16)
assert Xt_list[1].shape == (2, 32)
Xt_array = transformer.fit_transform(X[0][None, ...])
np.testing.assert_allclose(Xt_list[0], Xt_array[0])
Before the fix, the list path stops at transformer.fit_transform(X) with the ValueError above. After the fix, both list output shapes are (2, 16) and (2, 32), as asserted.
What each part of the script does:
- The seeds only freeze the values, so the checks give the same answer every time.
- The two shape checks test the padding arithmetic from the setup.
- The last line checks that
x0gets the same periodogram whether it arrives in a list next to a series of a different length, or alone in a 3-D array.
Only Xt_list[0] is compared numerically, with Xt_array[0]. The second list element gets a shape check, not a second value comparison against the 3-D path.
Why the list branch failed
Inside the transformer, the list and the 3-D array take separate routing and padding code before the shared periodogram step. Call them the list branch and the 3-D branch. Each one builds a set of keyword arguments and hands them to np.pad.
What np.pad accepts depends on the mode. The official numpy.pad documentation gives the signature as numpy.pad(array, pad_width, mode='constant', **kwargs). The **kwargs part lets the call take any keyword argument, but which names are allowed depends on mode:
| Mode | Optional keyword it accepts |
|---|---|
constant | constant_values |
mean, median, maximum, minimum | stat_length |
linear_ramp | end_values |
reflect, symmetric | reflect_type |
So constant_values is accepted only in constant mode. A mean call may carry mode and, optionally, stat_length, but not constant_values.
The two branches built their keywords differently:
- The 3-D branch built them conditionally. For
constant, it passedmodeandconstant_values. Formean, onlymode. - The list branch, before the fix, had no such condition. It sent
constant_valueswhatever the mode, though nothing in ameanrequest asks for a constant fill value. Formean, it built a call equivalent tonp.pad(..., mode="mean", constant_values=0).
NumPy read the mode, checked which extra keywords that mode allows, and rejected constant_values. So the two branches disagreed before the Fourier step even began.
The input values do not trigger this error. Neither do the channel count or the output width. The call is invalid before any padding happens: the mode says “fill with a statistic”, while the extra keyword says “fill with this constant”. The error names the unwanted argument directly, instead of showing up later as a numerical problem. No statistic computed from X can make constant_values relevant to mean, so changing the arrays, the tolerances or the Fourier check would leave the bad call in place. The fix belongs where the keywords are assembled.
The default constant mode worked with the extra keyword, because constant_values=0 means something for that mode. So the list path passed with the default. That passing case told you nothing about mean, reflect, or any other mode with different keywords. So test each input type with each padding mode.
The fix
An Aeon contribution made the list branch build its padding keywords conditionally, as the 3-D branch already did, and added a regression test. A maintainer reviewed and merged it, so it makes a practical case study of this branch-parity rule.
At the point where the keywords are built, the fix is two lines of logic:
kwargs = {"mode": self.pad_with}
if self.pad_with == "constant": kwargs["constant_values"] = self.constant_value
The first line is the shared part. The second adds the field that only constant uses. The list branch now builds its keywords with the same rule as the 3-D branch. NumPy handles what each mode means, and never receives an argument that belongs to another mode. The fix does not add the other optional keywords (stat_length, end_values, reflect_type). The exact change and its regression test are in the immutable squash diff.
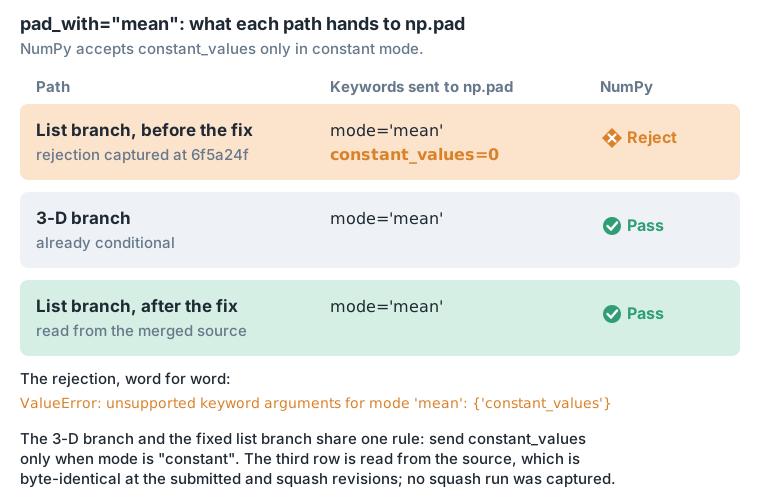
Figure 2. The fix makes the keyword conditional. Dropping the irrelevant keyword from the mean call turns the list branch from reject to pass, with the same rule the 3-D branch already used.
The pull request was merged as a squash merge, which turns it into one new commit. So there are two revisions: the submitted head 0050d4e7251ae9bbc8a2c57ebfef1ebbab502cf3 and the squash revision 8ac71e463aa7314bd1bfc05edccf3d53de1aa3a1. The submitted source and submitted test are byte-for-byte identical to the squash source and squash test. So what the merged code does can be read from its source. This post calls that the source-derived merged model. It is a reading of the source, not a captured squash run.
The regression test
The test checks one rule. Write T_list,m for the transform through the list branch with padding mode m, and T_3D,m for the transform through the 3-D branch. For the first series in a fixed pair, the test asks for:
T_list,m([x0,x1])[0] ≈ T_3D,m(x0[None,...])[0]
In words: x0 should get the same periodogram whether it goes through the list branch next to x1, or through the 3-D branch on its own. The two sides are not built the same way: the list path also transforms x1, and the 3-D side holds only x0. The comparison keeps the array, the mode and the transform fixed, and changes only the outer container. If the padding keywords differ, the left side can fail while the right side works. If both finish, the value comparison checks that going through the list did not change the periodogram of x0.
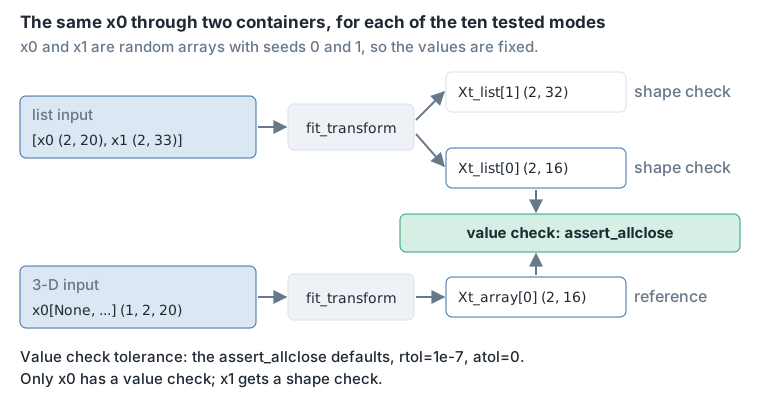
Figure 3. The test changes only the container. Both list outputs get a shape check; only x0 also gets a value check against the 3-D path.
The upstream test runs ten named modes on seeded (2, 20) and (2, 33) arrays, with the same checks as the example above. This x0-only value check is enough to expose the mismatch. It compares the values with np.testing.assert_allclose and passes no tolerance arguments. So the official assert_allclose documentation supplies the defaults: rtol=1e-7, atol=0, a relative tolerance of 1e-7 and no absolute tolerance.
The two kinds of check do different jobs:
- Shape assertions do catch the observed
meanrejection, because the failing branch returns no result to check. After the call succeeds, they still catch padding-width mistakes. - A value comparison is the stronger check once both branches return arrays of the expected shape. It catches results that look right but differ.
The test that tells the two branches apart combines a non-default mode with a value comparison against the branch that already handles that mode correctly.
A hand check with a direct DFT
A second check, independent of Aeon and NumPy, tests the reasoning. It is not another Aeon capture. It takes one channel and goes step by step:
- Start from
x0 = [1,2,3,4,5]andx1 = [1,2,3,4,5,6]. - Pad both to length eight with their mean. That gives
[1,2,3,4,5,3,3,3]and[1,2,3,4,5,6,3.5,3.5]. - Take a direct DFT, the discrete Fourier transform computed from its definition.
- Keep the first
floor(N/2)magnitudes, four of the eight.
In that model, the list spectrum of x0 and its 3-D version both come out as [24, 5.414213562373097, 1.9999999999999998, 2.585786437626905].
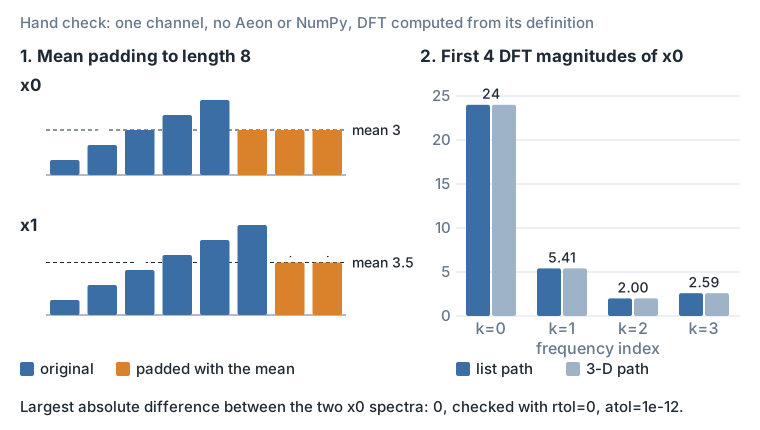
Figure 4. The hand check on a one-channel fixture. Mean padding fills each series with its own mean, and x0 gets the same spectrum through both paths.
The largest absolute difference observed for x0 is zero. That is an observed floating-point result, not a claim that the bytes are identical. The independent direct-DFT fixture uses an absolute-only threshold, rtol=0, atol=1e-12. Each tolerance stays next to its own check, so this fixture does not borrow the upstream tolerance, and the two checks are not one experiment.
Results
The captured results cover ten tested named modes, in this order: constant, mean, edge, reflect, median, linear_ramp, maximum, minimum, symmetric, and wrap. It is a limited regression table, not a list of everything NumPy’s padding accepts.
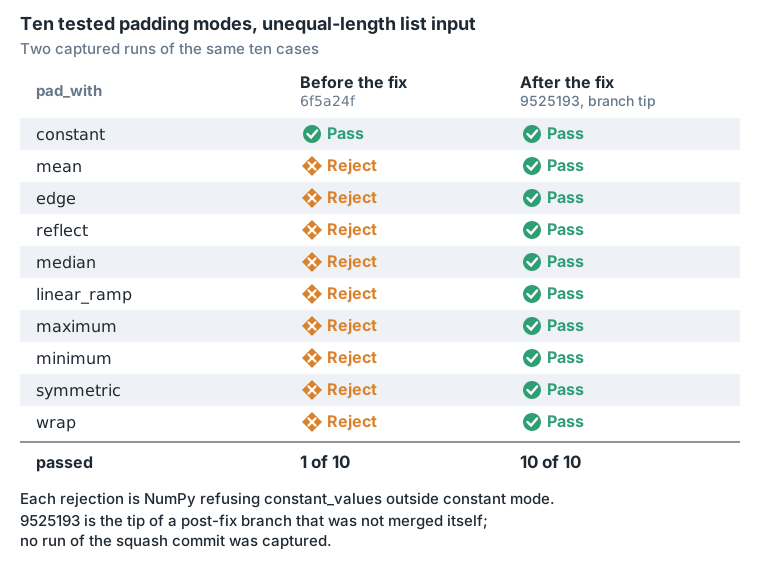
Figure 5. The captured result goes from one pass and nine rejections to ten passes across the tested modes. Each column names the commit it was captured at; neither is a run of the merged squash commit.
Captured before at 6f5a24f, the focused run of these ten cases recorded one pass and nine rejections. constant passed. Each of the other nine modes rejected the irrelevant constant_values keyword. The 9525193 branch-tip capture recorded ten passes. Both runs use the same ten modes, so one-of-ten against ten-of-ten is a like-for-like comparison.
The after column is labelled “Captured after fix”, not “merged”. Revision 9525193 is the tip of a post-fix branch that was never merged itself. The source-derived merged model agrees with its result, but that agreement does not create a captured run at the squash commit.
Limits
- Only ten modes were tested. NumPy’s documented
emptymode and callable padding are outside the captured table, so the result does not extend to NumPy’s whole padding interface. - The upstream value check covers x0 only. The second list element gets a shape check; it is not compared numerically with a separate 3-D result.
- The wider test runs do not match. The pre-fix run says
71 passed; the post-fix branch tip says80 passed, 1 skipped. Their skips differ, so these two runs support no exact difference in pass counts and no conclusion about the wider suite. - The release statement is only about dates. The v1.5.0 release was published on 2026-06-29; the squash merge followed on 2026-08-06. That chronology shows only that v1.5.0 cannot contain that later commit. It says nothing about equivalent code or a later release.
- No RISE claim. RISE (Random Interval Spectral Ensemble) is an Aeon classifier that builds trees on periodogram and autocorrelation features of random intervals. The evidence does not show that the RISE code now in Aeon’s tree reaches this unequal-length failure.
- Impact was not measured. The captures show test behavior only. There is no evidence here about production incidents, user reports, adoption, speed, or downstream accuracy.
- The direct DFT is an explanatory model. Its zero difference belongs to the fixed one-channel mean-padding fixture and its stated absolute tolerance. It is not a new NumPy or Aeon run.
Checklist
- Vary the container on its own: run the list and the 3-D input with the same
x0. - Vary the parameter mode on its own: keep the default, then add a valid non-default mode whose keywords differ.
- Pair shape checks with a behavioral oracle, a check that compares the shared sample’s values across branches.
- Write each numerical tolerance next to the check that uses it; do not carry defaults from one fixture into another.
- Inspect the keywords where the call is handed to the library, and add mode-specific ones only inside their own branch.
- Label captured output, submitted code, squash code and source-derived models as separate kinds of evidence.
The test grid is small: container × parameter mode × check. Each axis varies on its own. A default-mode shape check covers one cell. The mean list-versus-3-D value comparison covers another, and it fails exactly where the branches had diverged.
Primary sources
- Aeon, PR #3704, for who submitted it, the review, the merge, the revisions and the changed files.
- Aeon, immutable squash diff, for the conditional-keyword fix and the added regression test.
- Aeon, submitted transformer source and submitted regression test.
- Aeon, squash-pinned transformer source and squash-pinned regression test.
- Aeon, v1.5.0 release page, for the publication date, which comes before the merge.
- NumPy, official
numpy.paddocumentation, for the signature, the named modes and the keywords each mode accepts. - NumPy, official
numpy.testing.assert_allclosedocumentation, for the defaultsrtol=1e-7, atol=0that the upstream call inherits.